ALEX Intelligence Listed Property Buyer Model · Version 14.225 · System identified initial comps
Prepared for Gary C. Blackburn
· Prepared by Diane Hart Alexander, MBA, MHA, Designated Broker
This is a comparable-sales opinion of value, not a certified
appraisal. It is not a mortgage or lending document. It is produced from various data
feeds, including MLS data, county records, ALEX’s adjustment engine and
Diane’s refinements
based on a review of available property information.
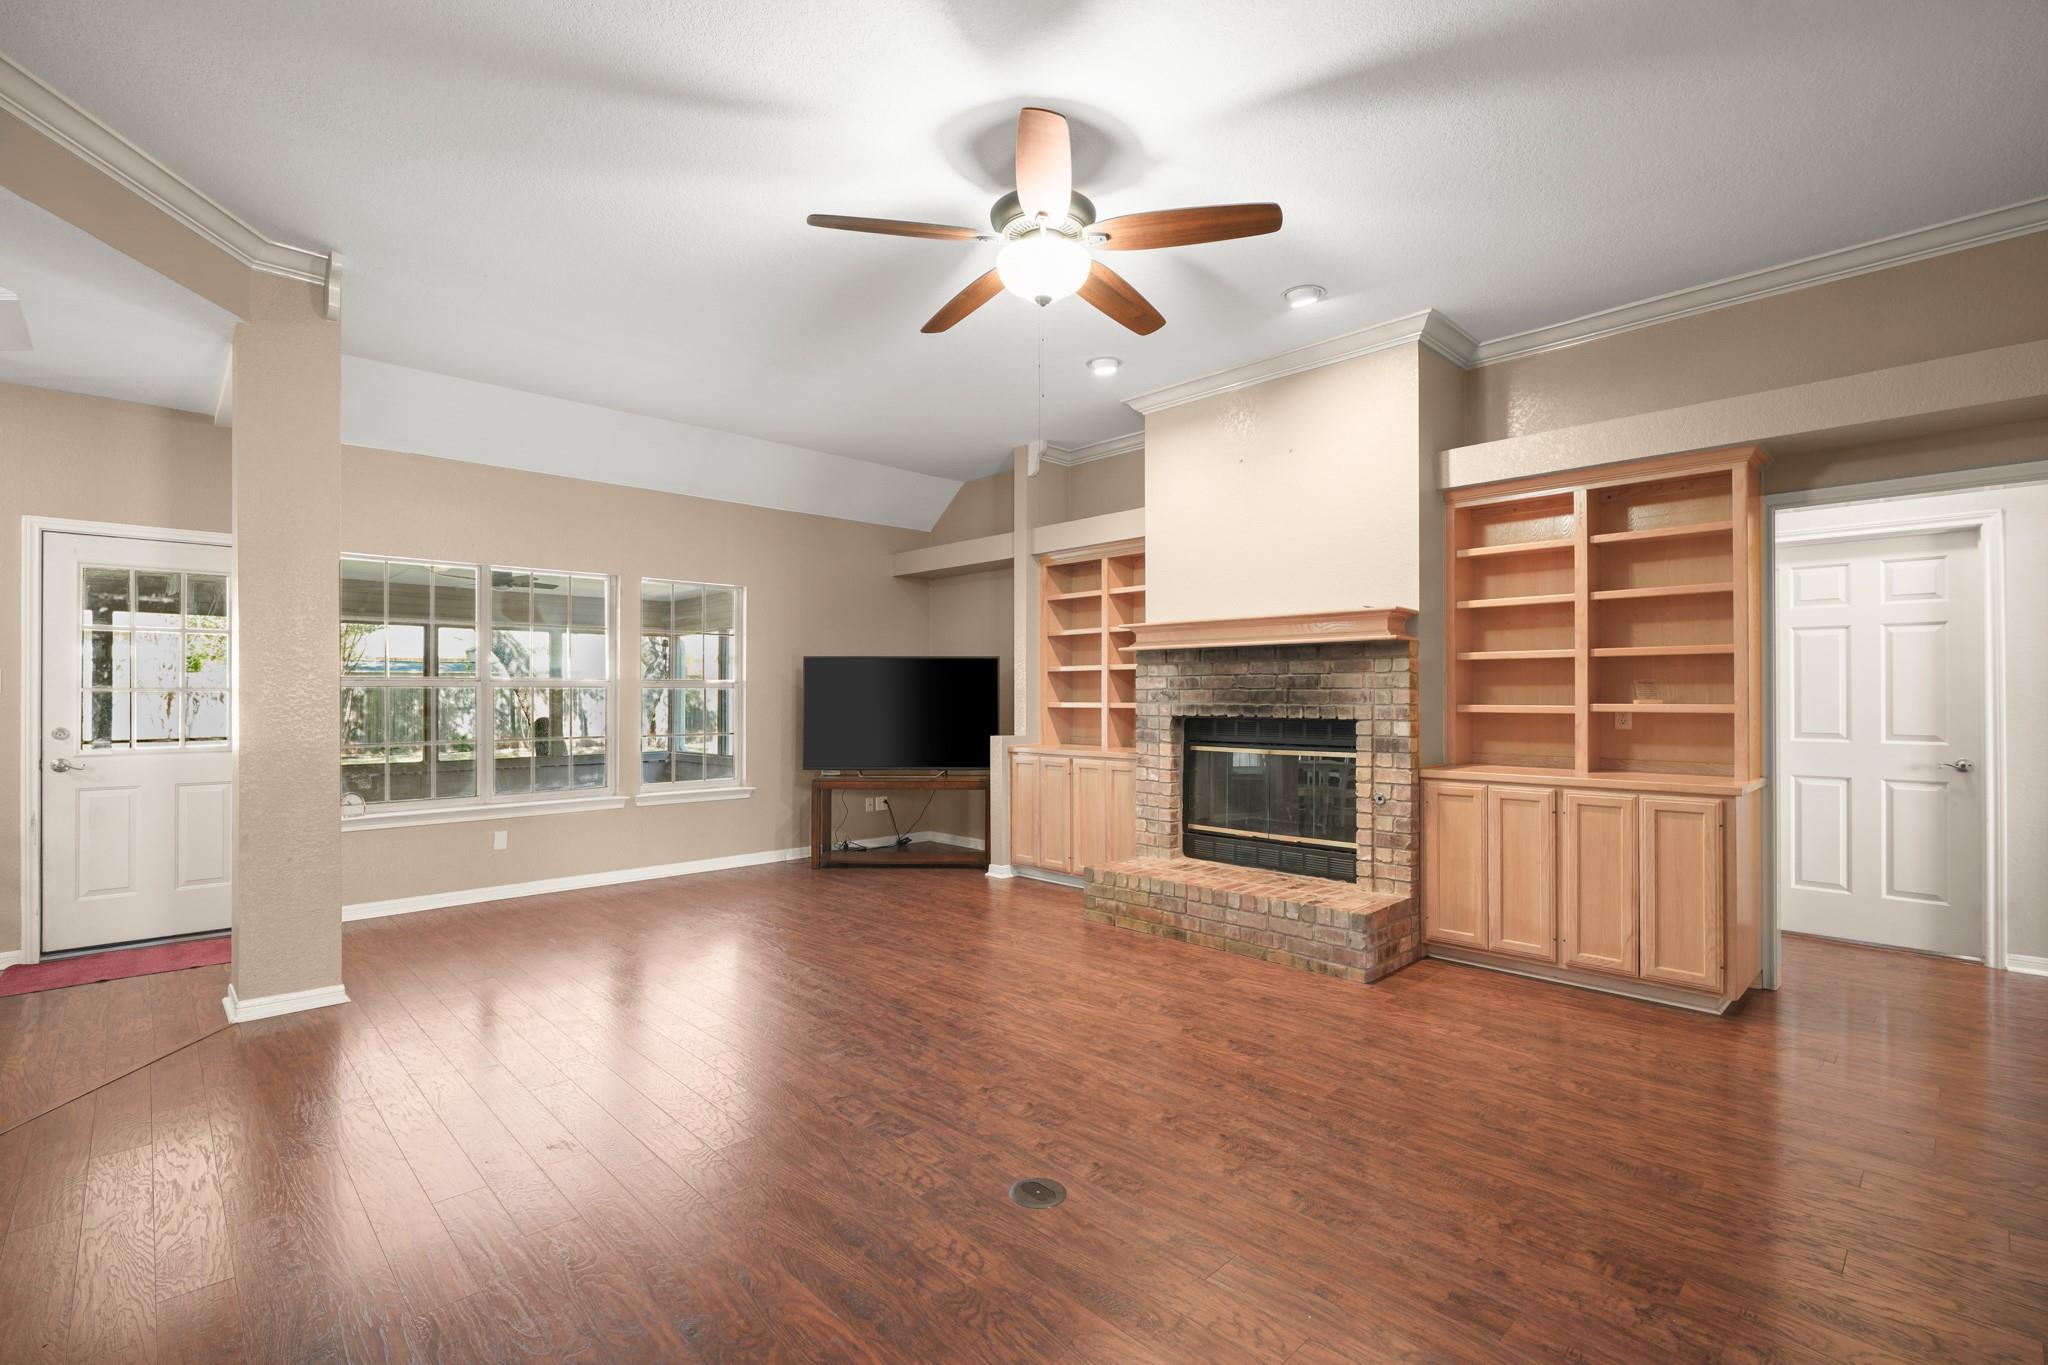
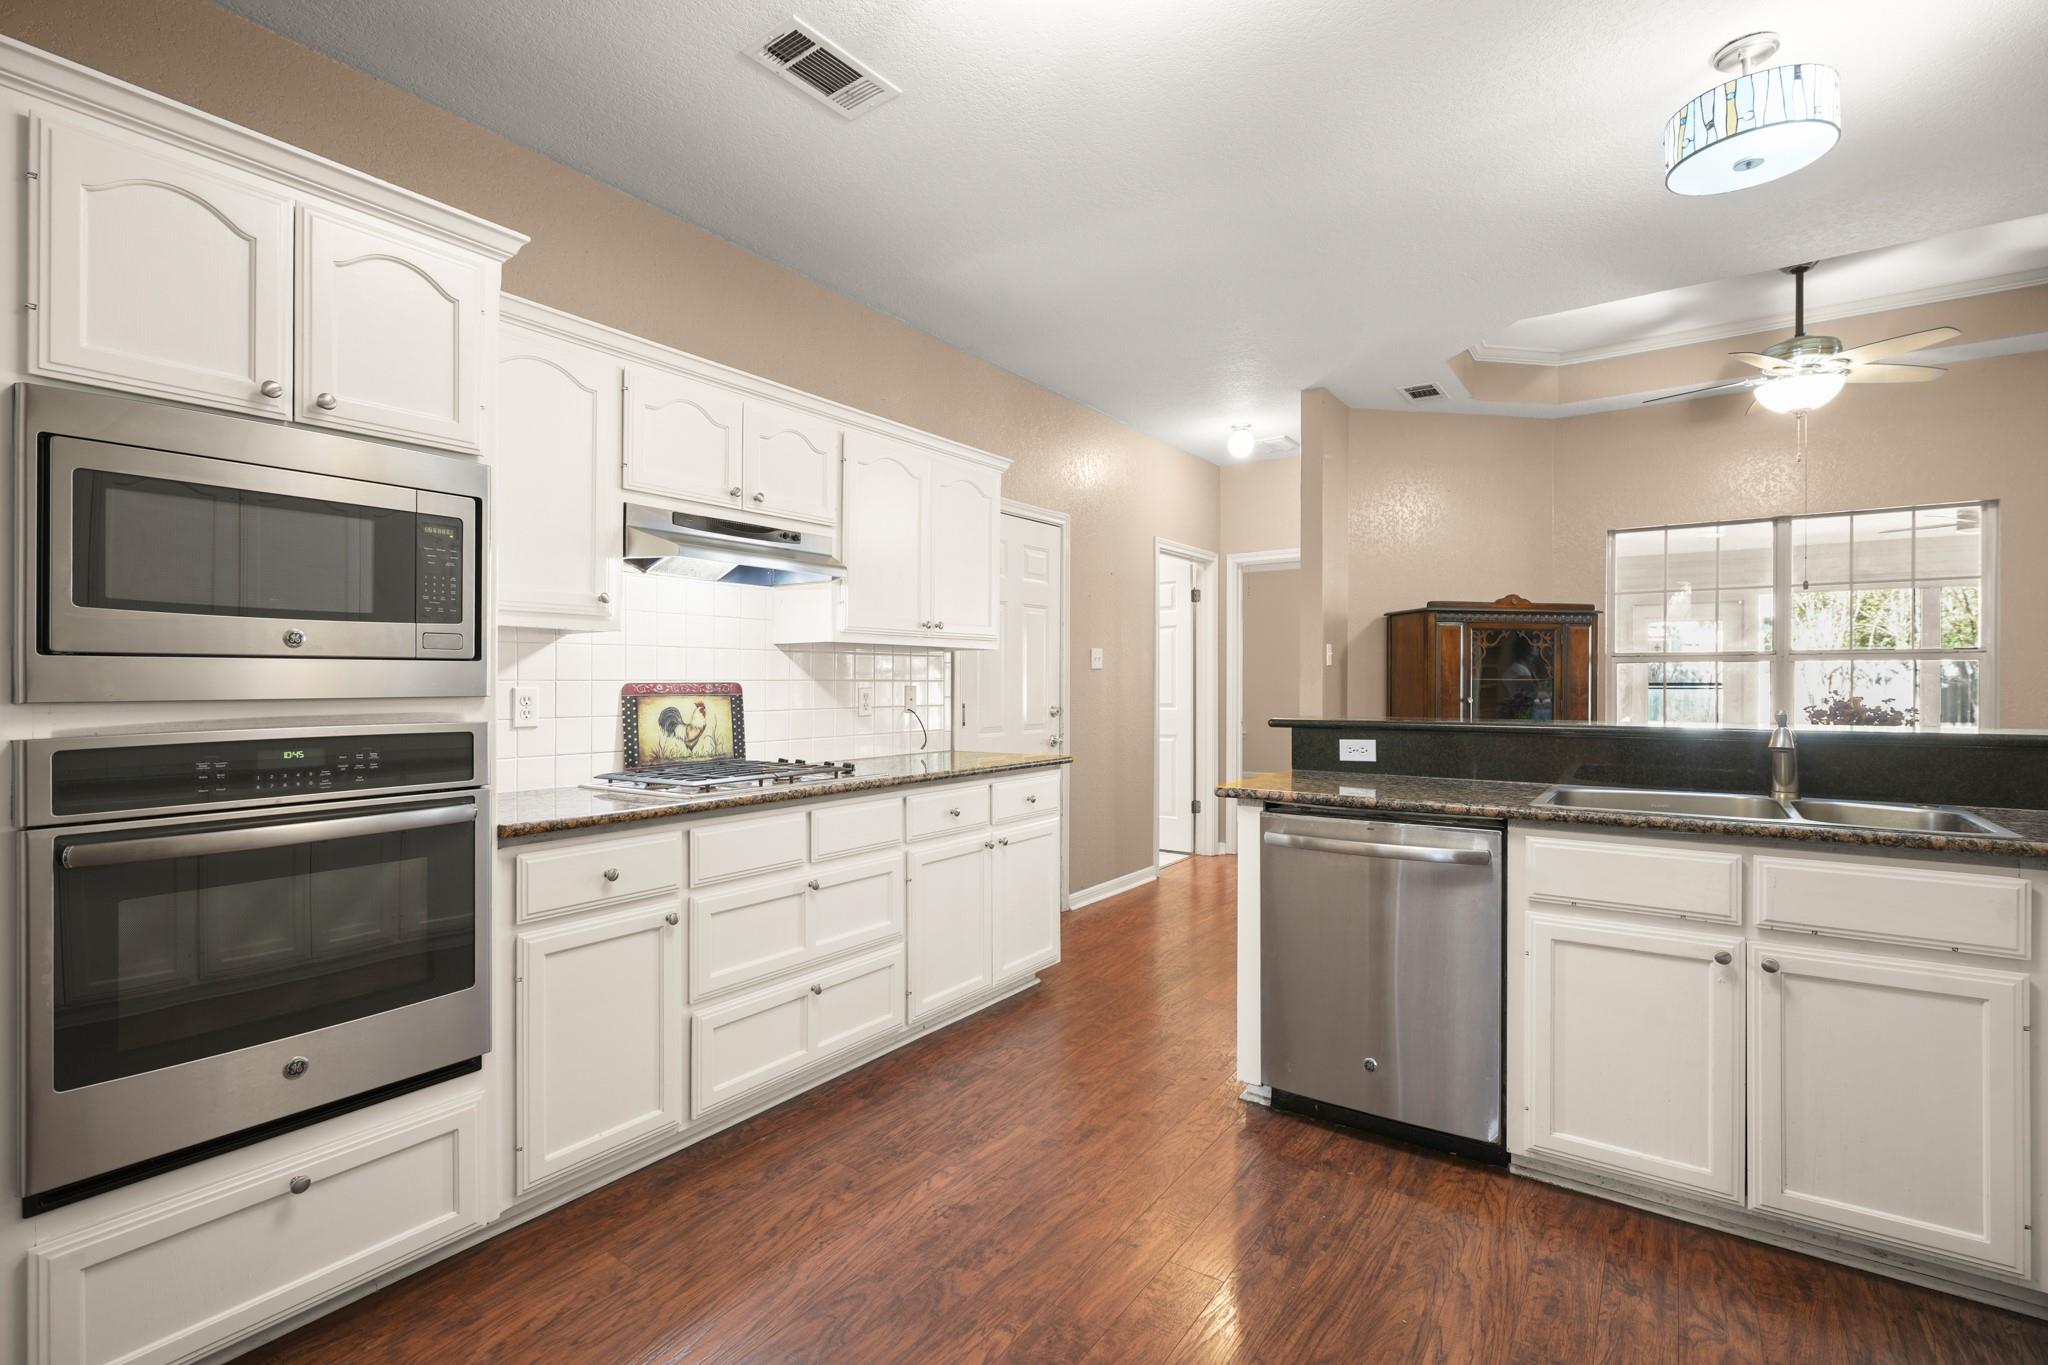
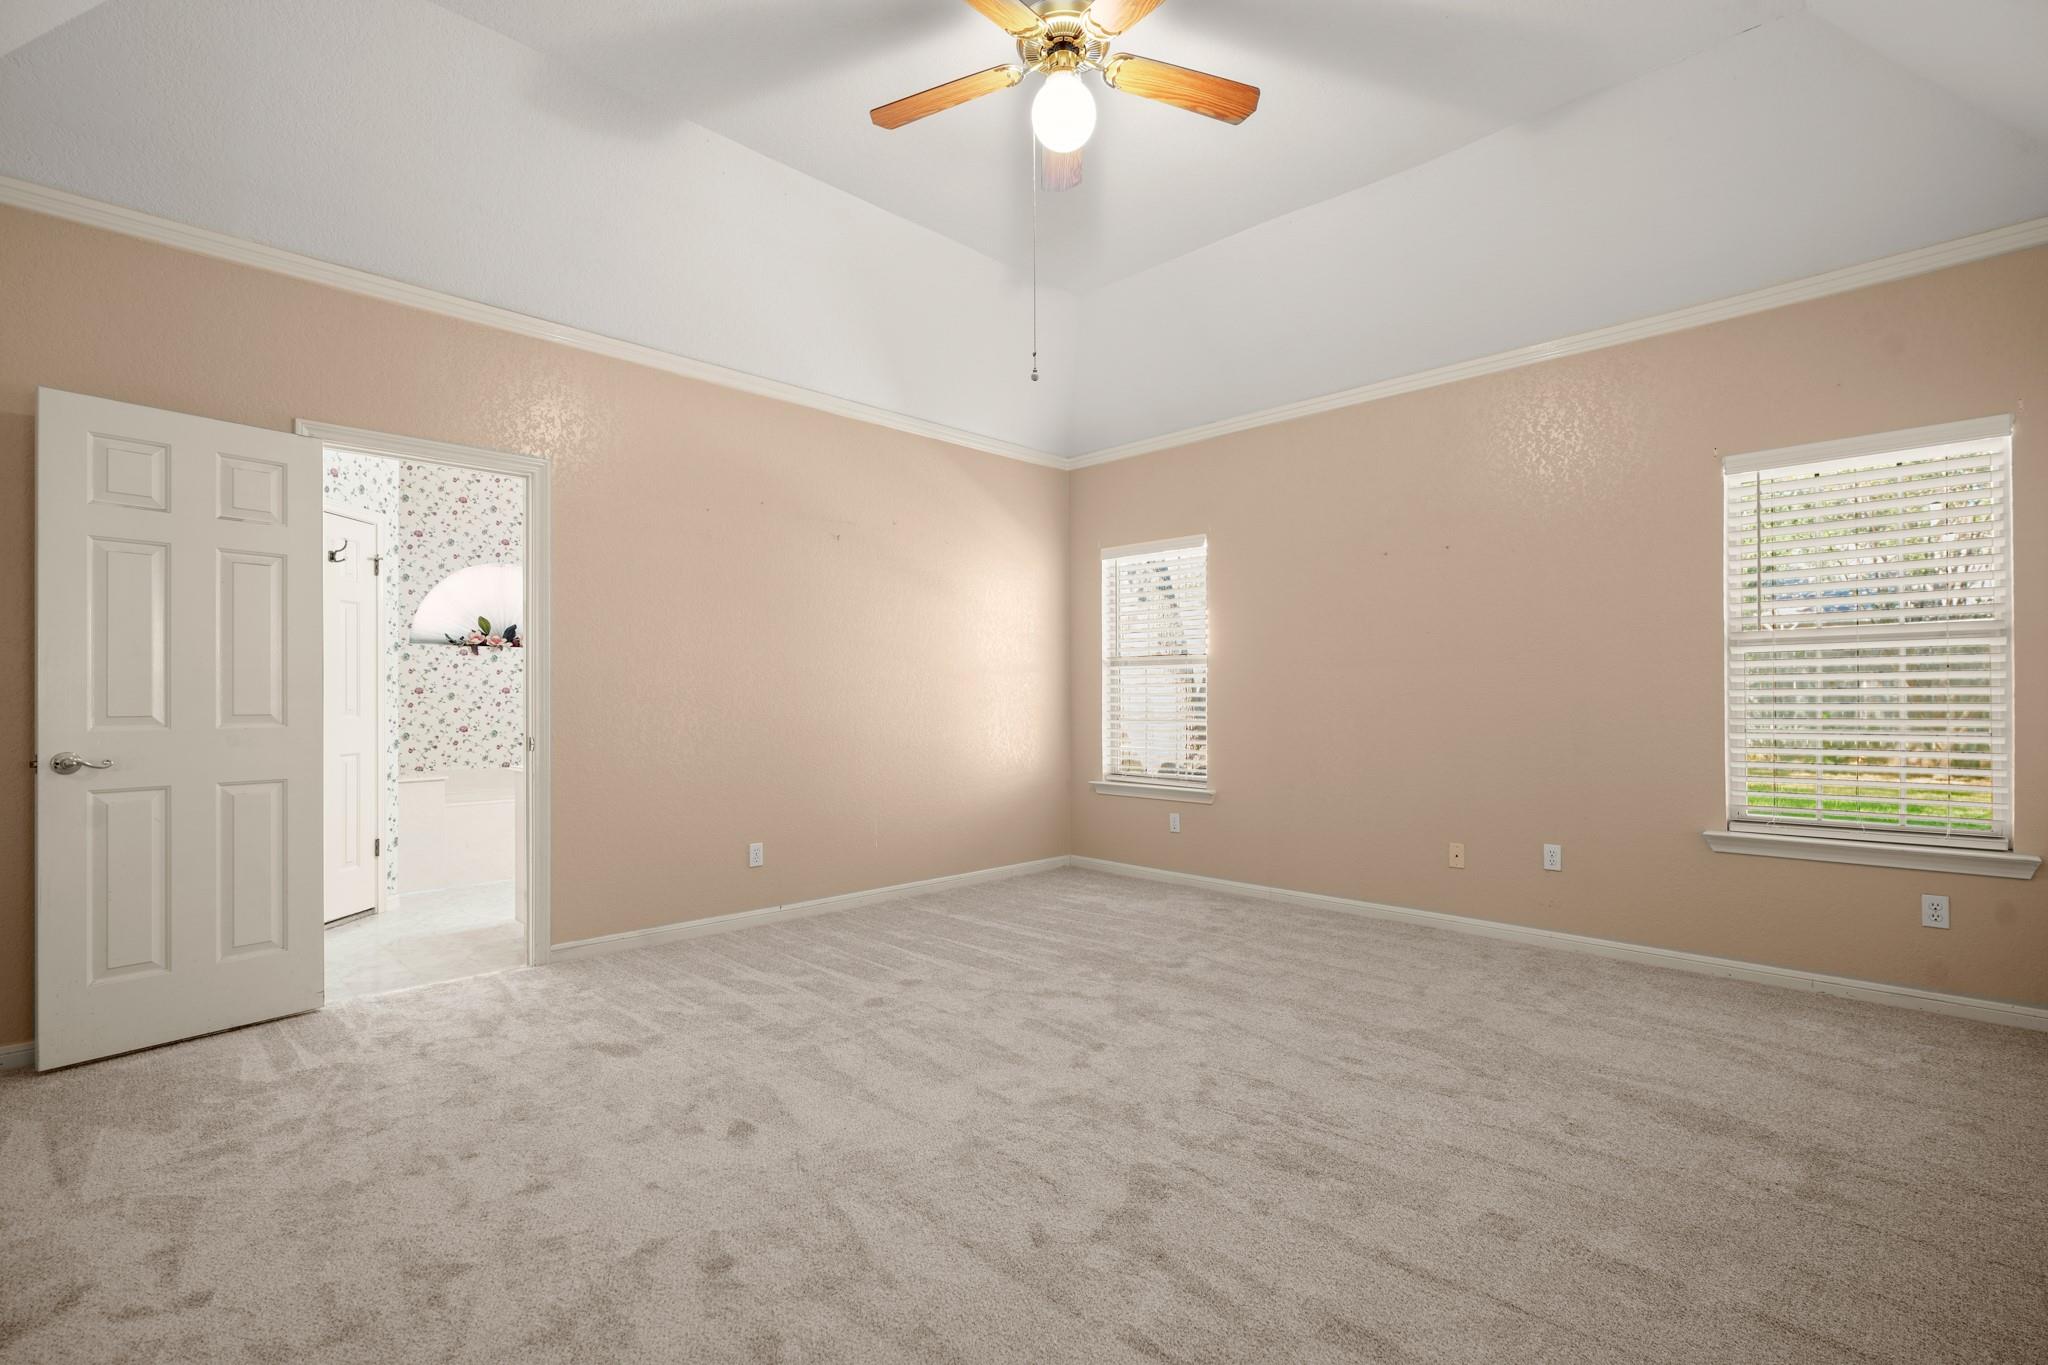
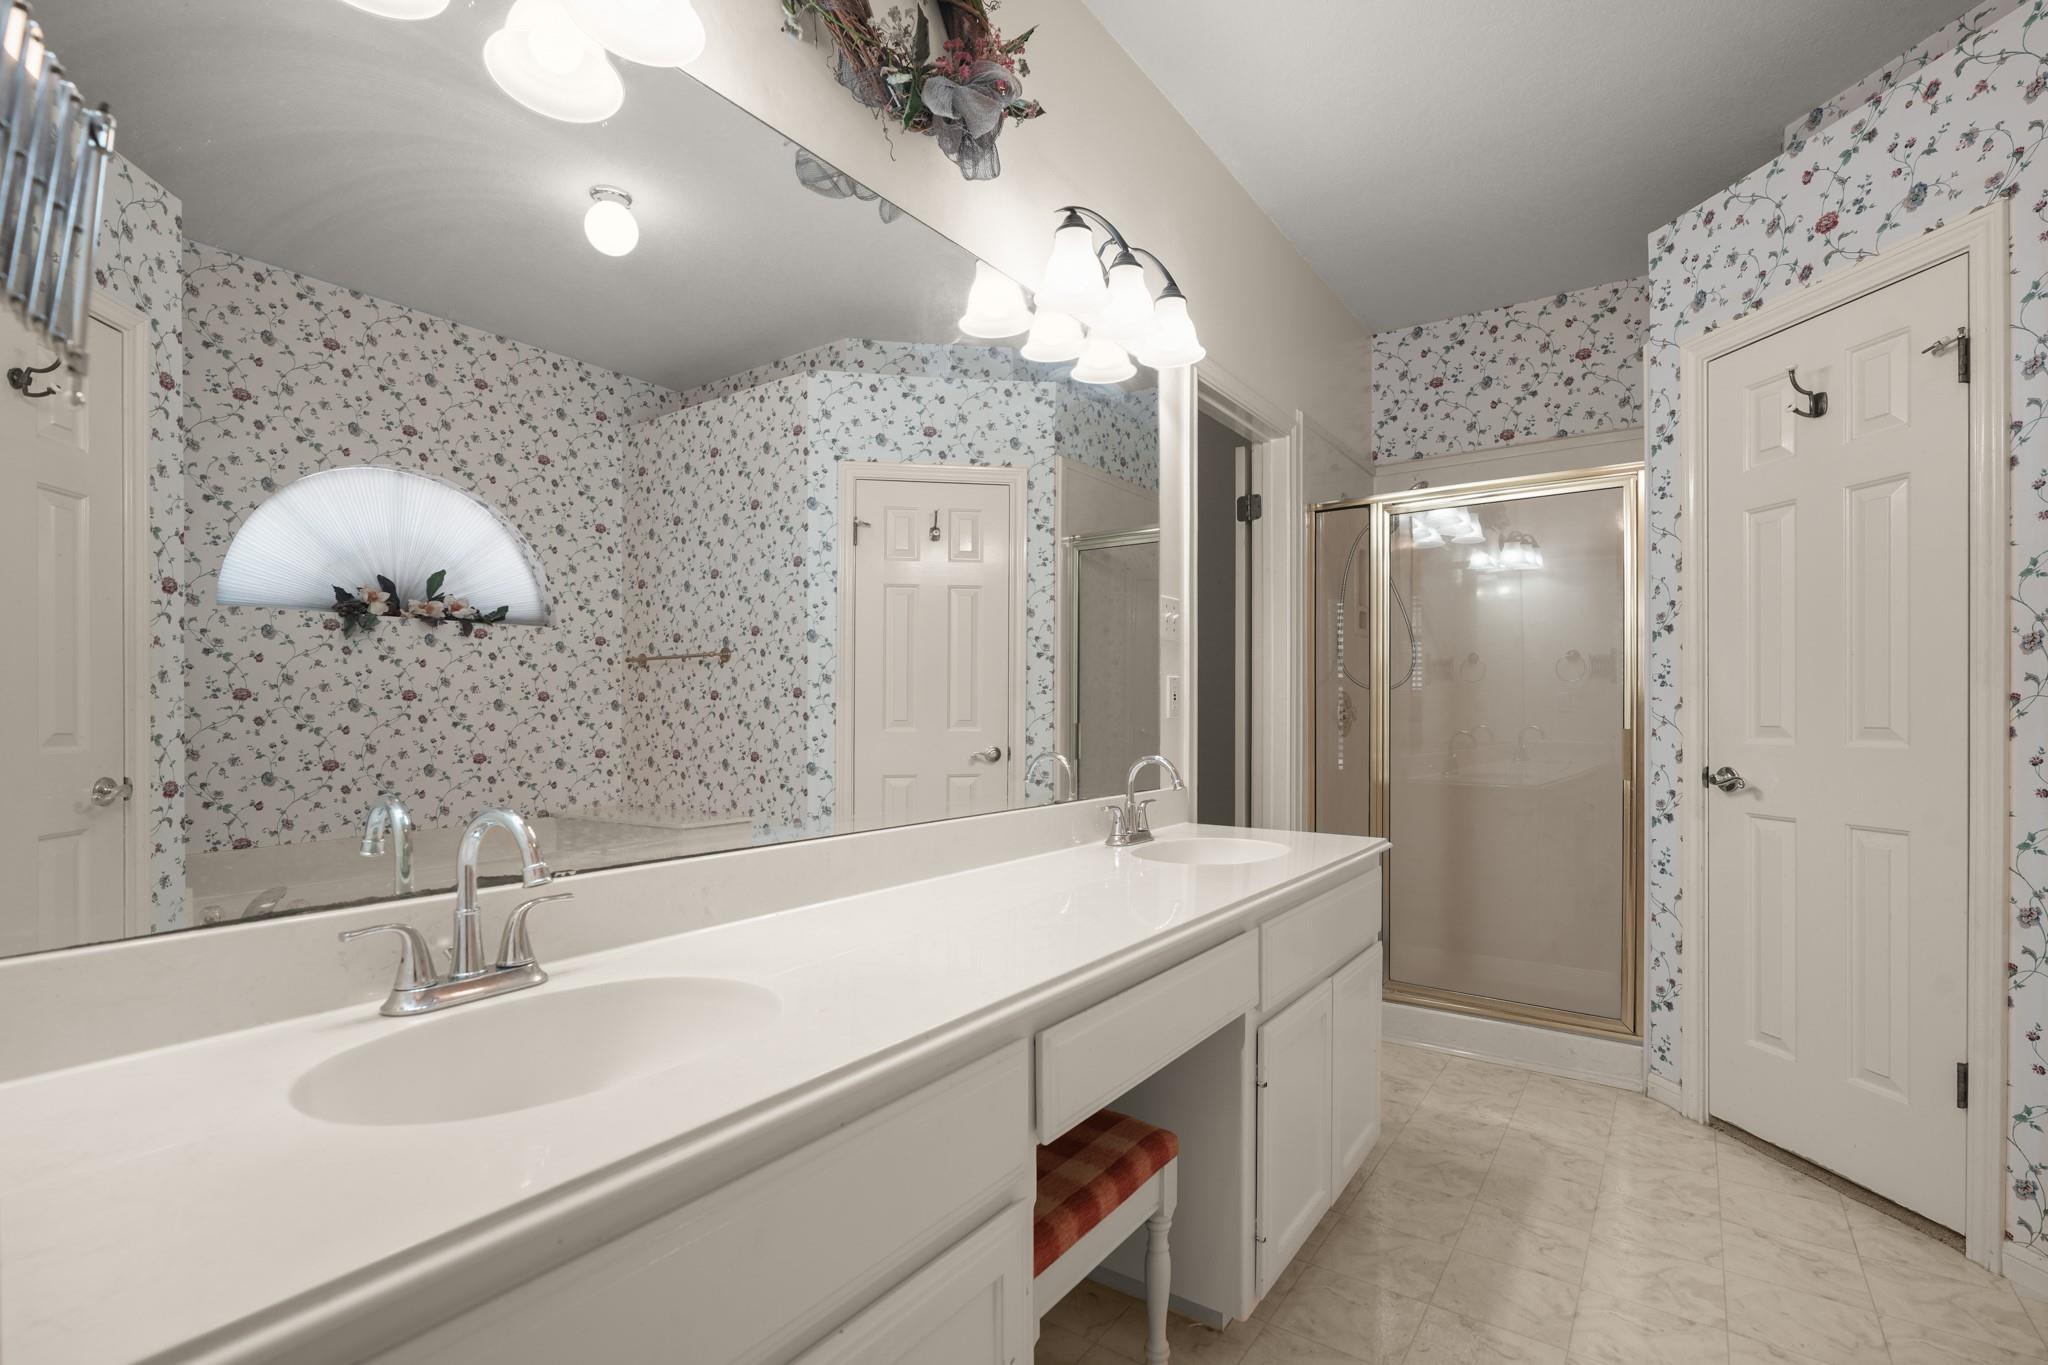
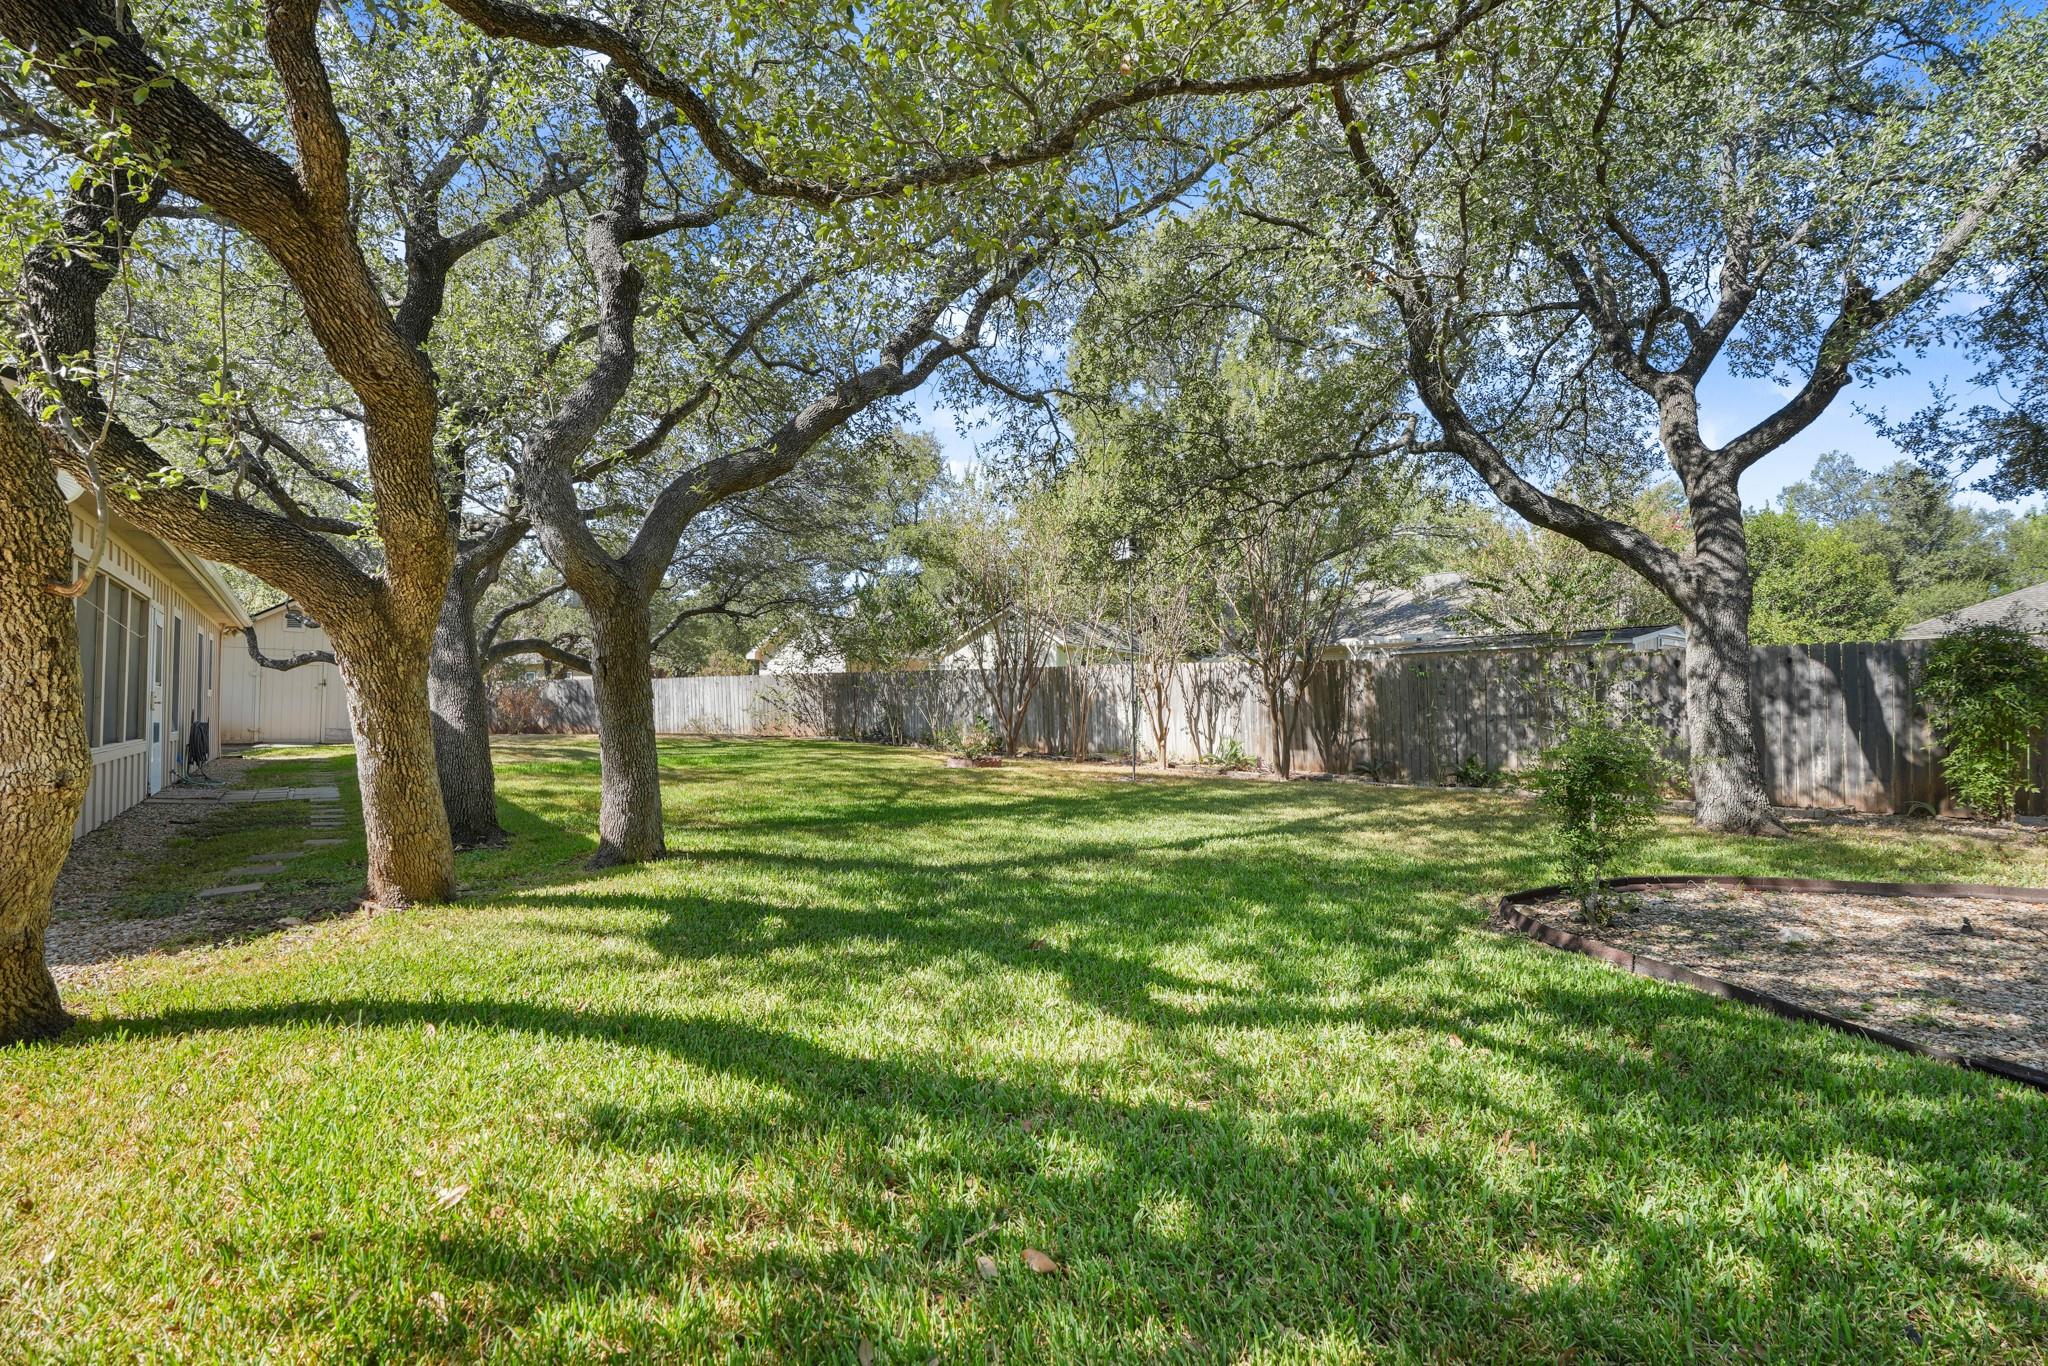
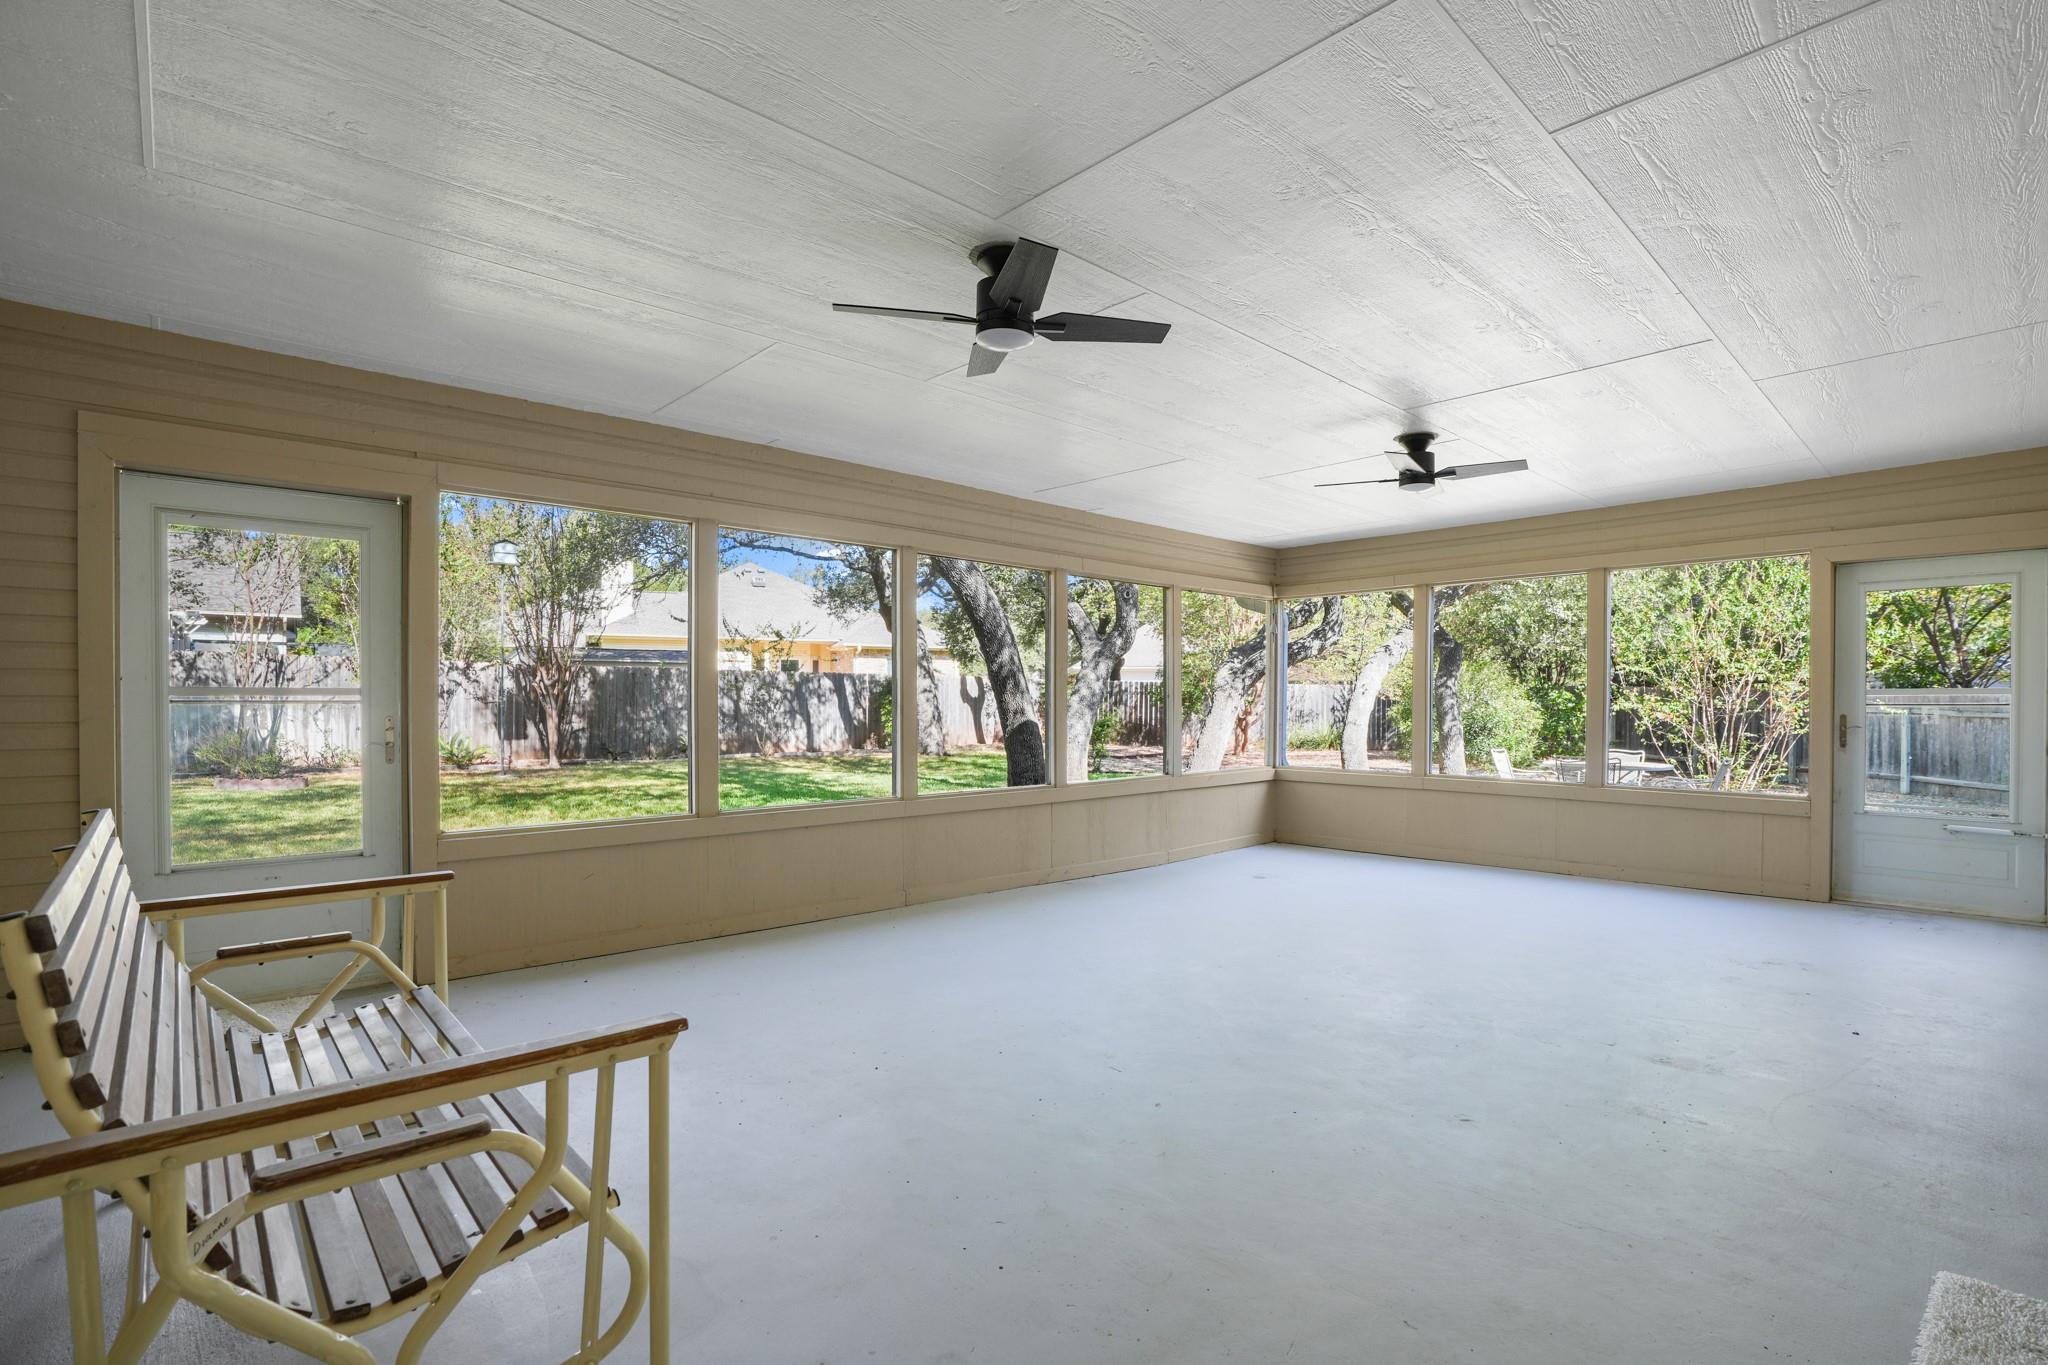
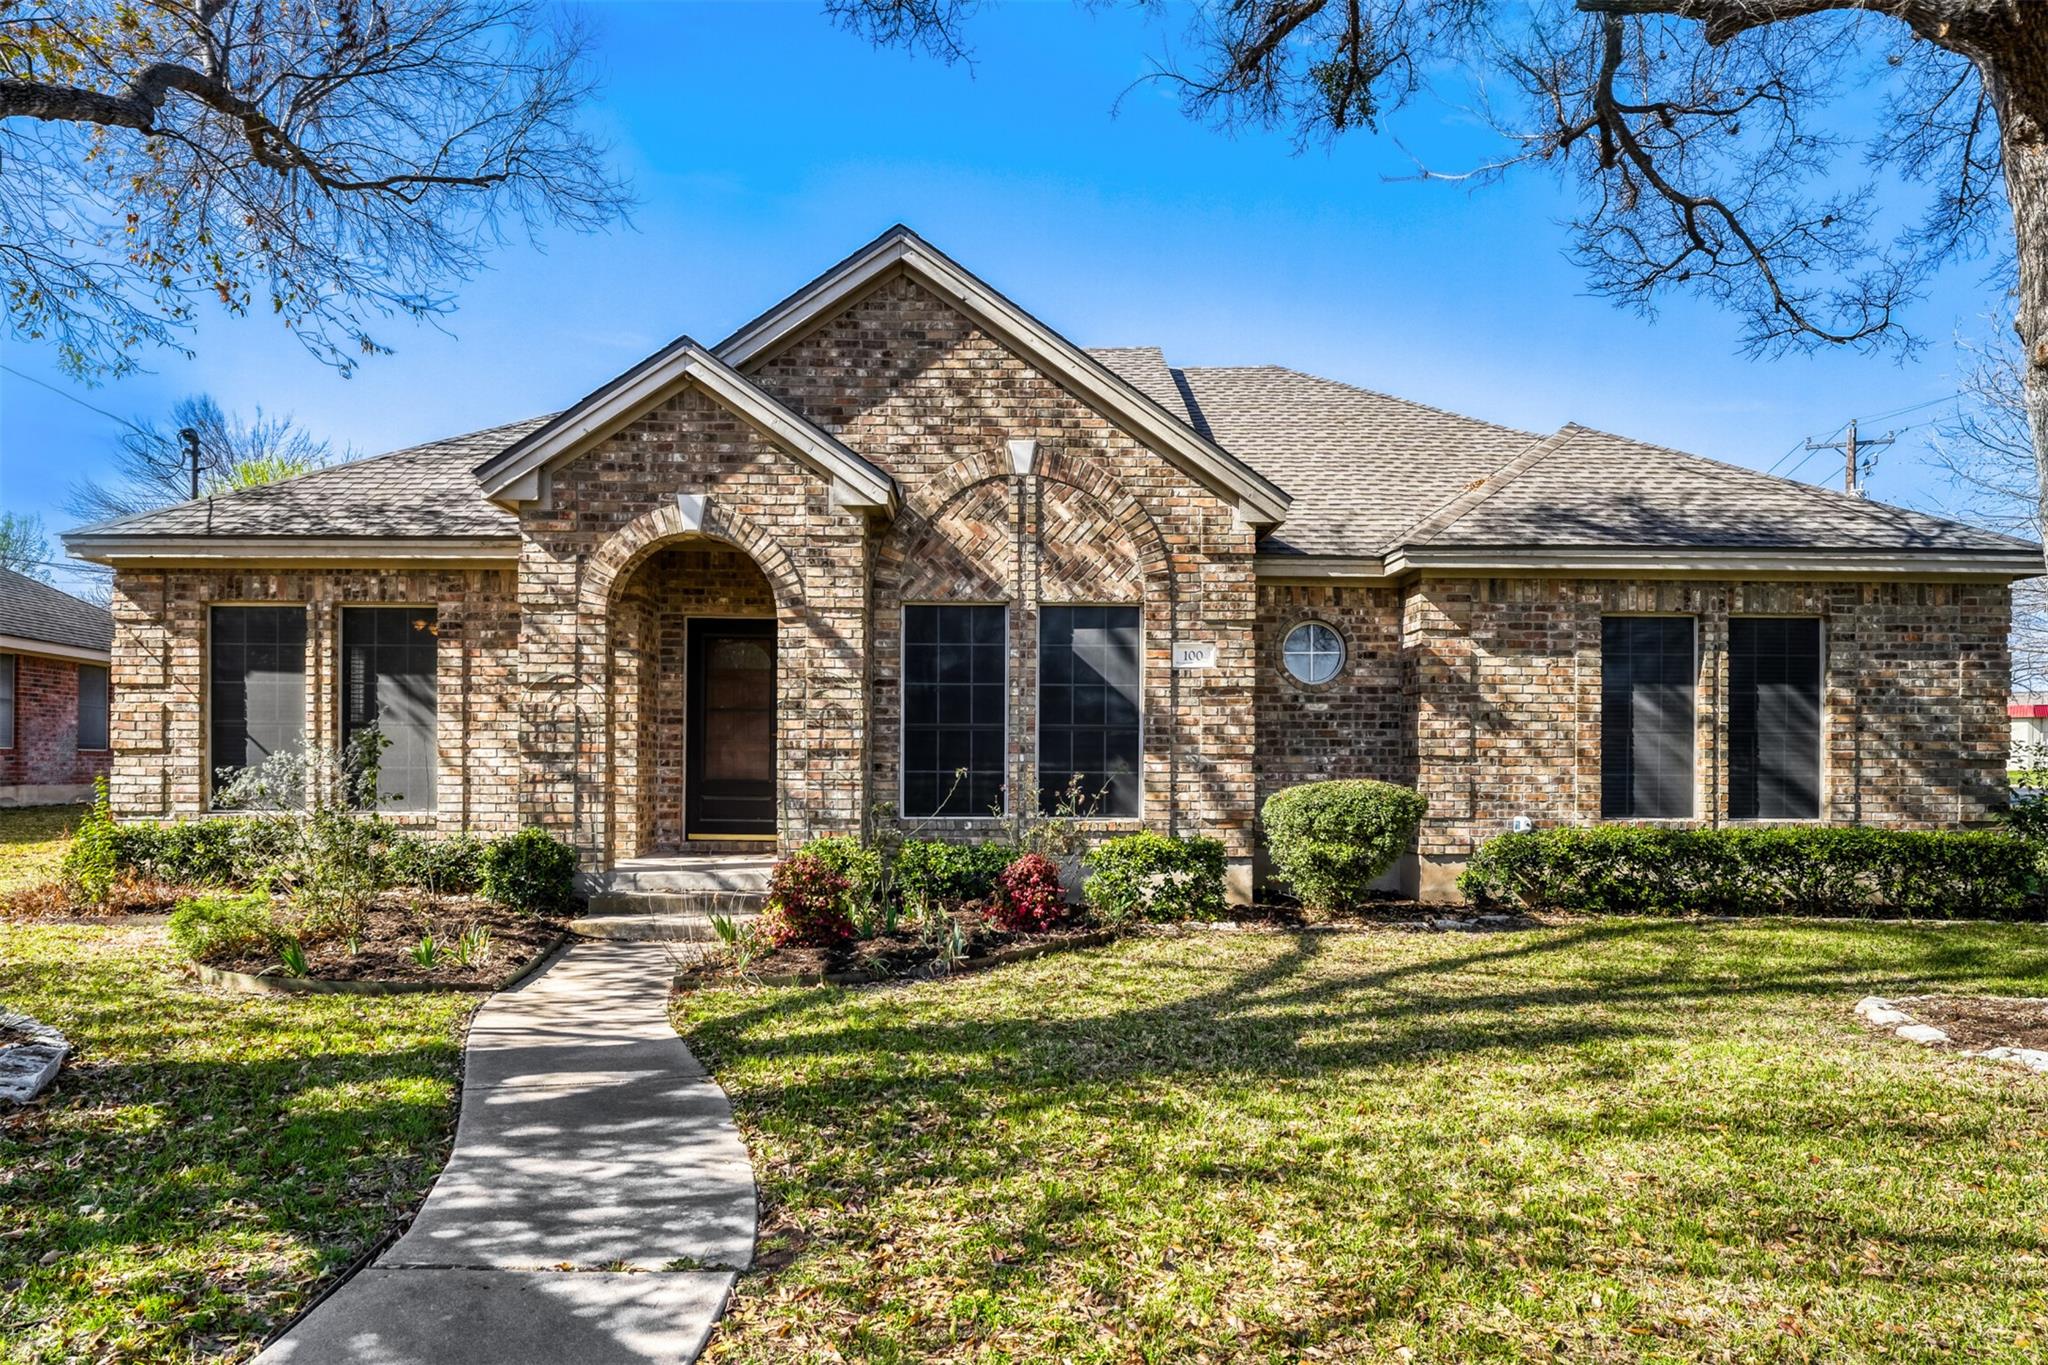
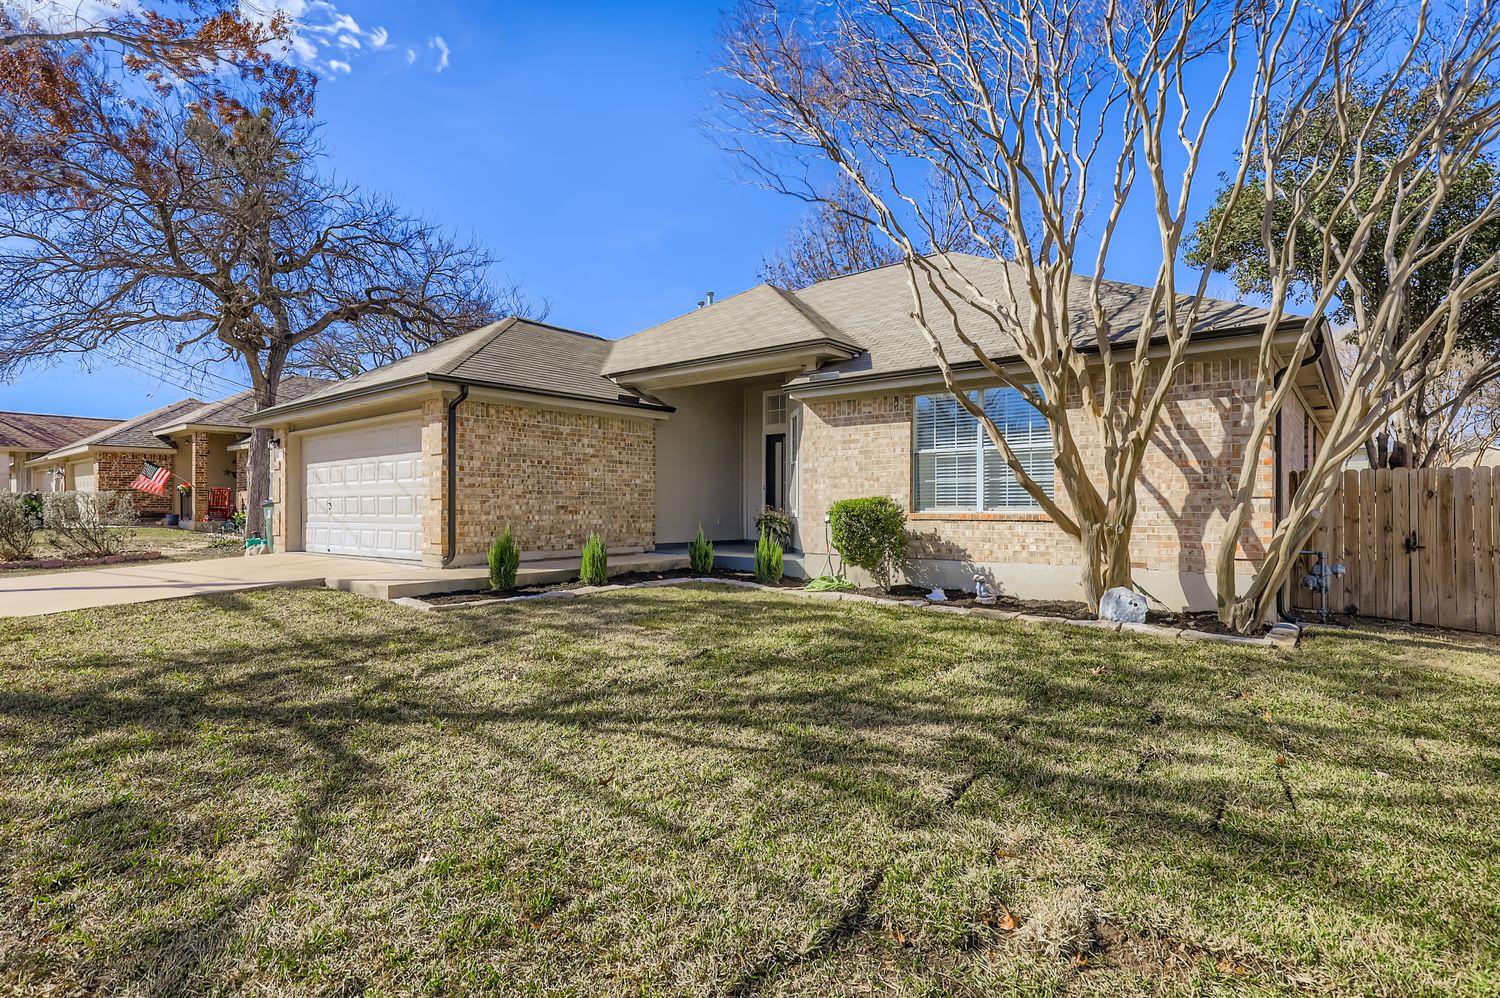
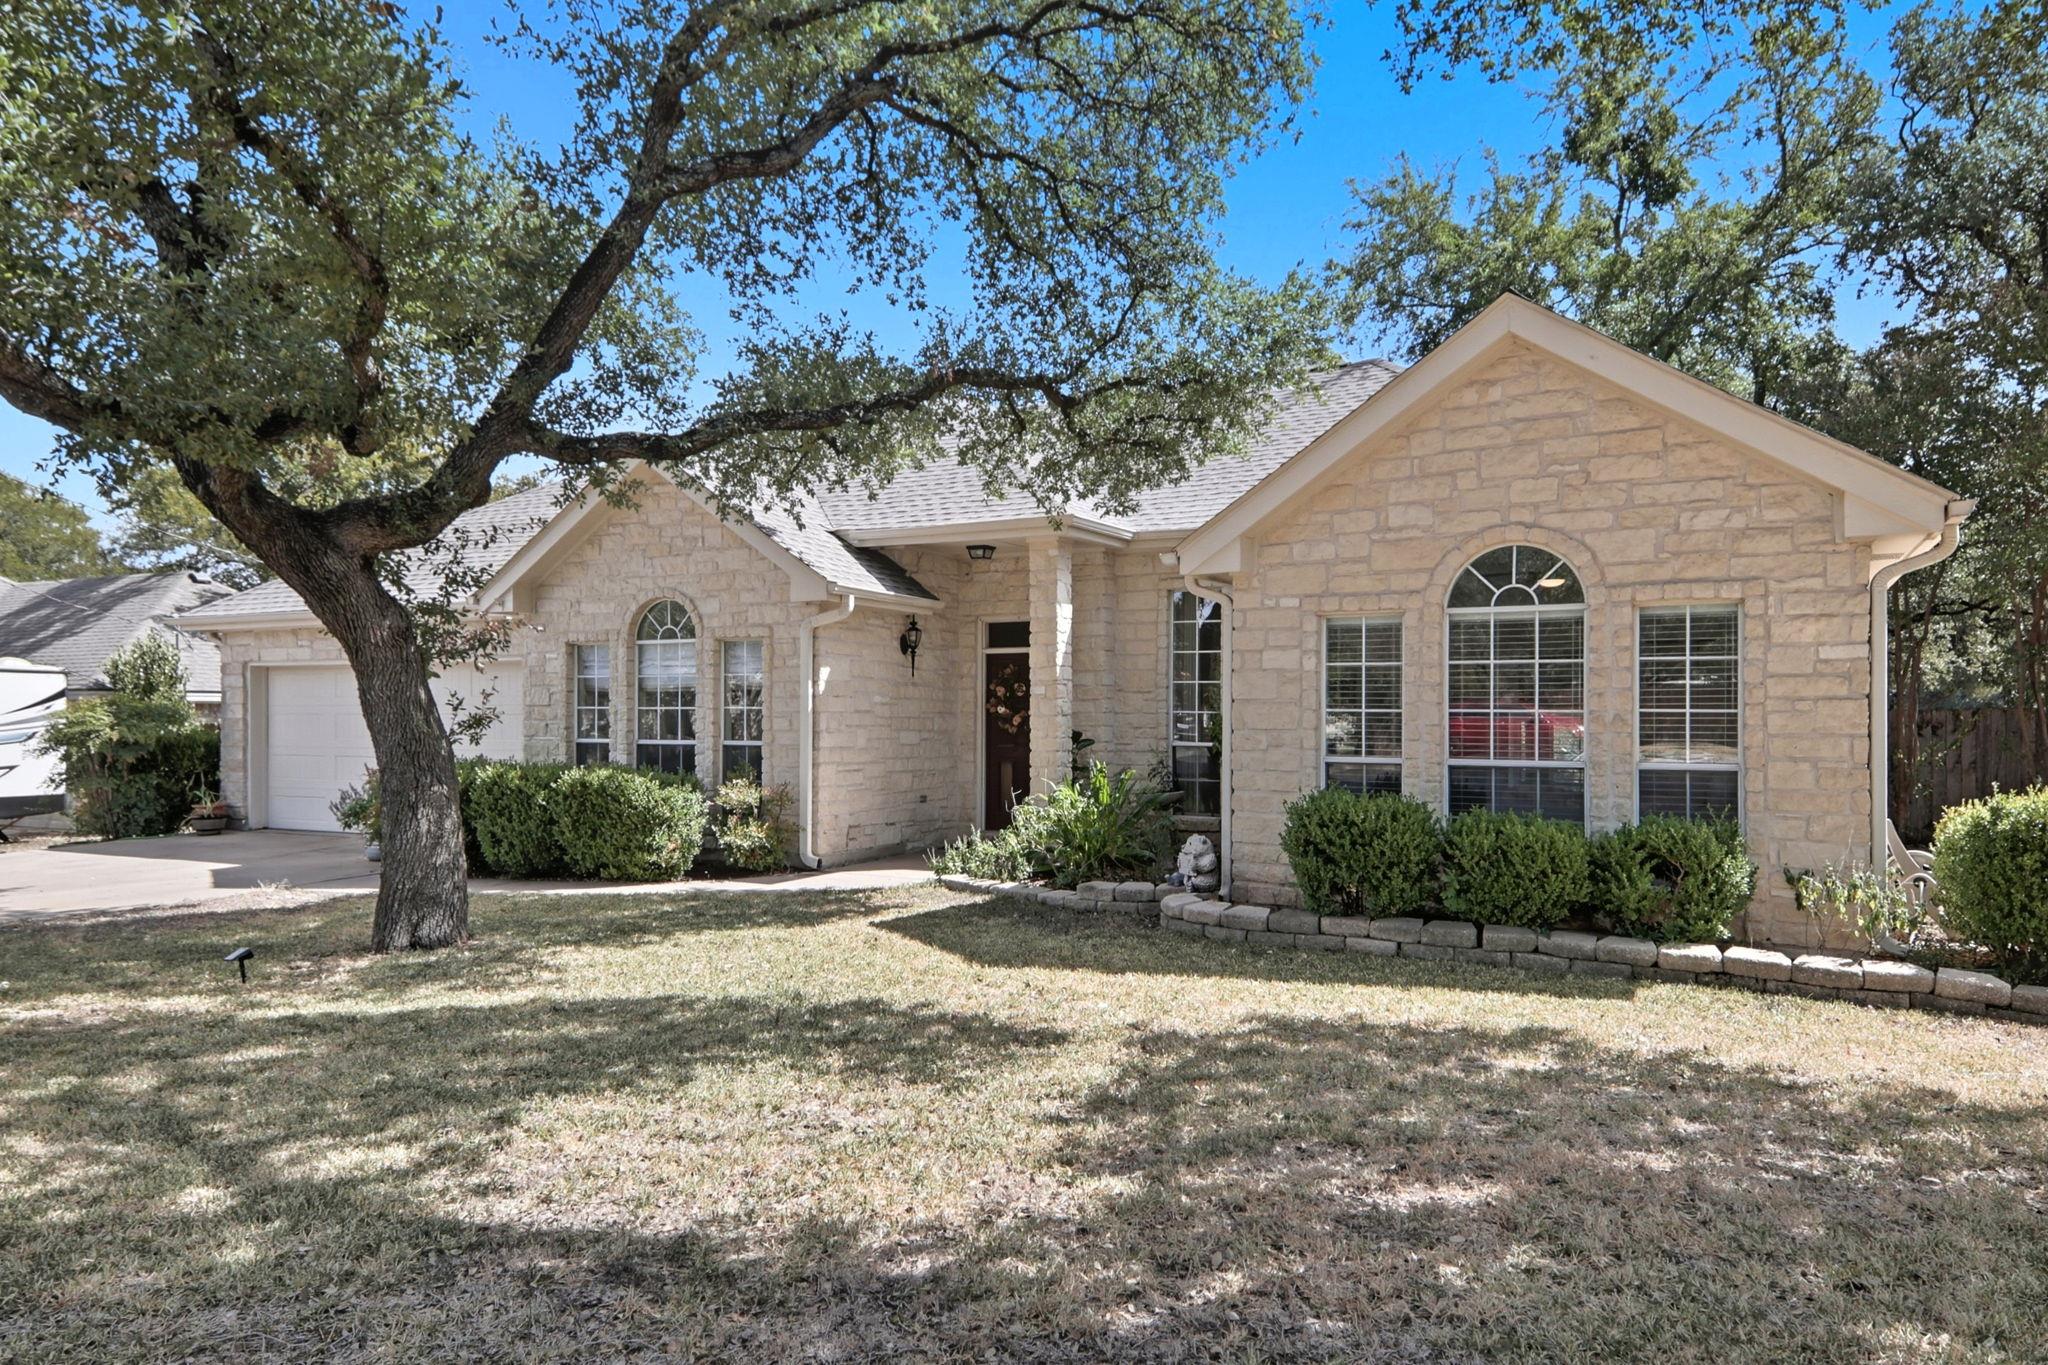
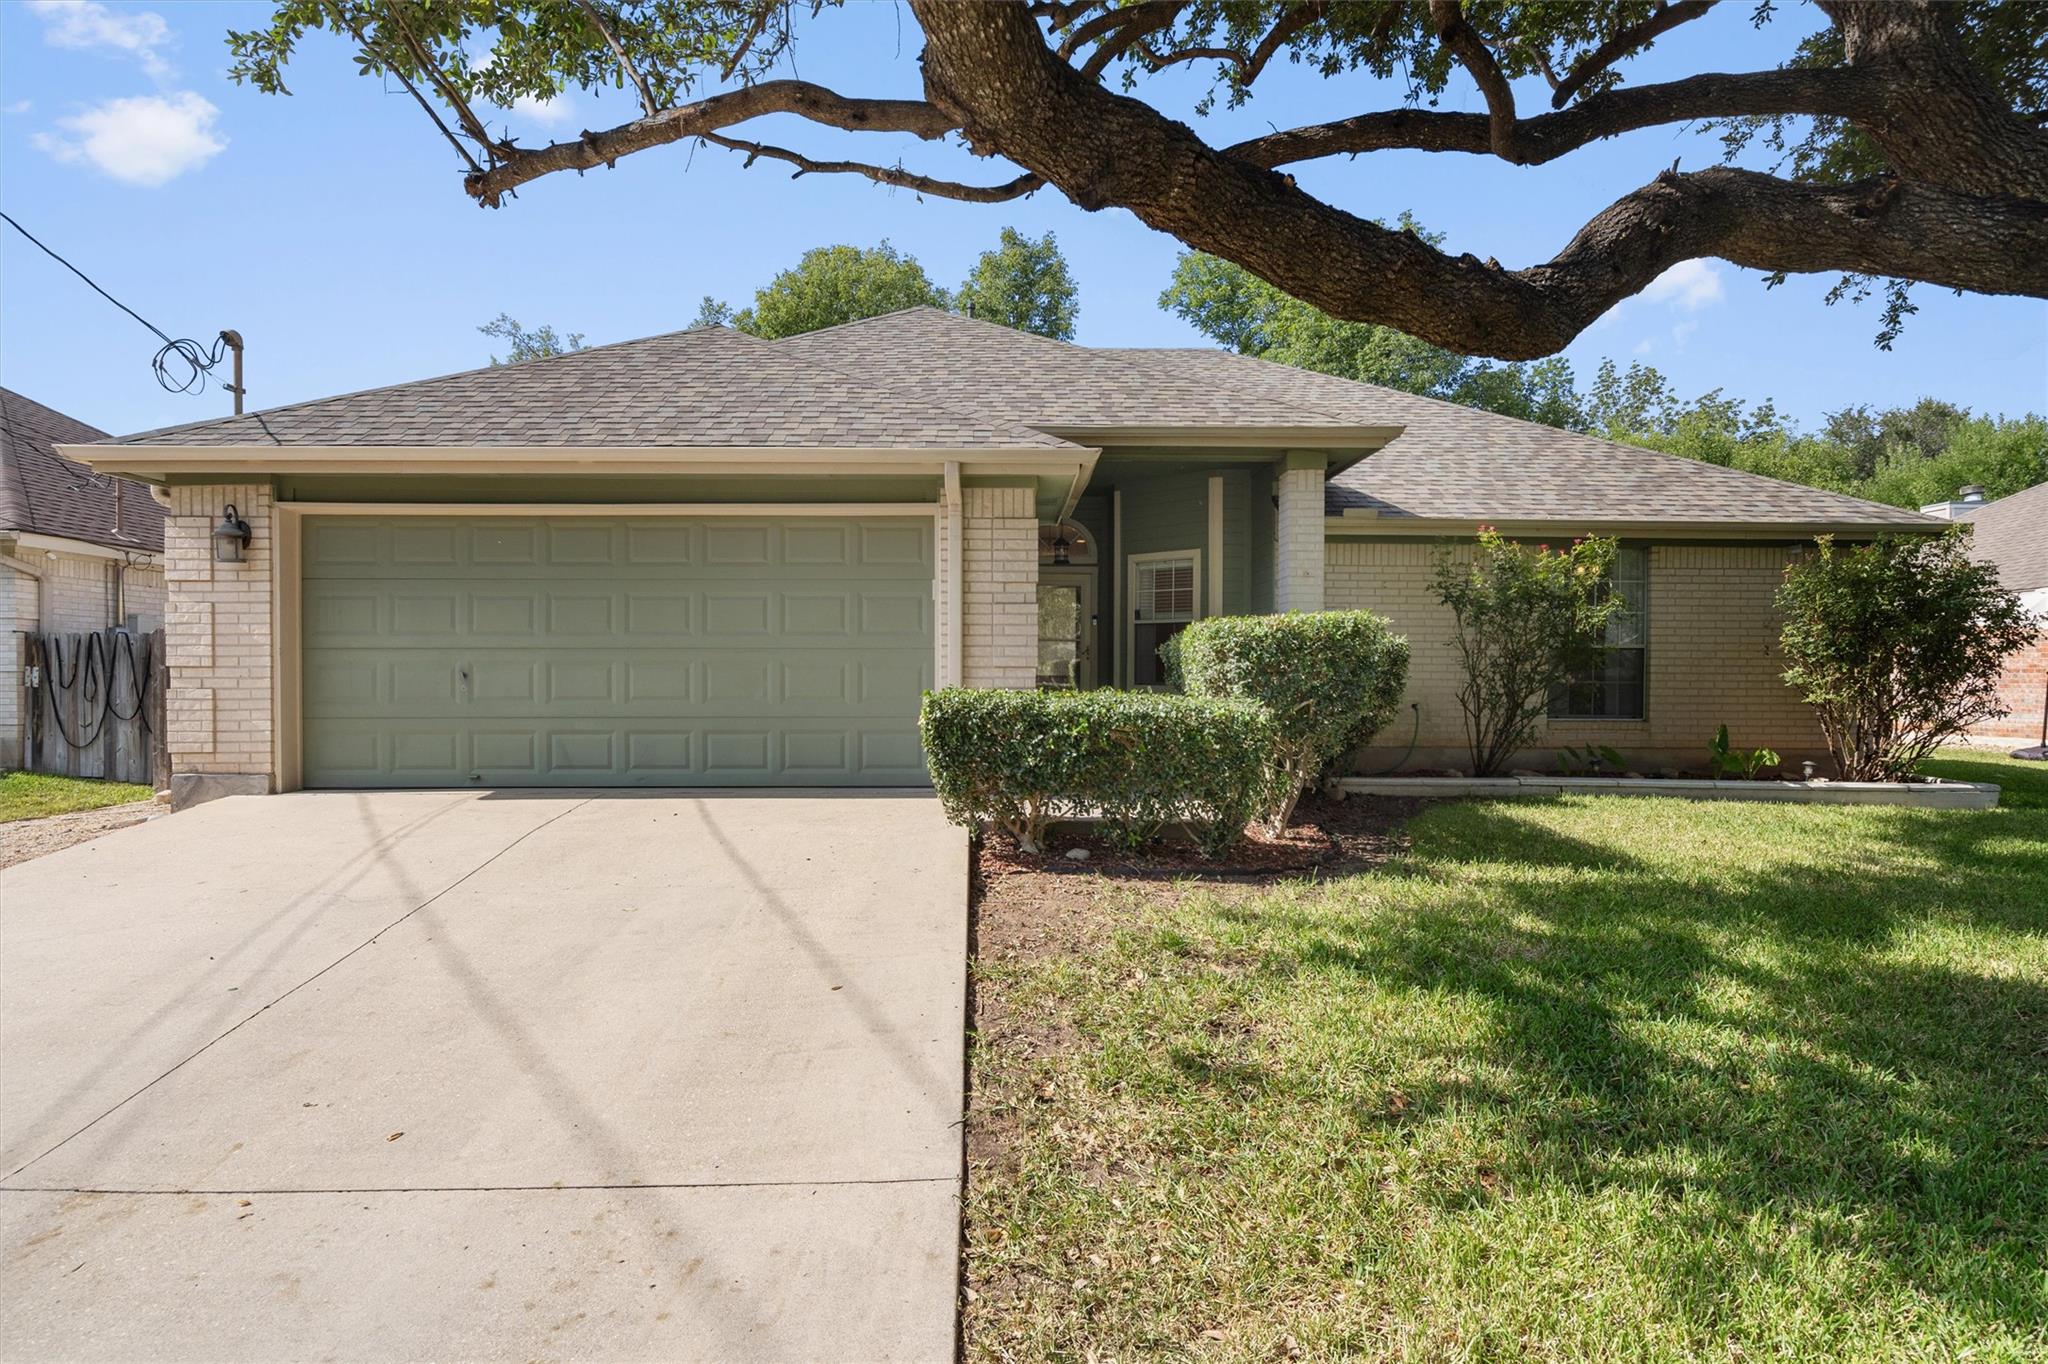
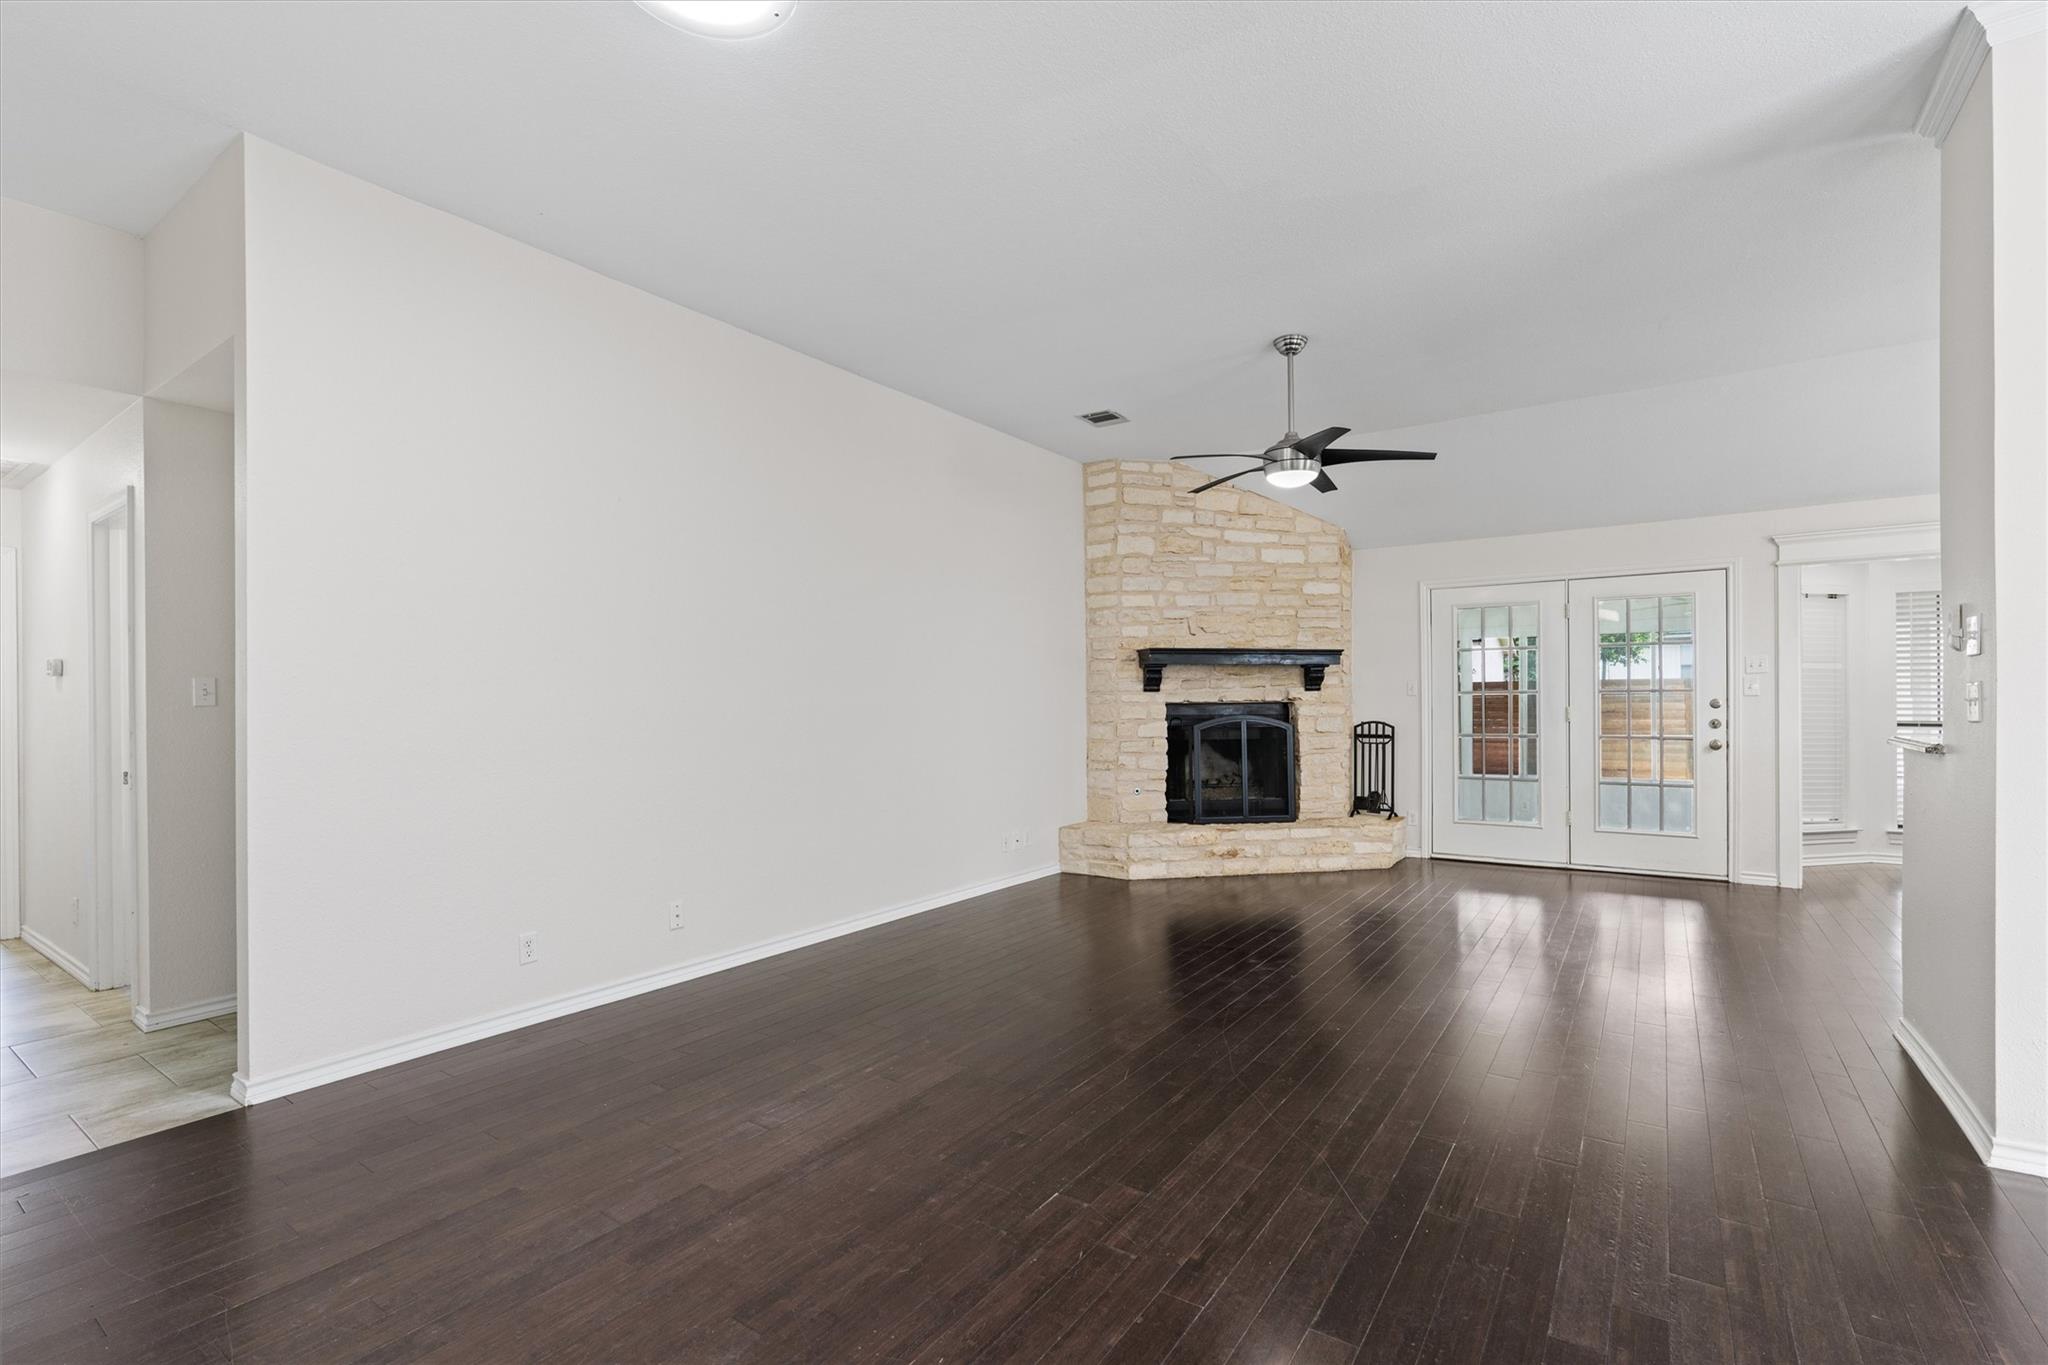
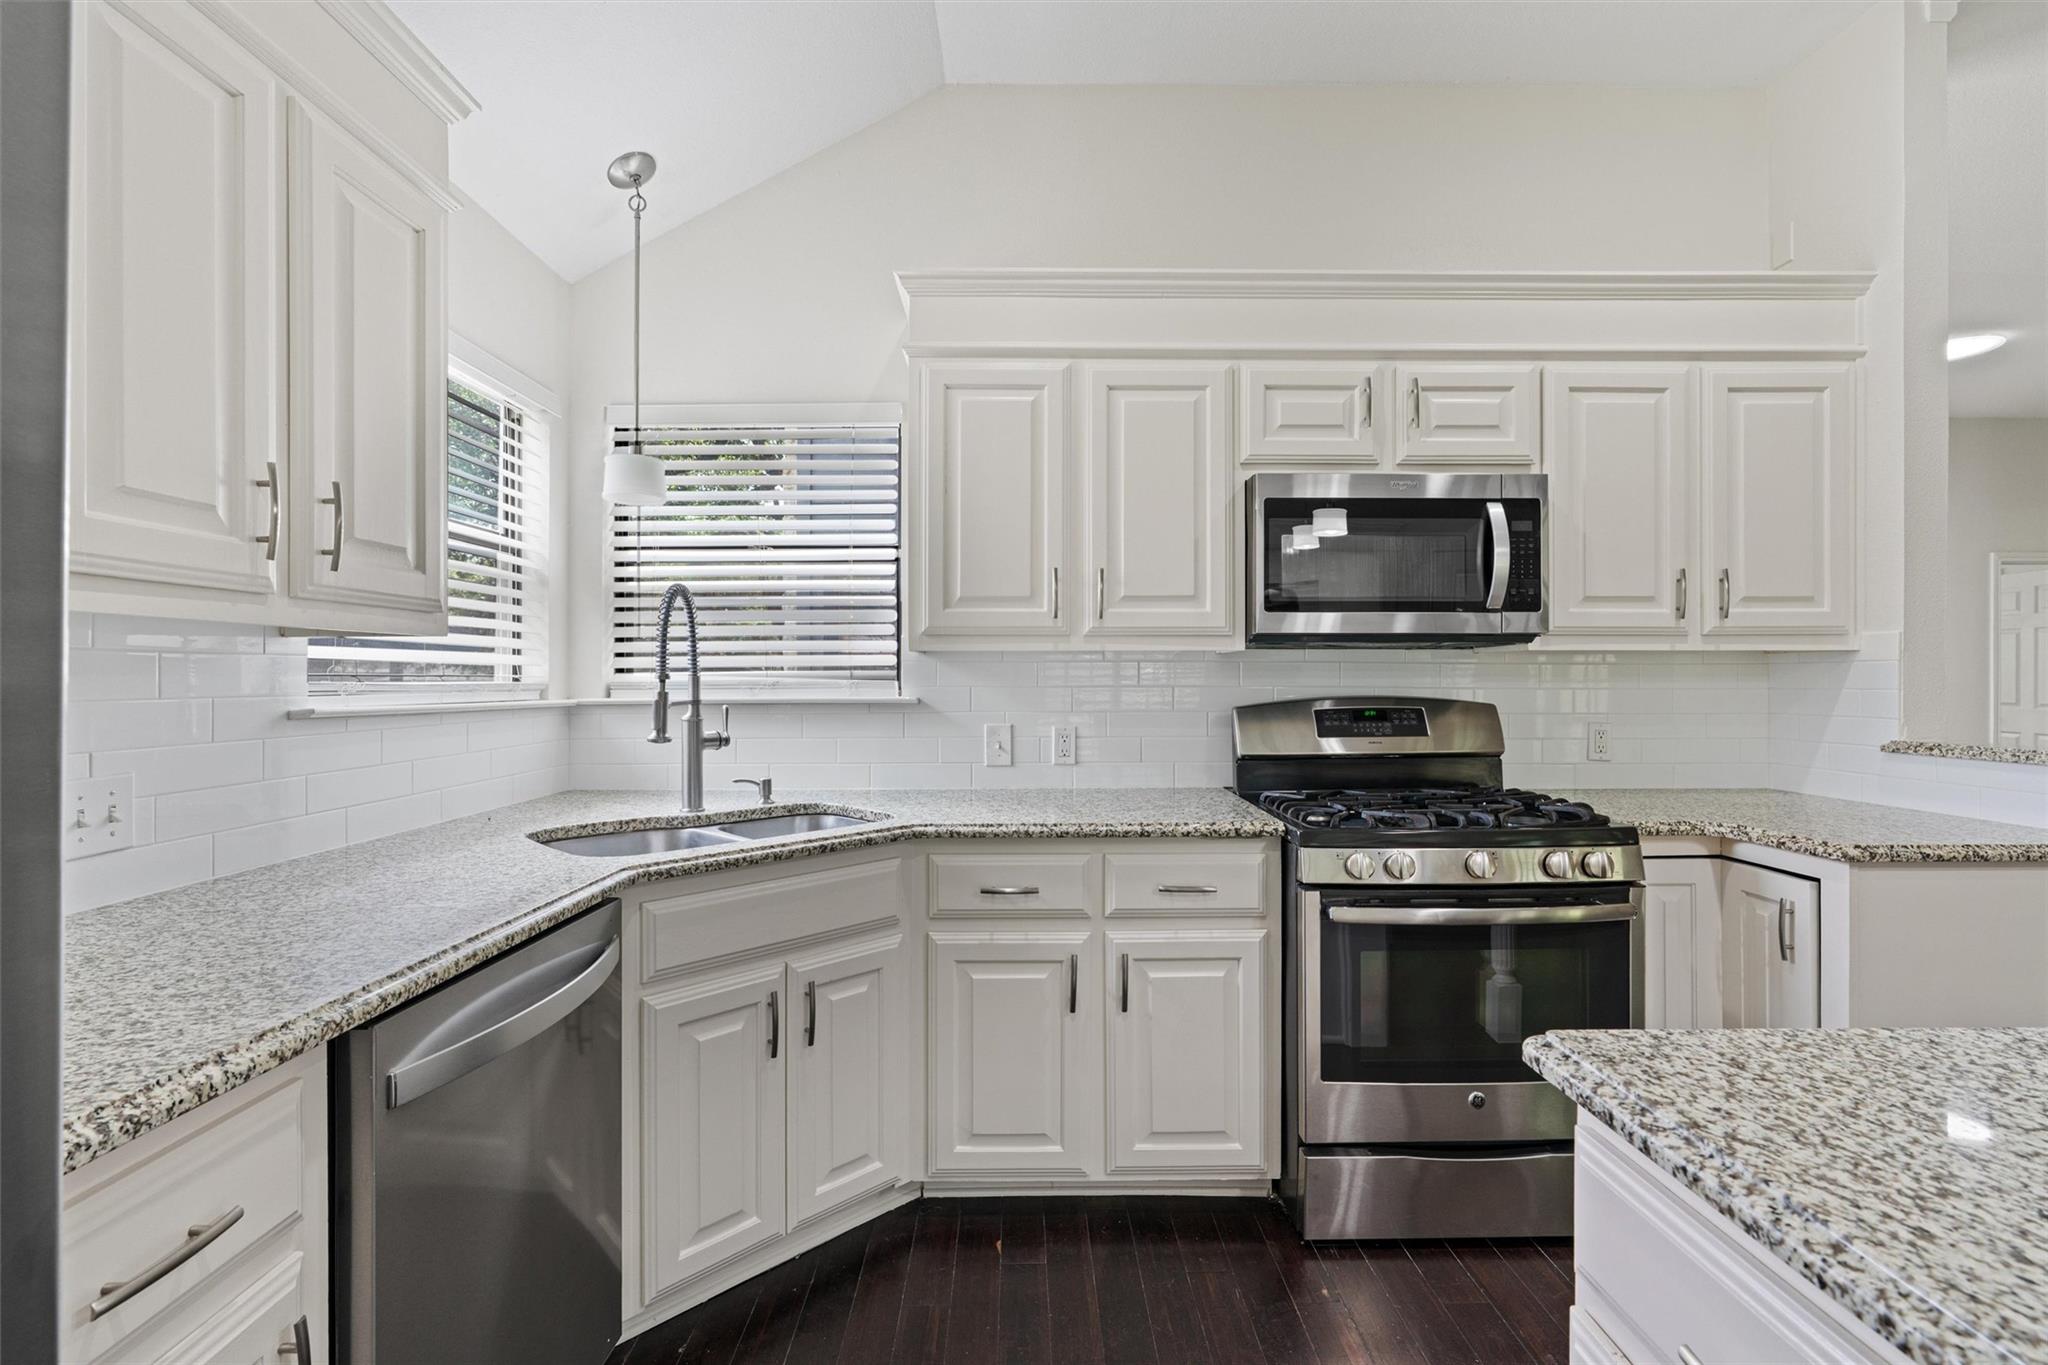
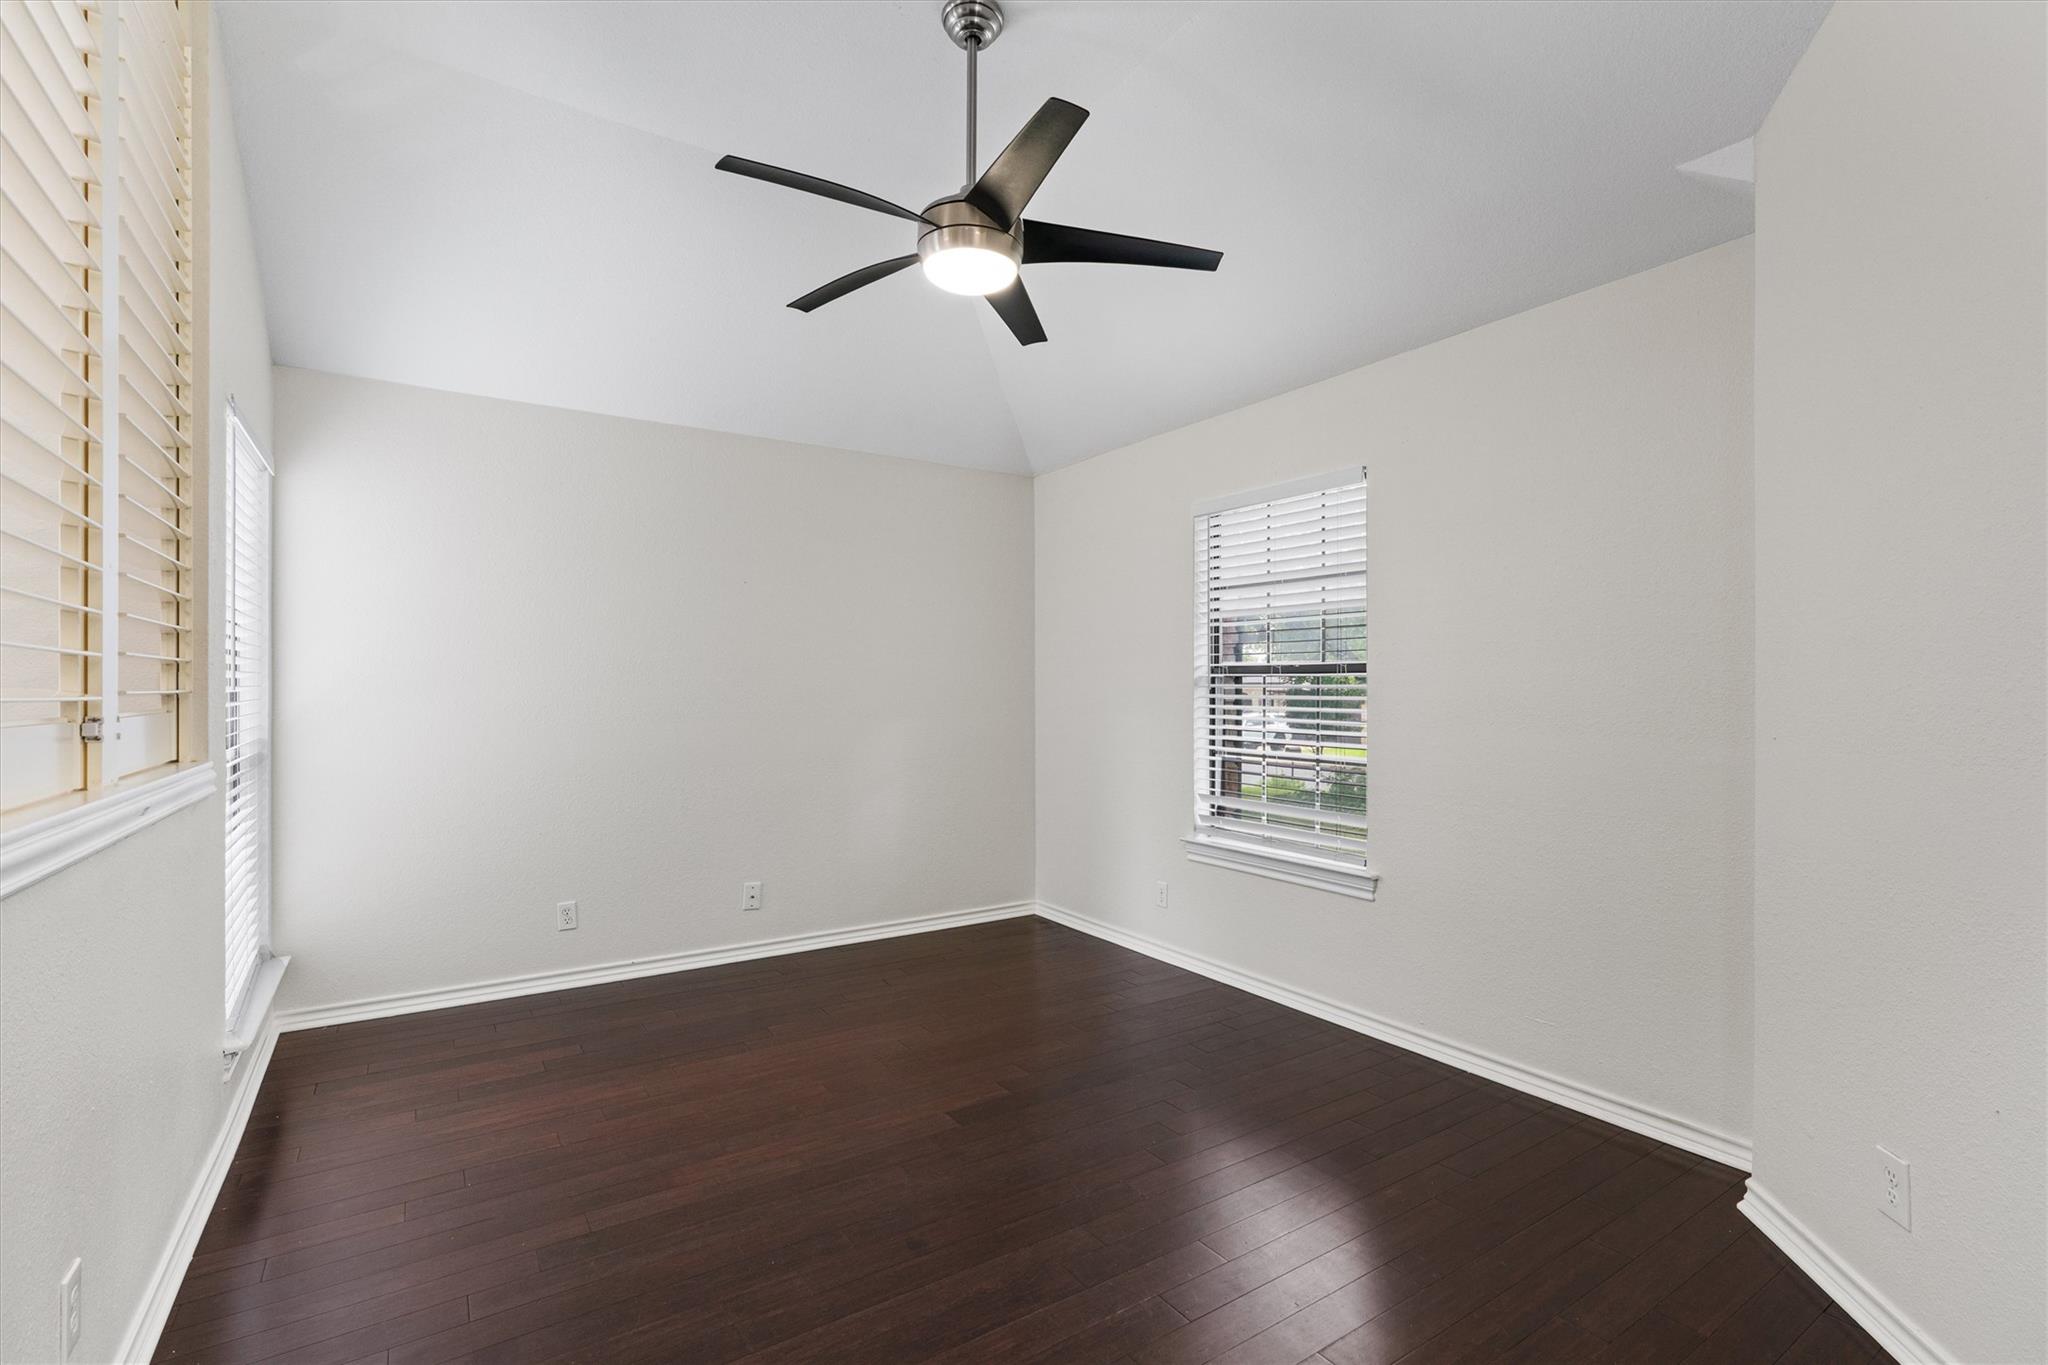
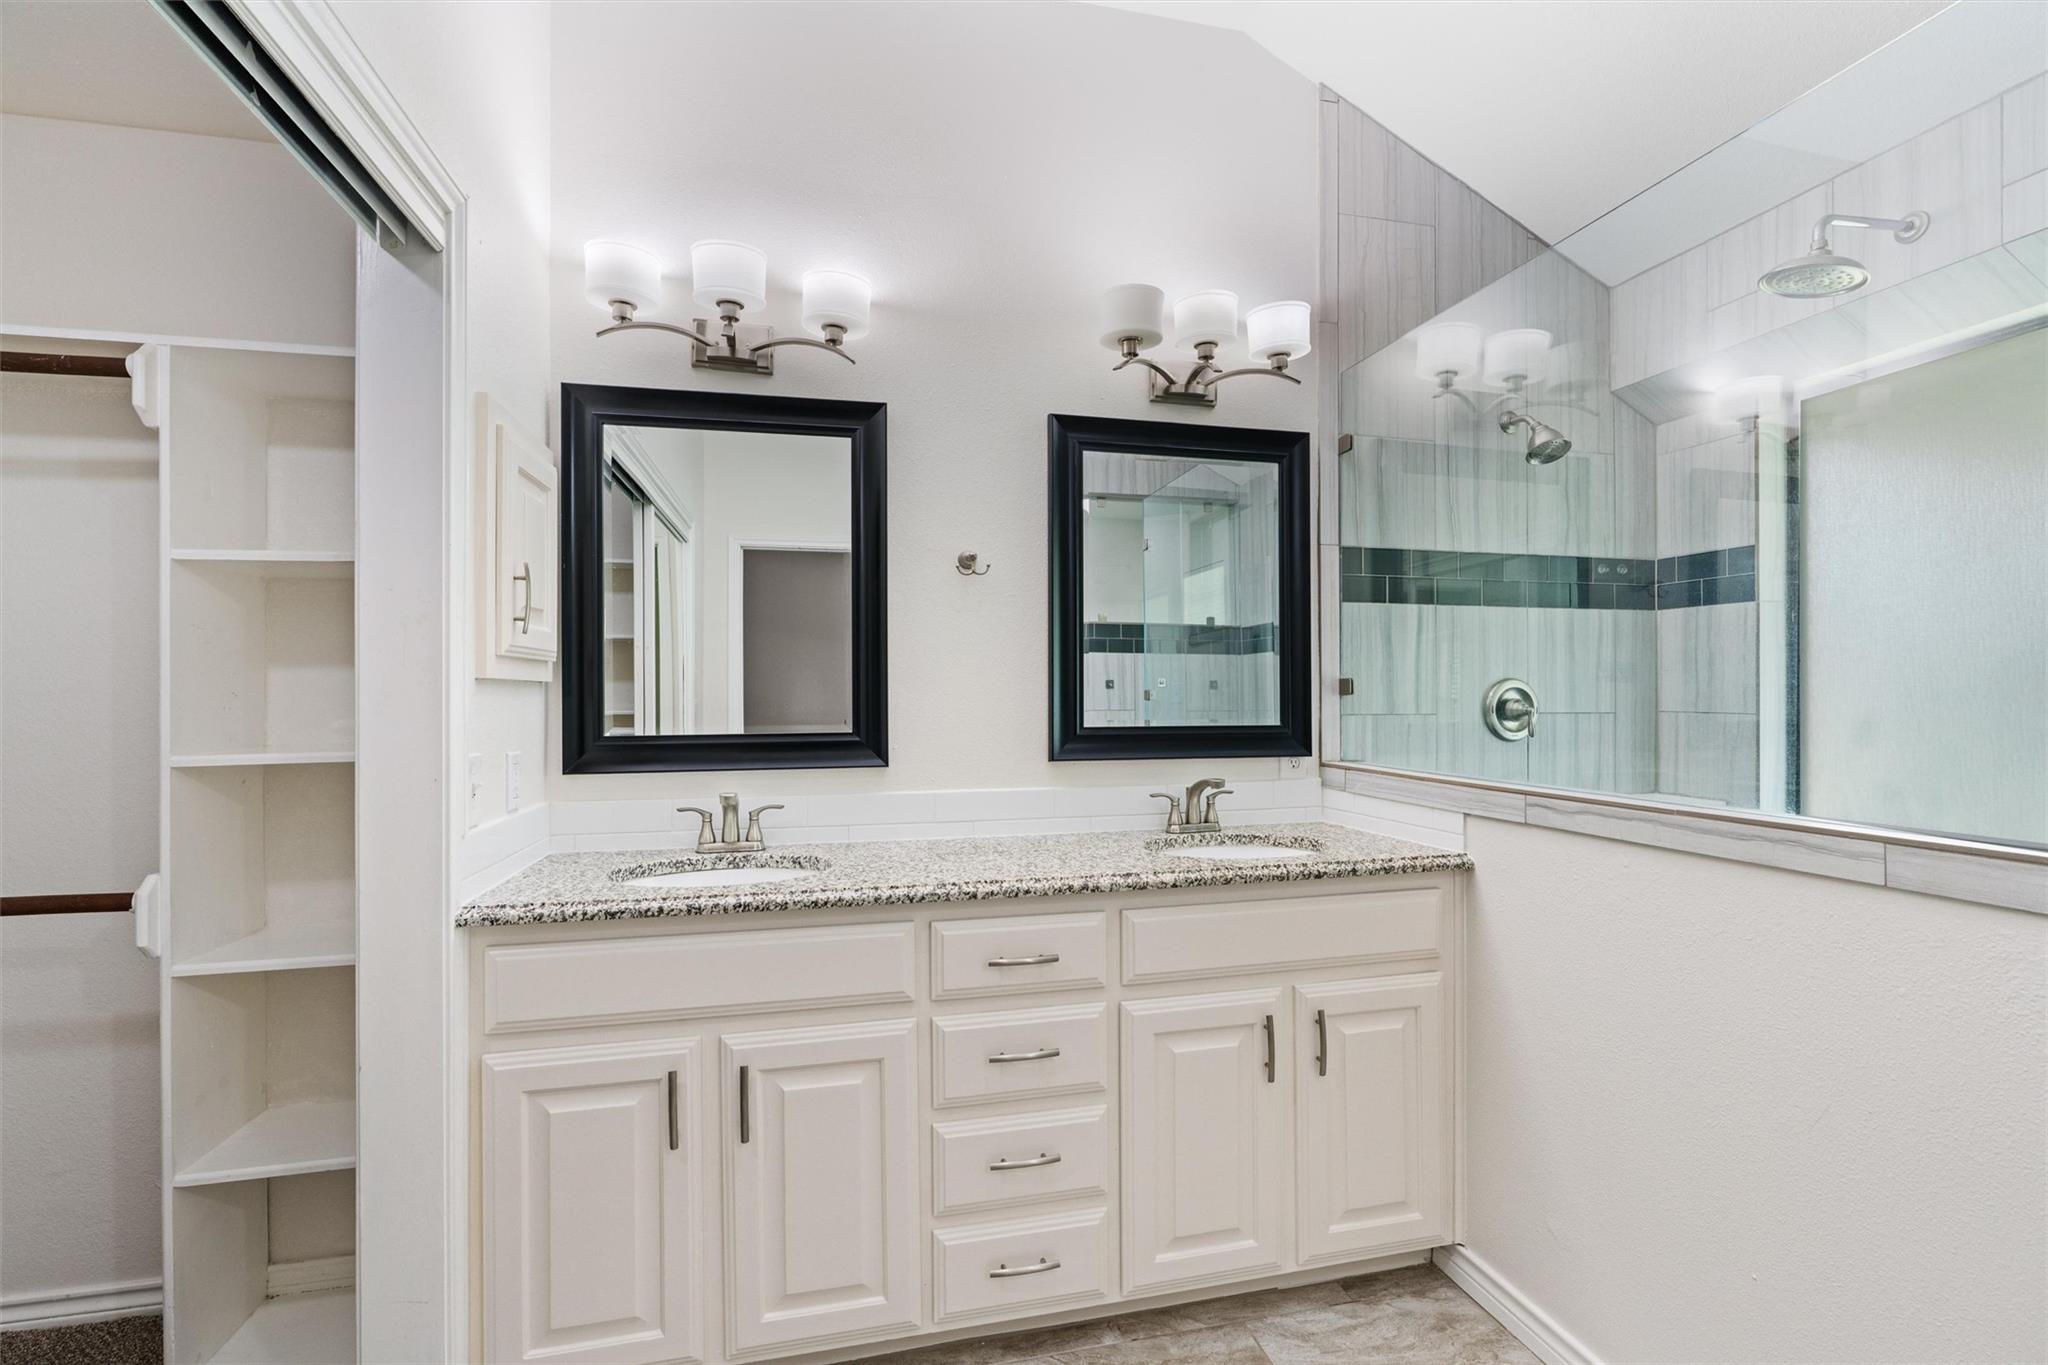
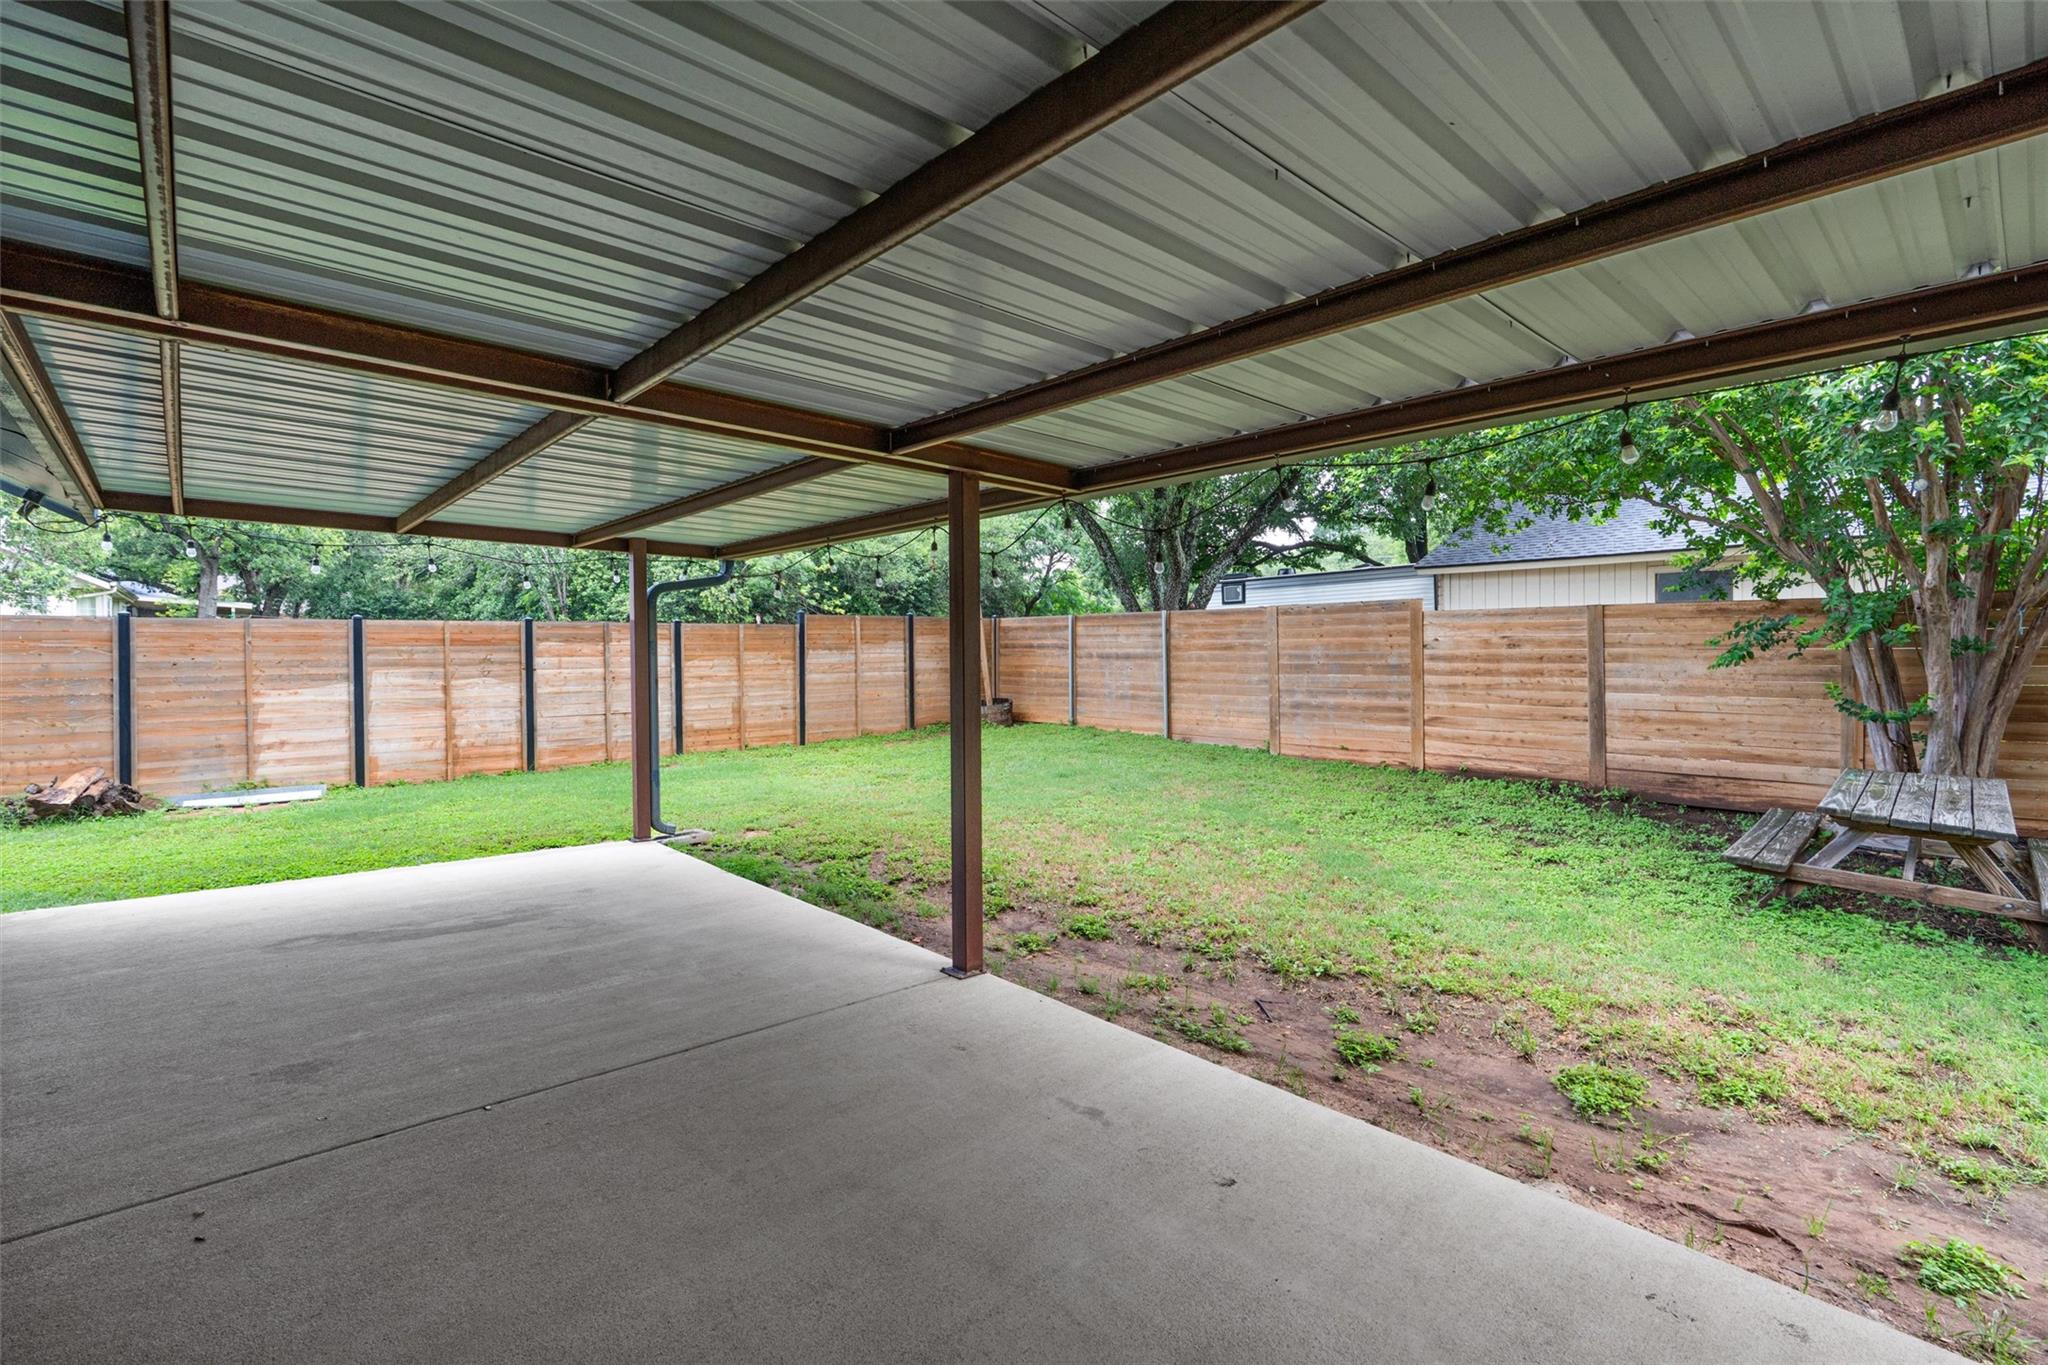
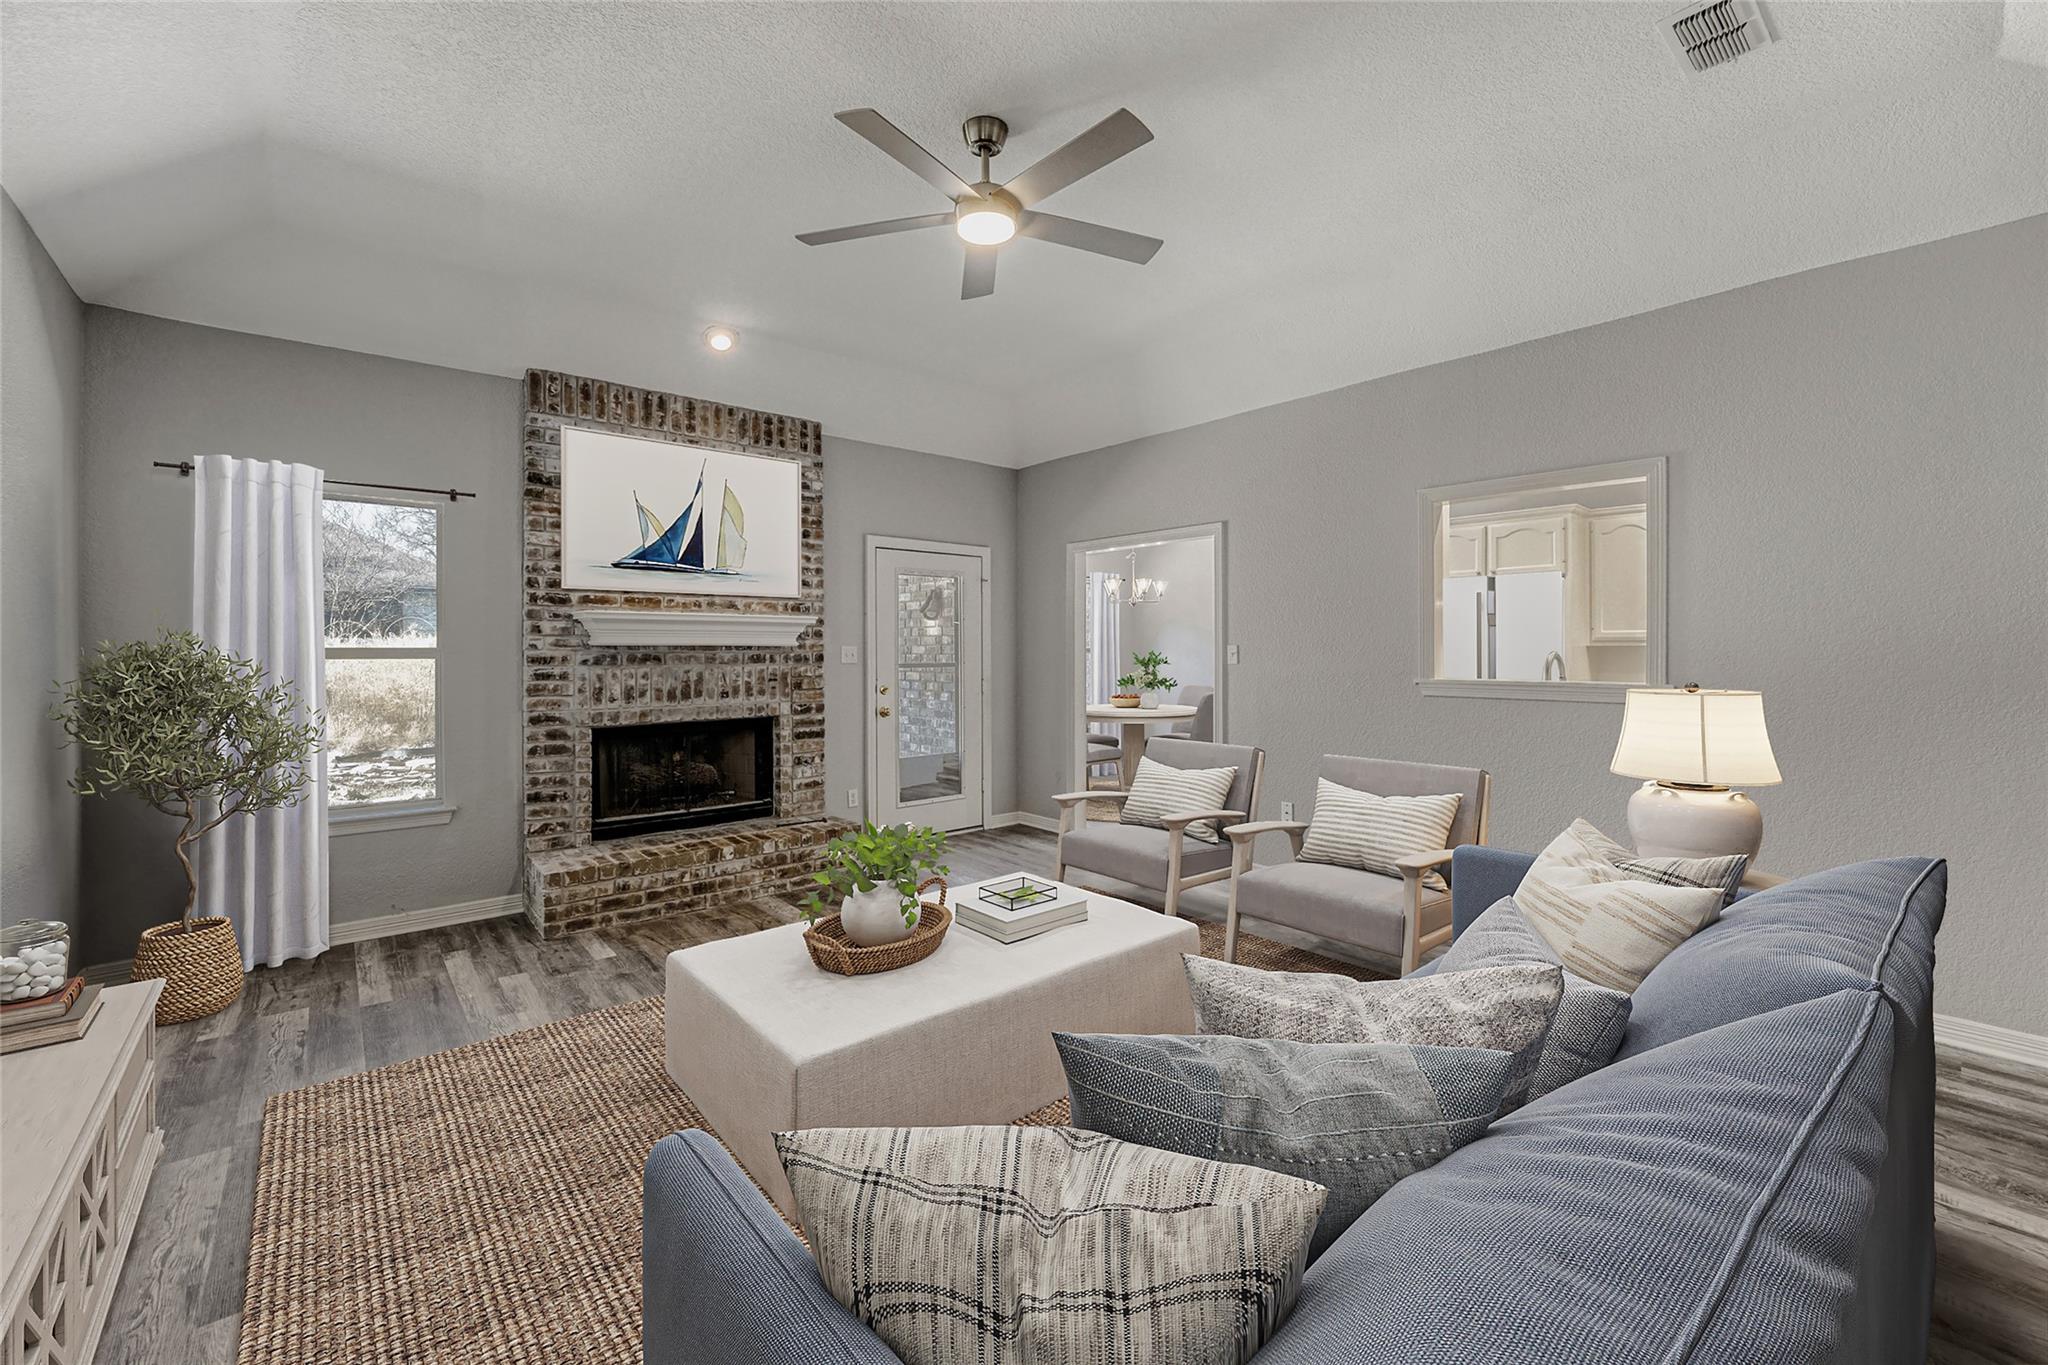
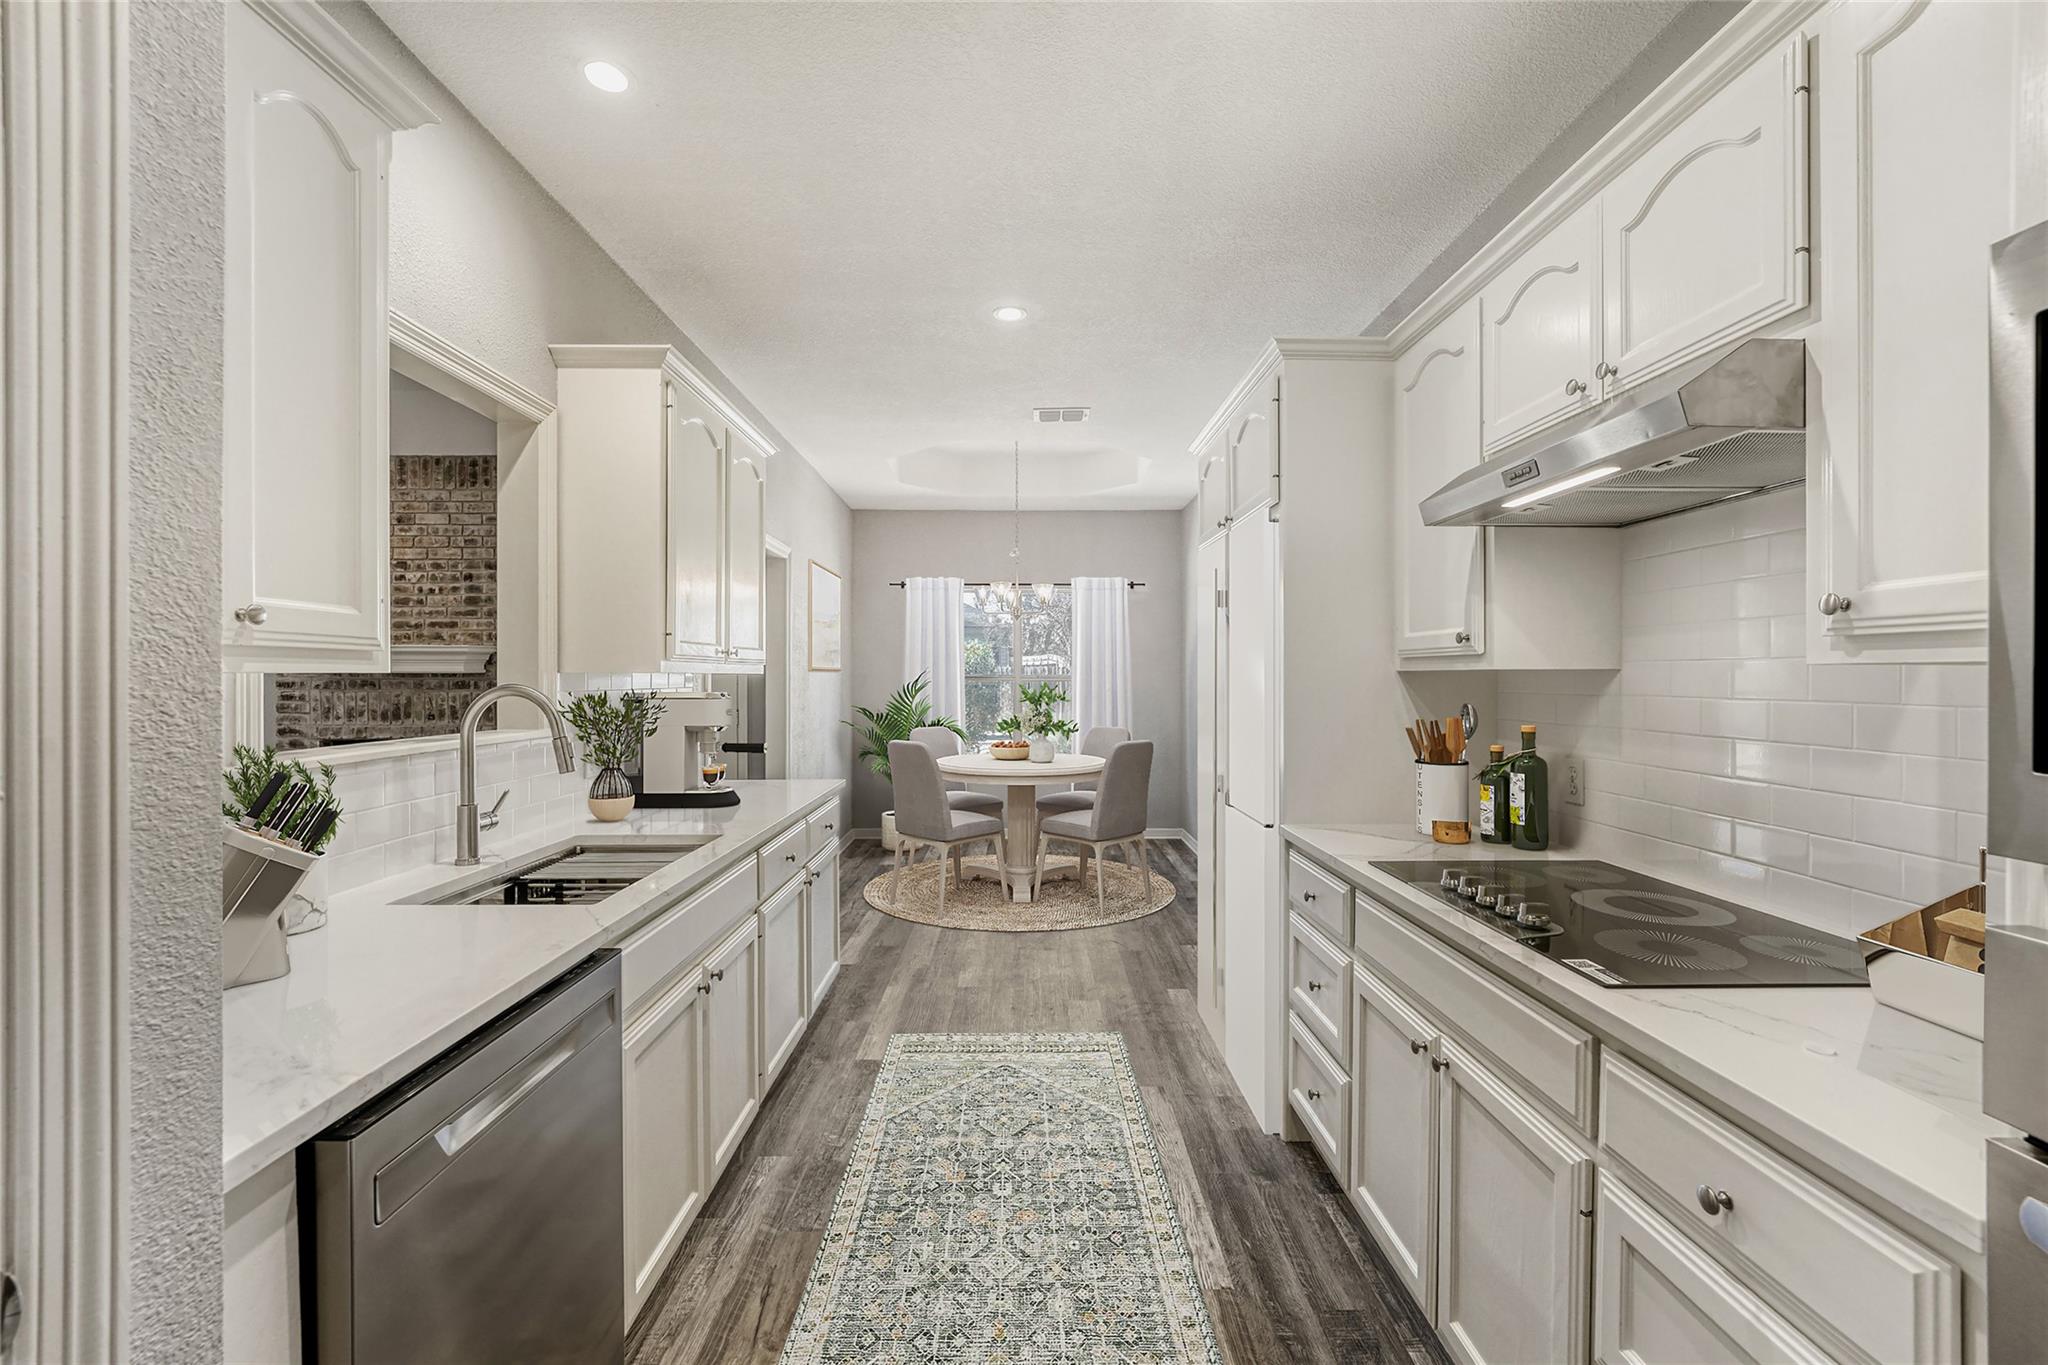
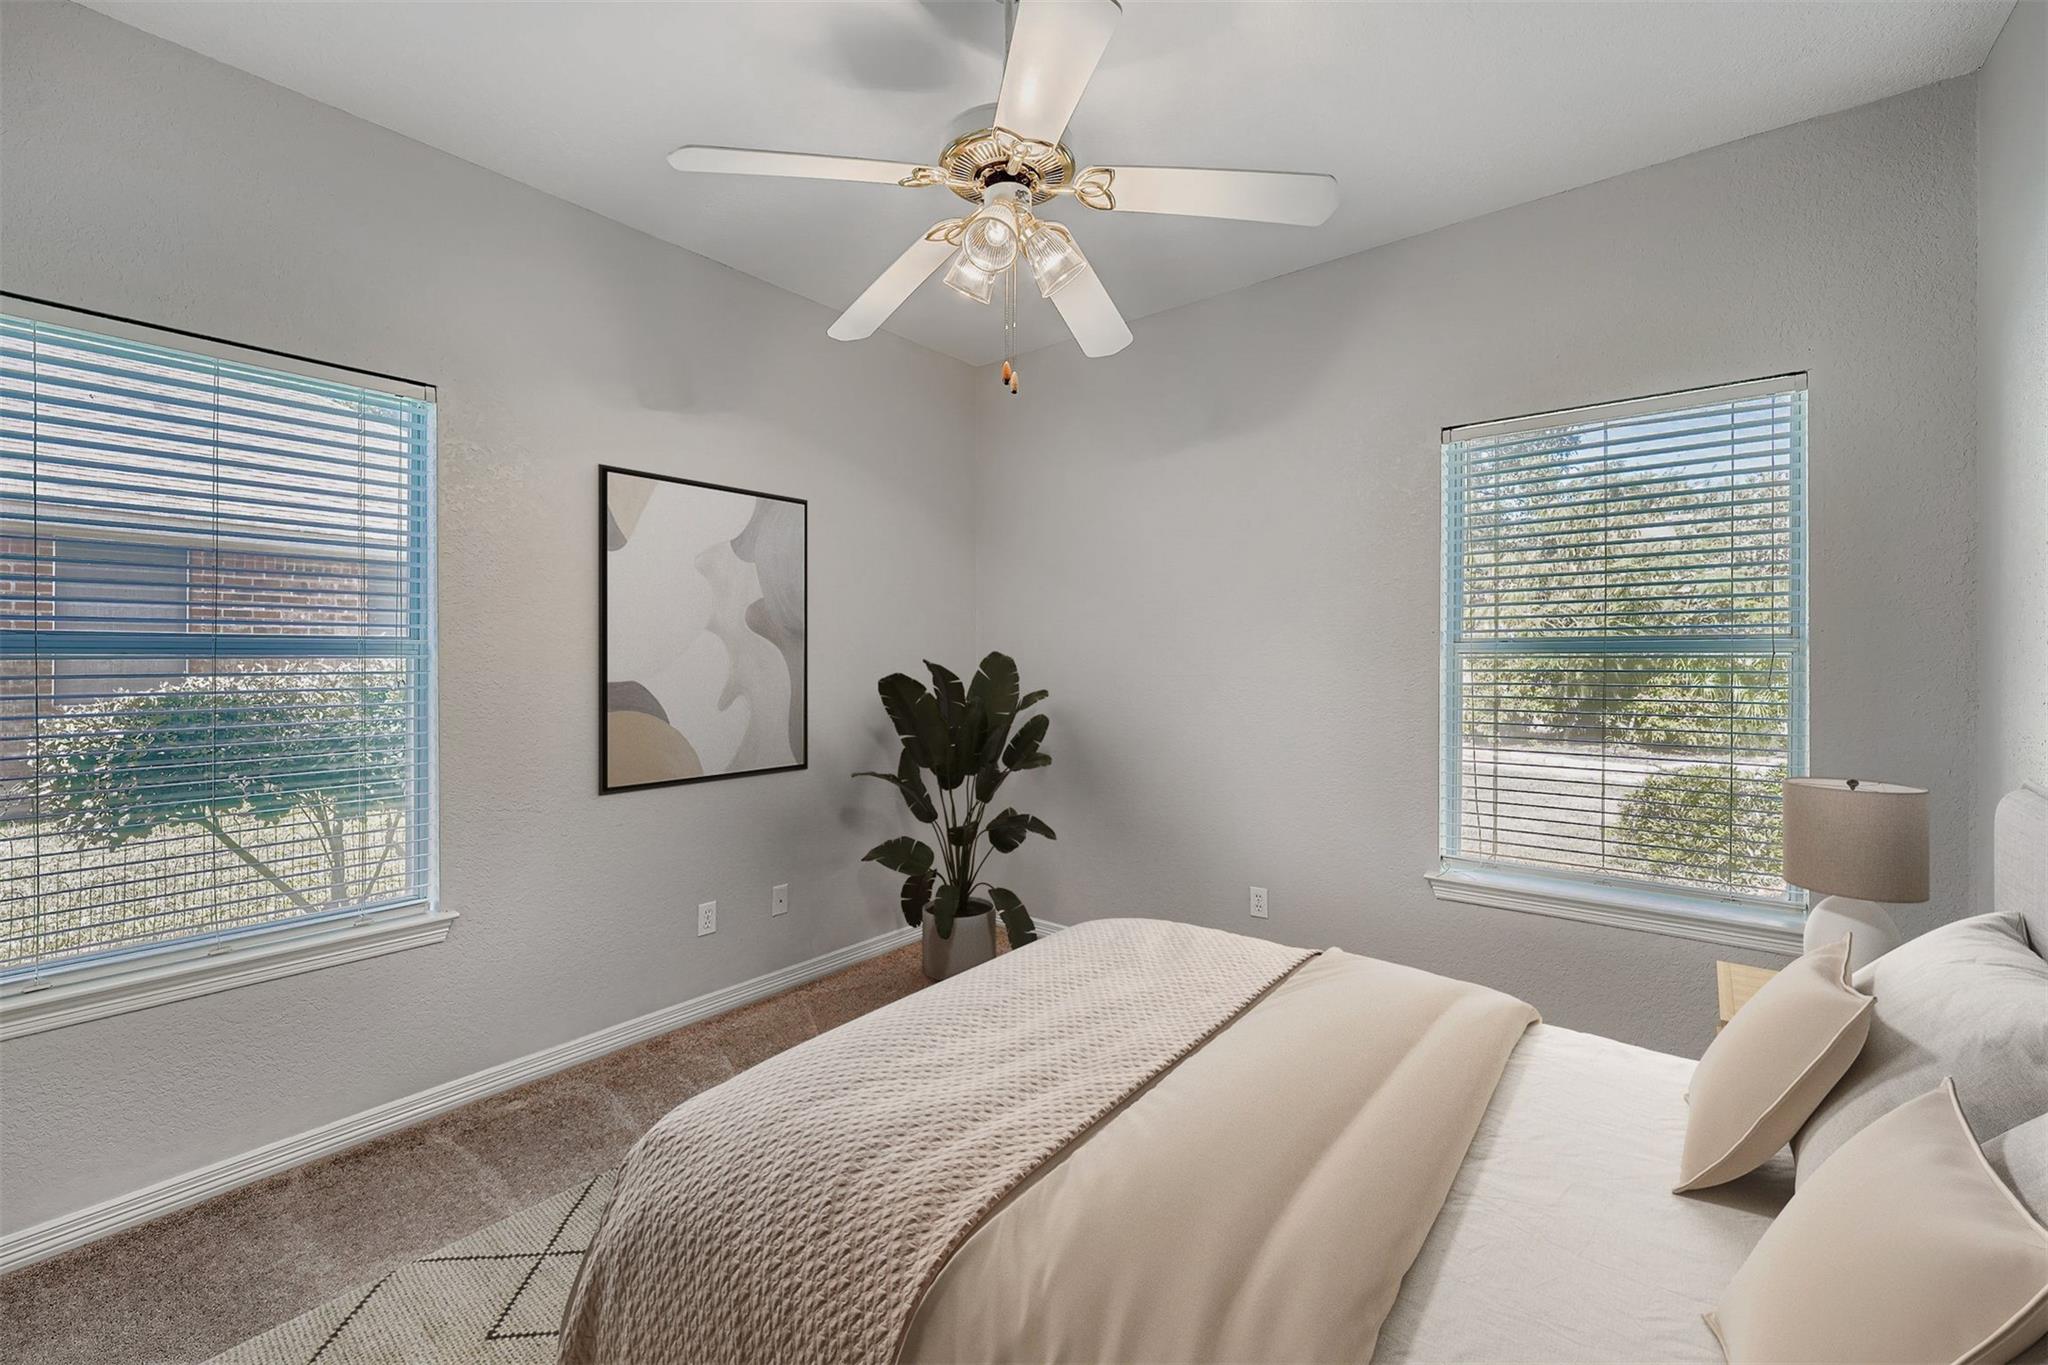
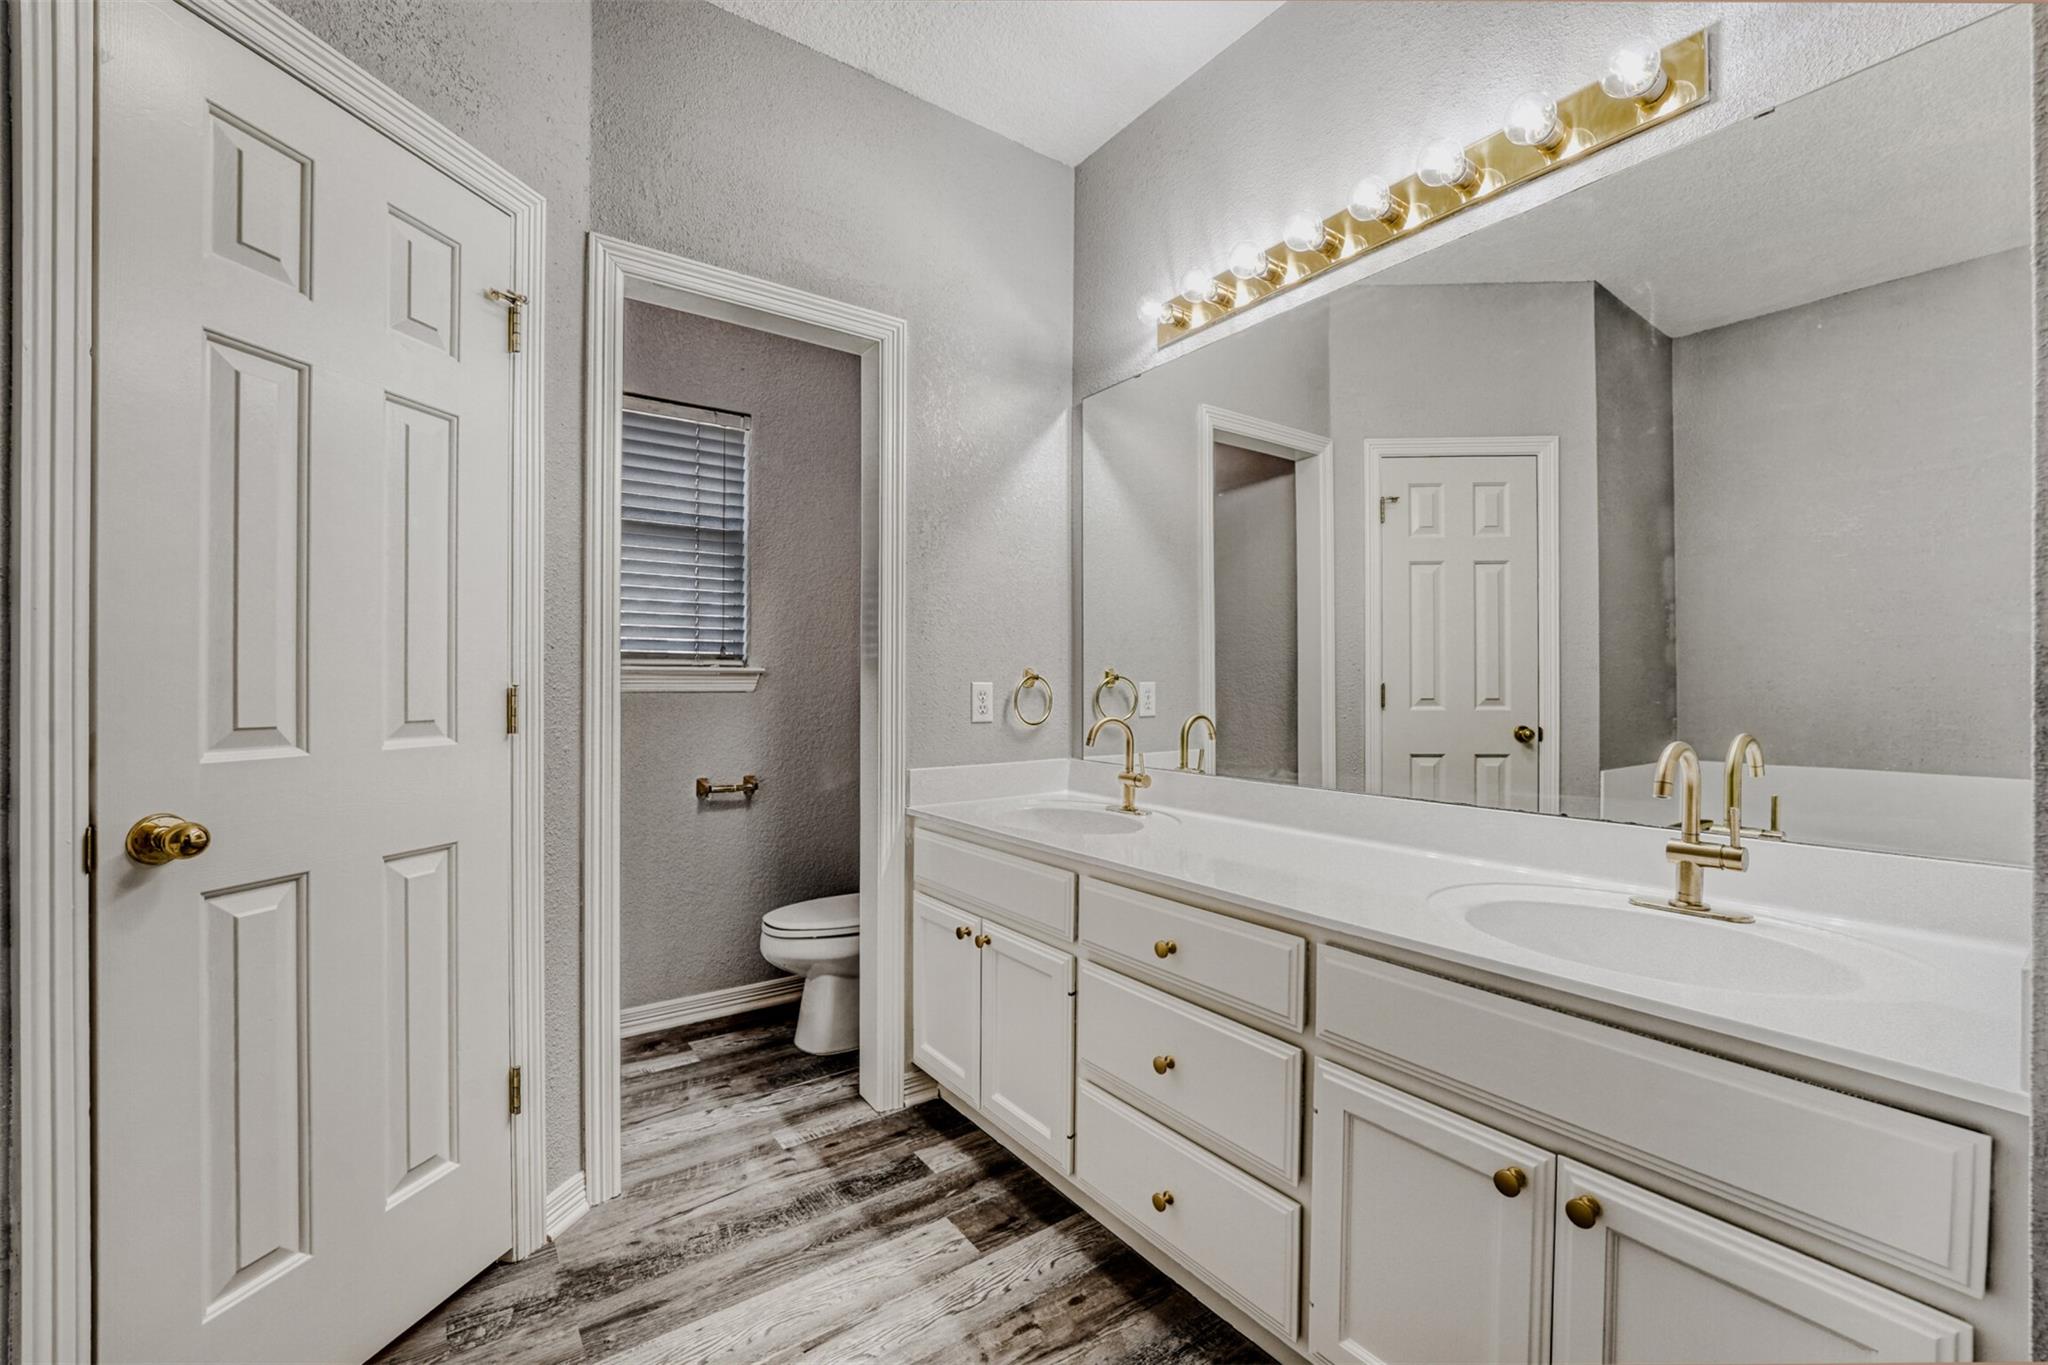
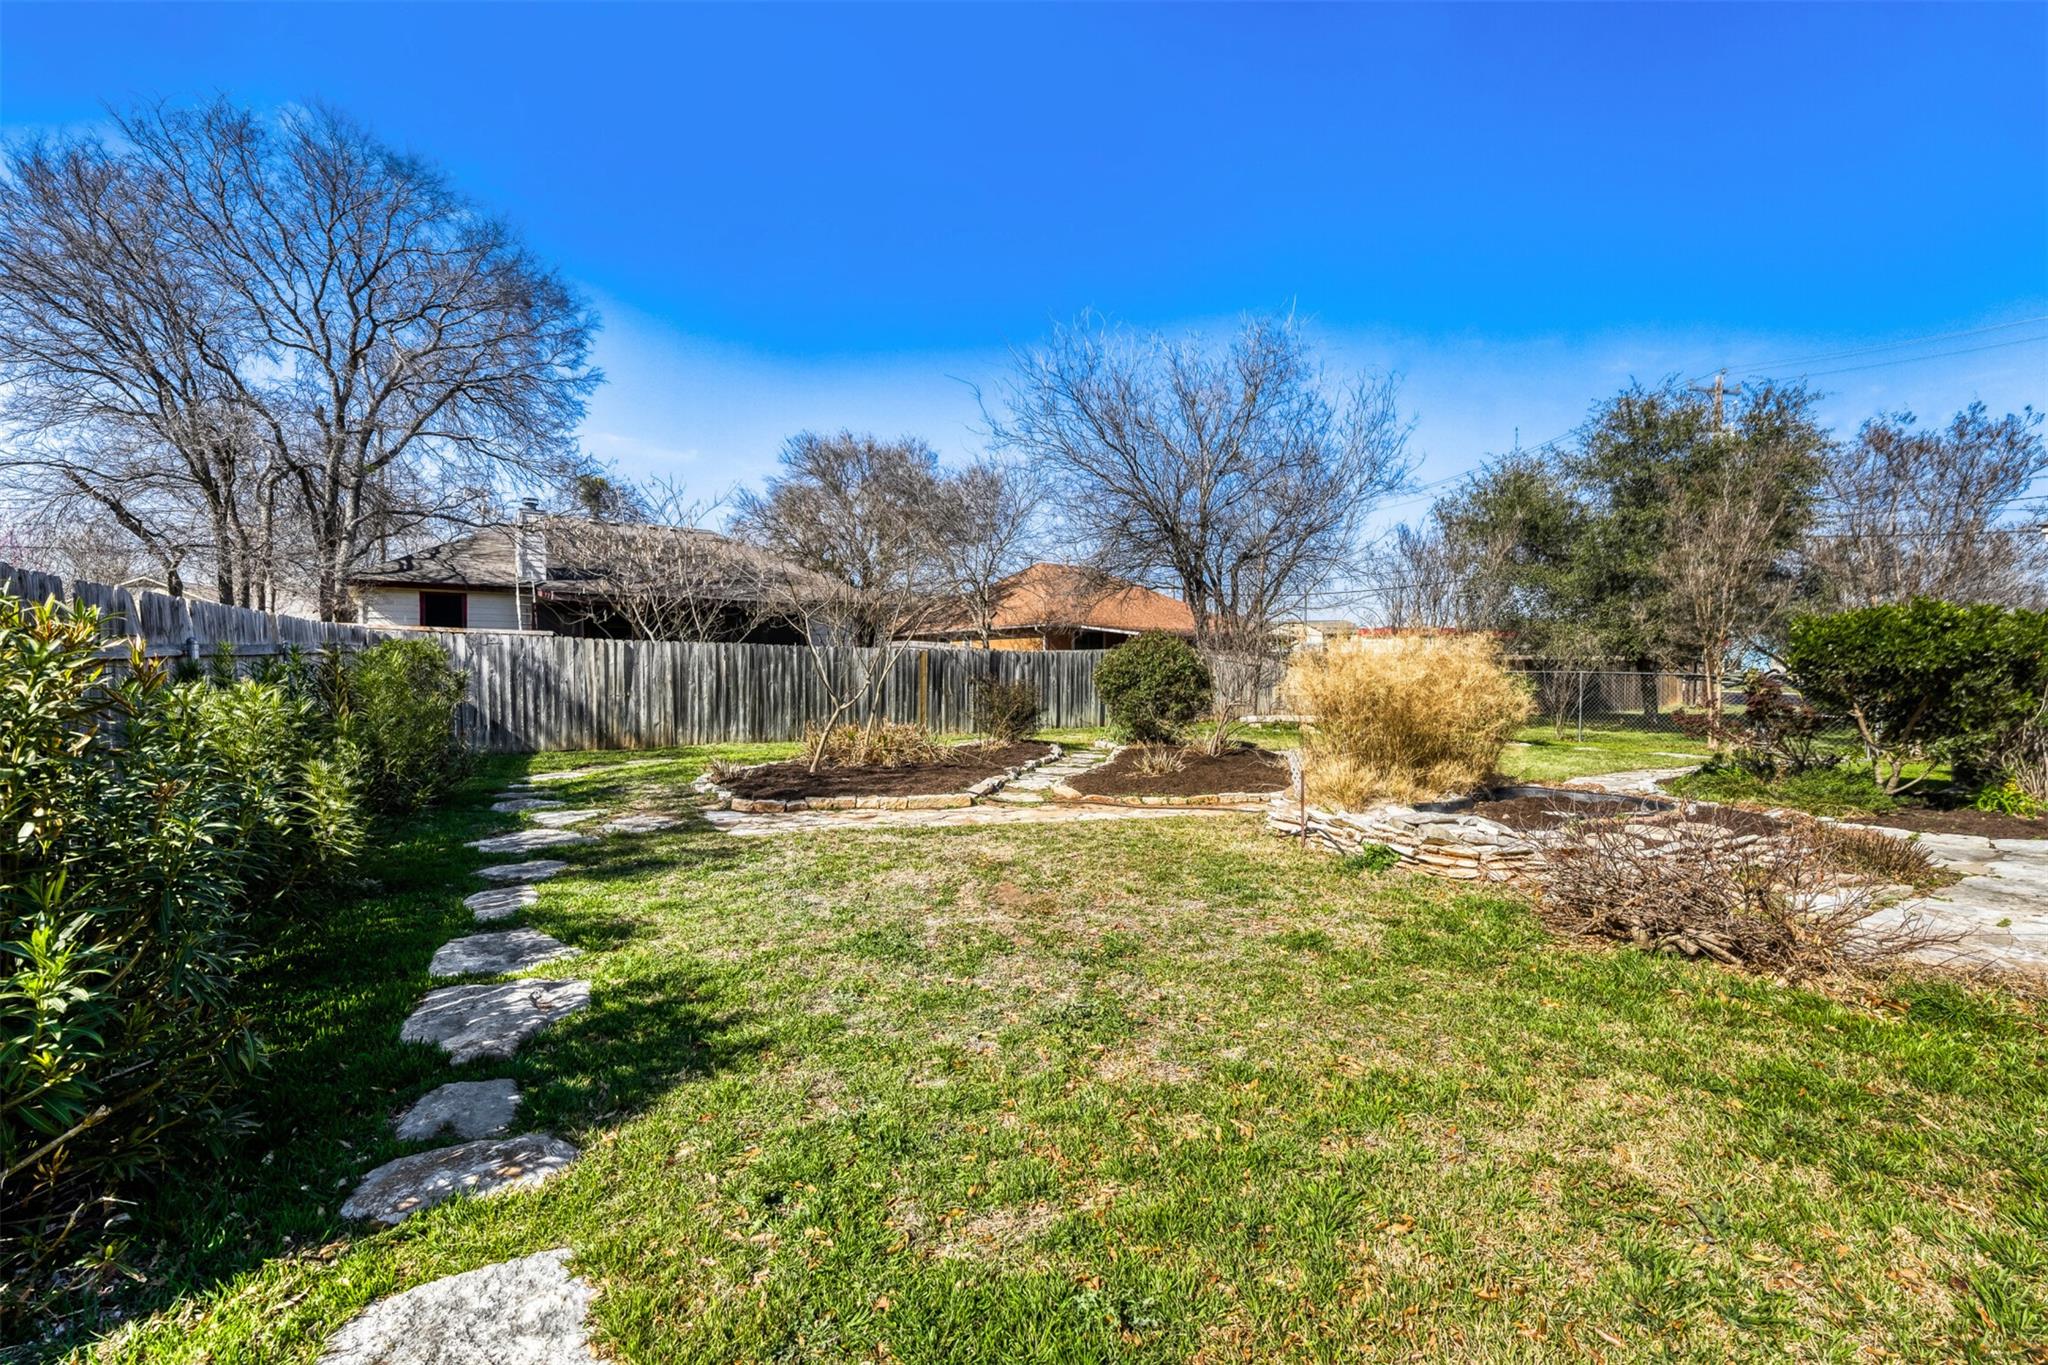
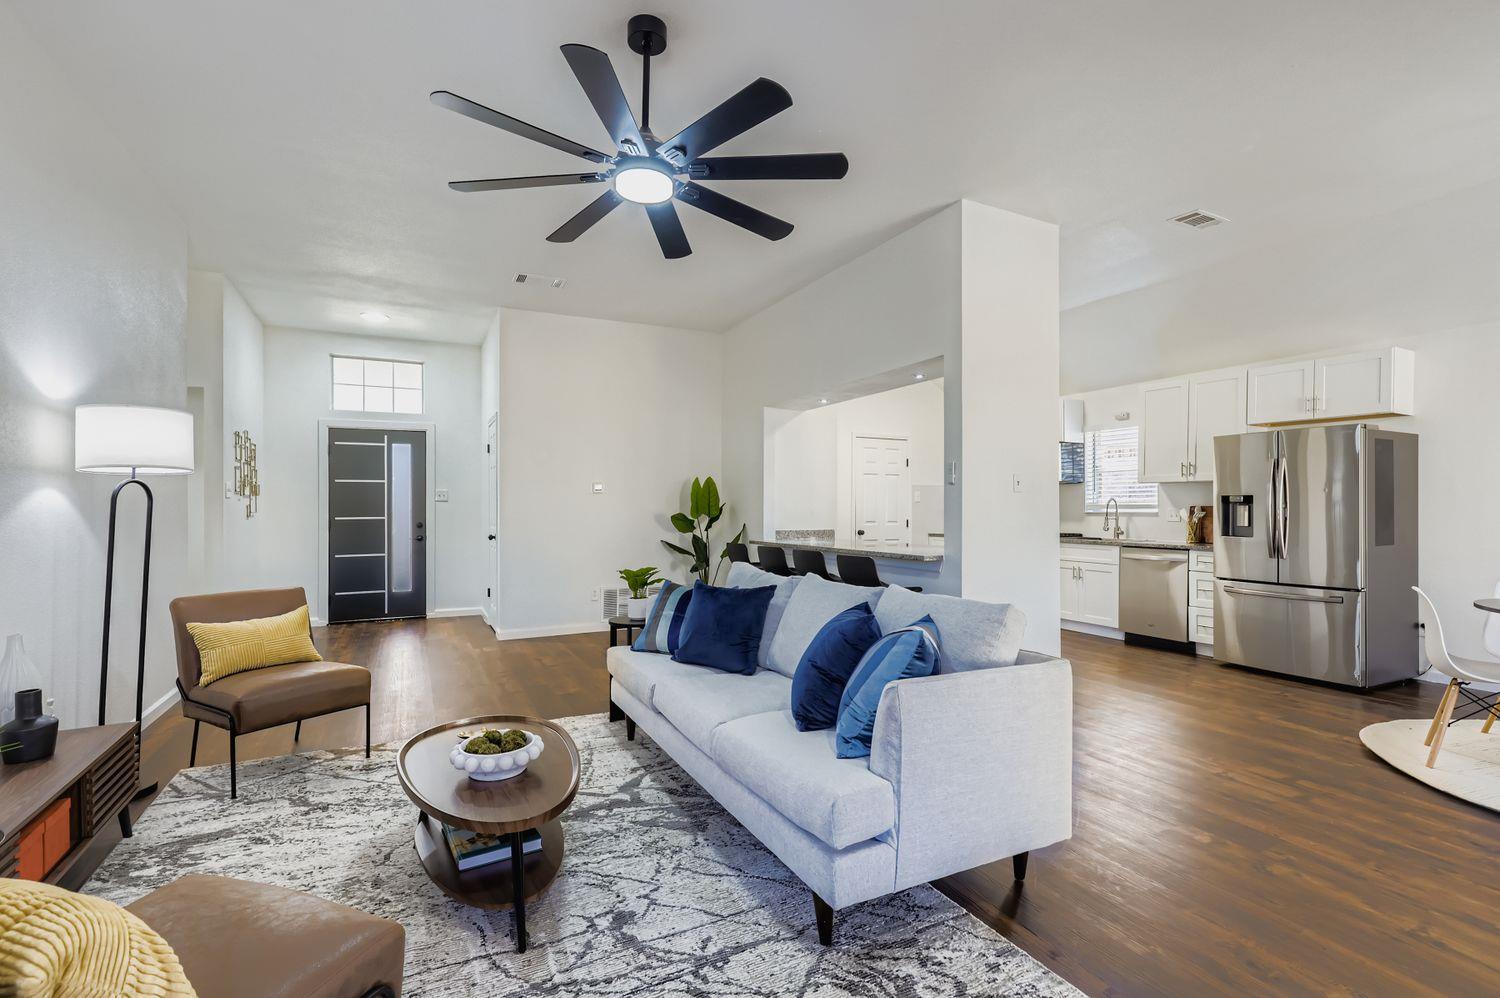
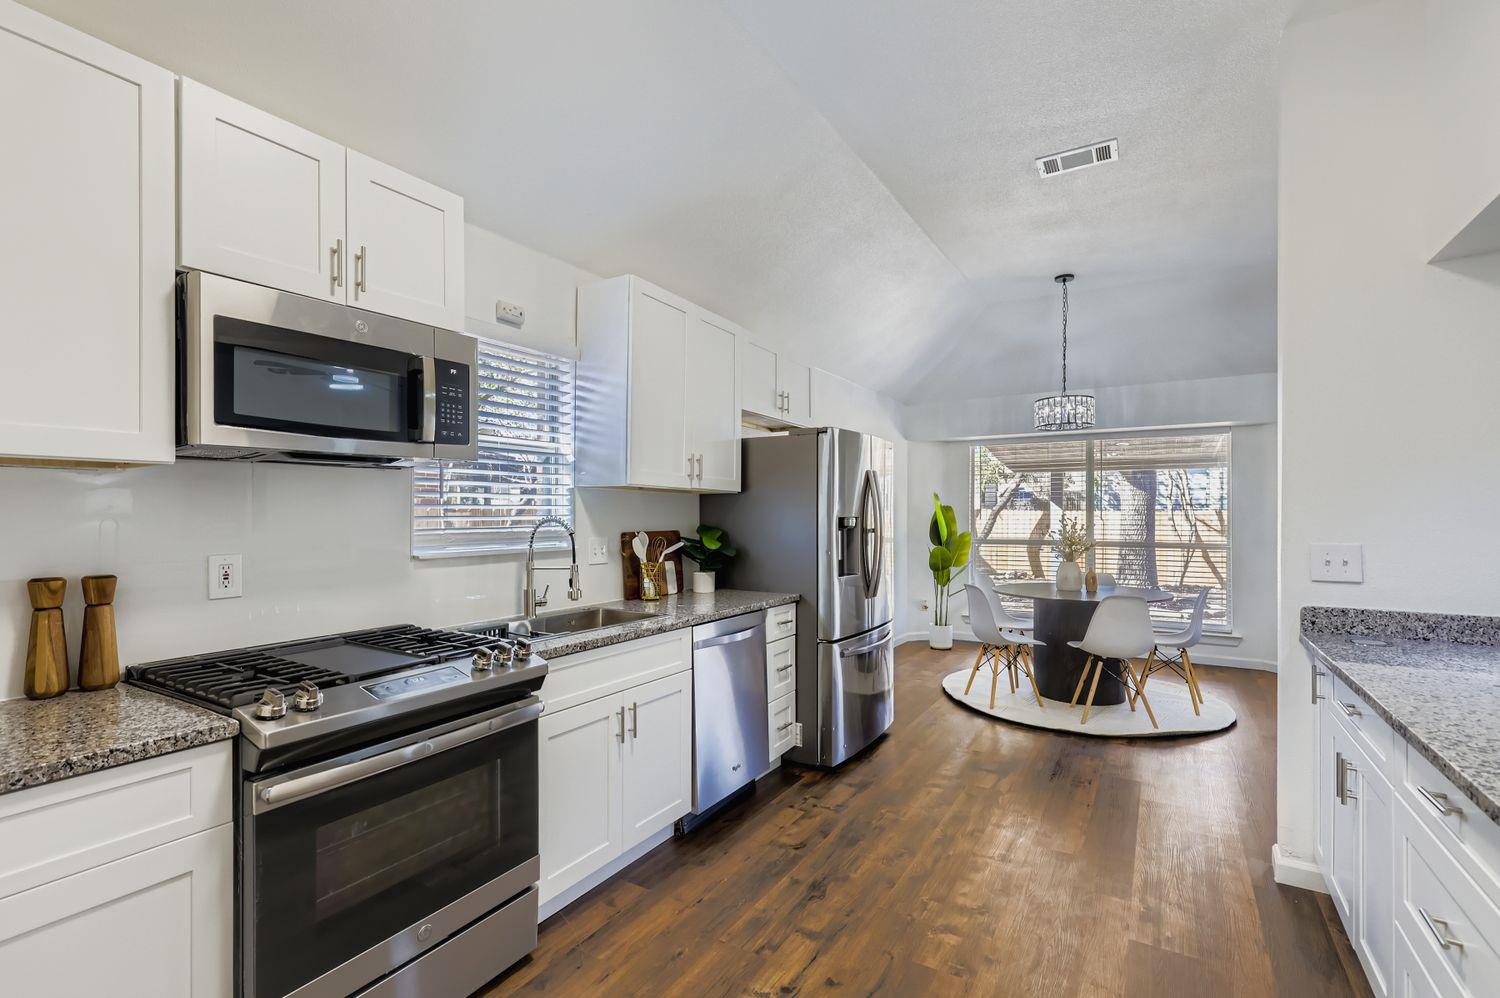
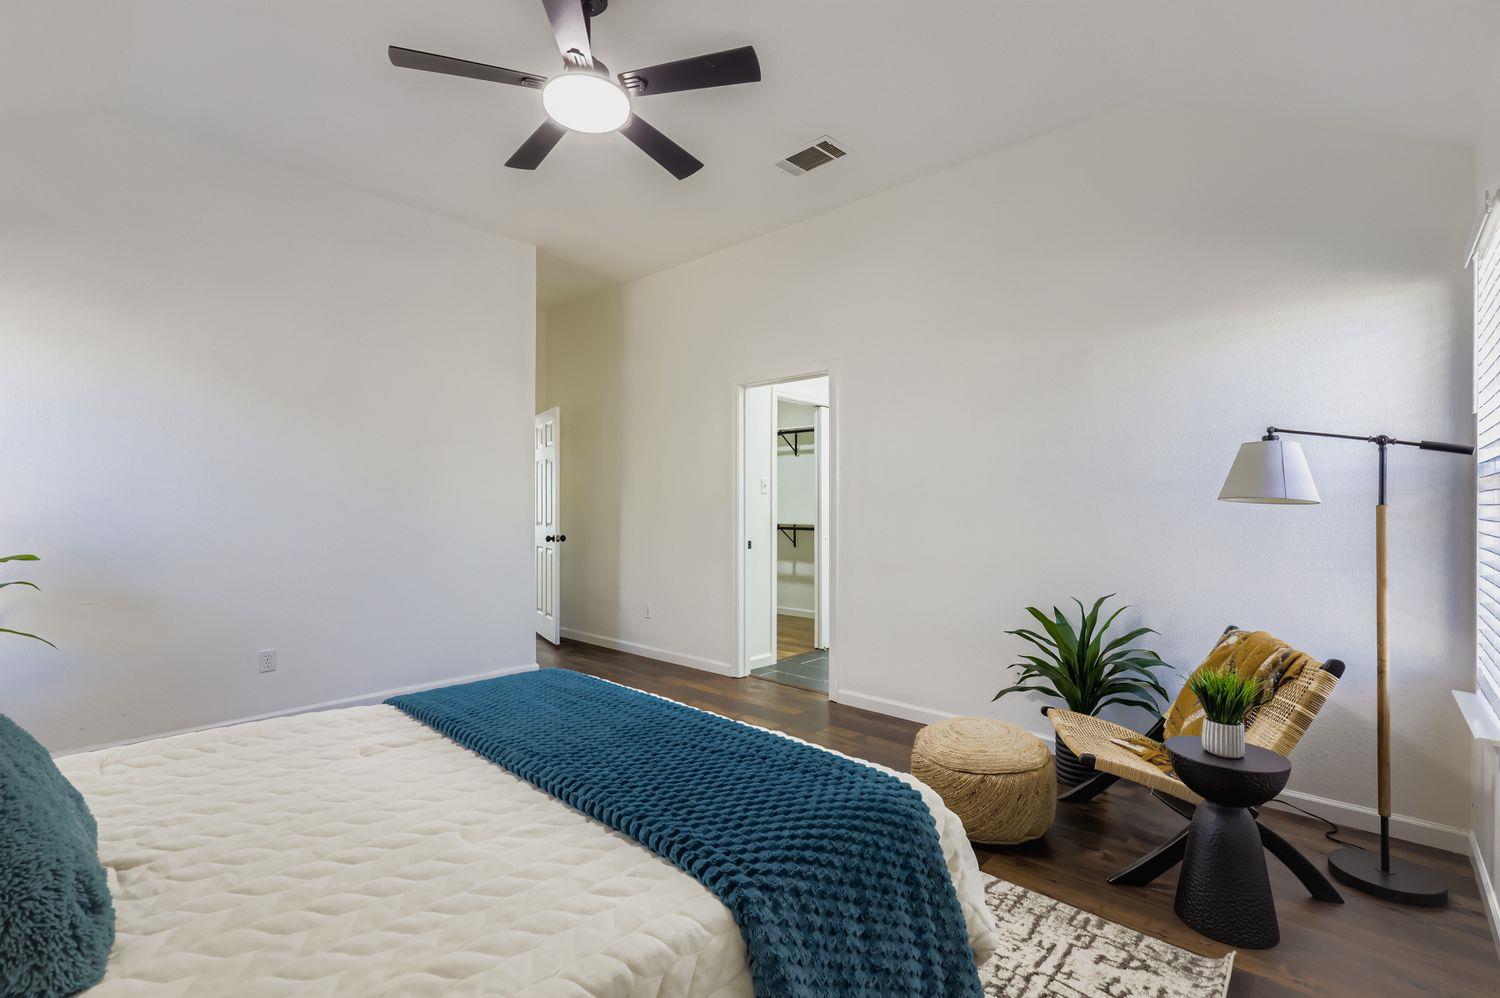
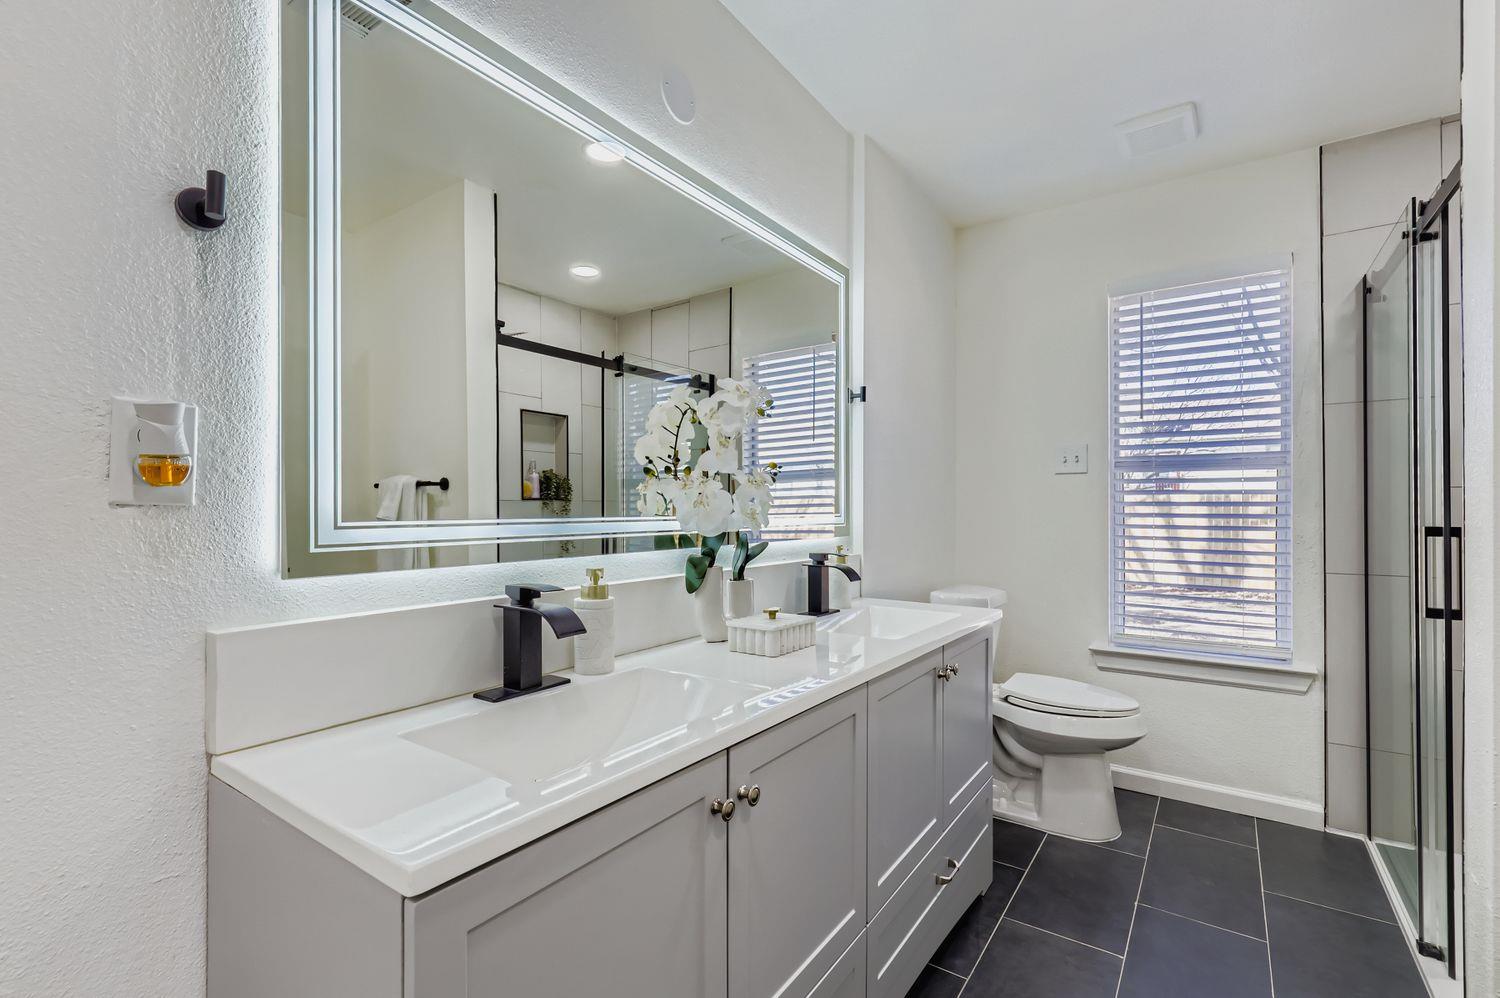
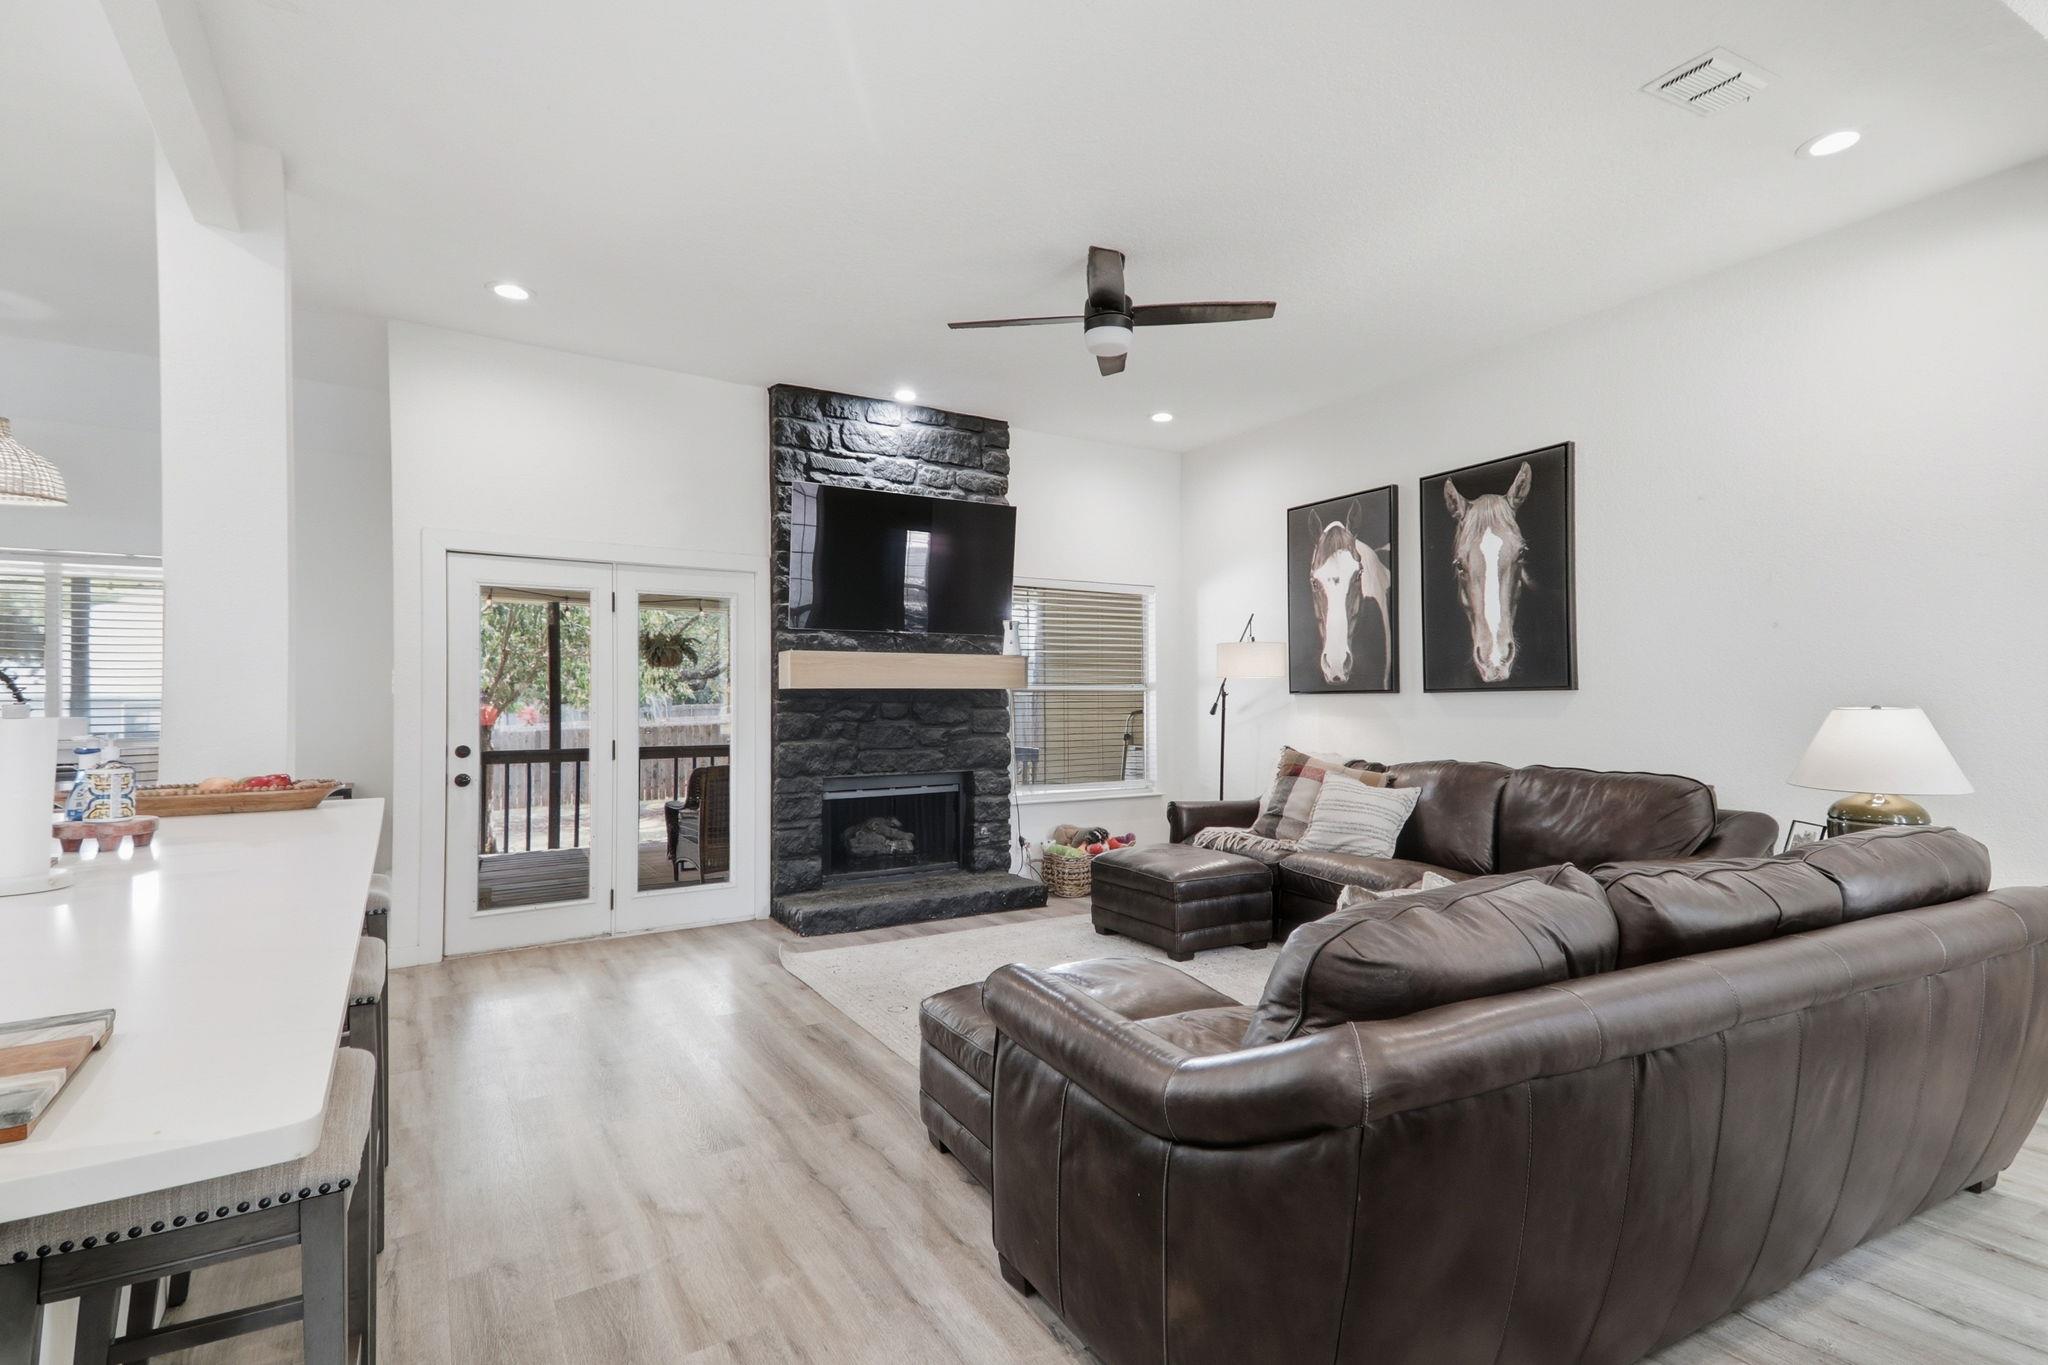
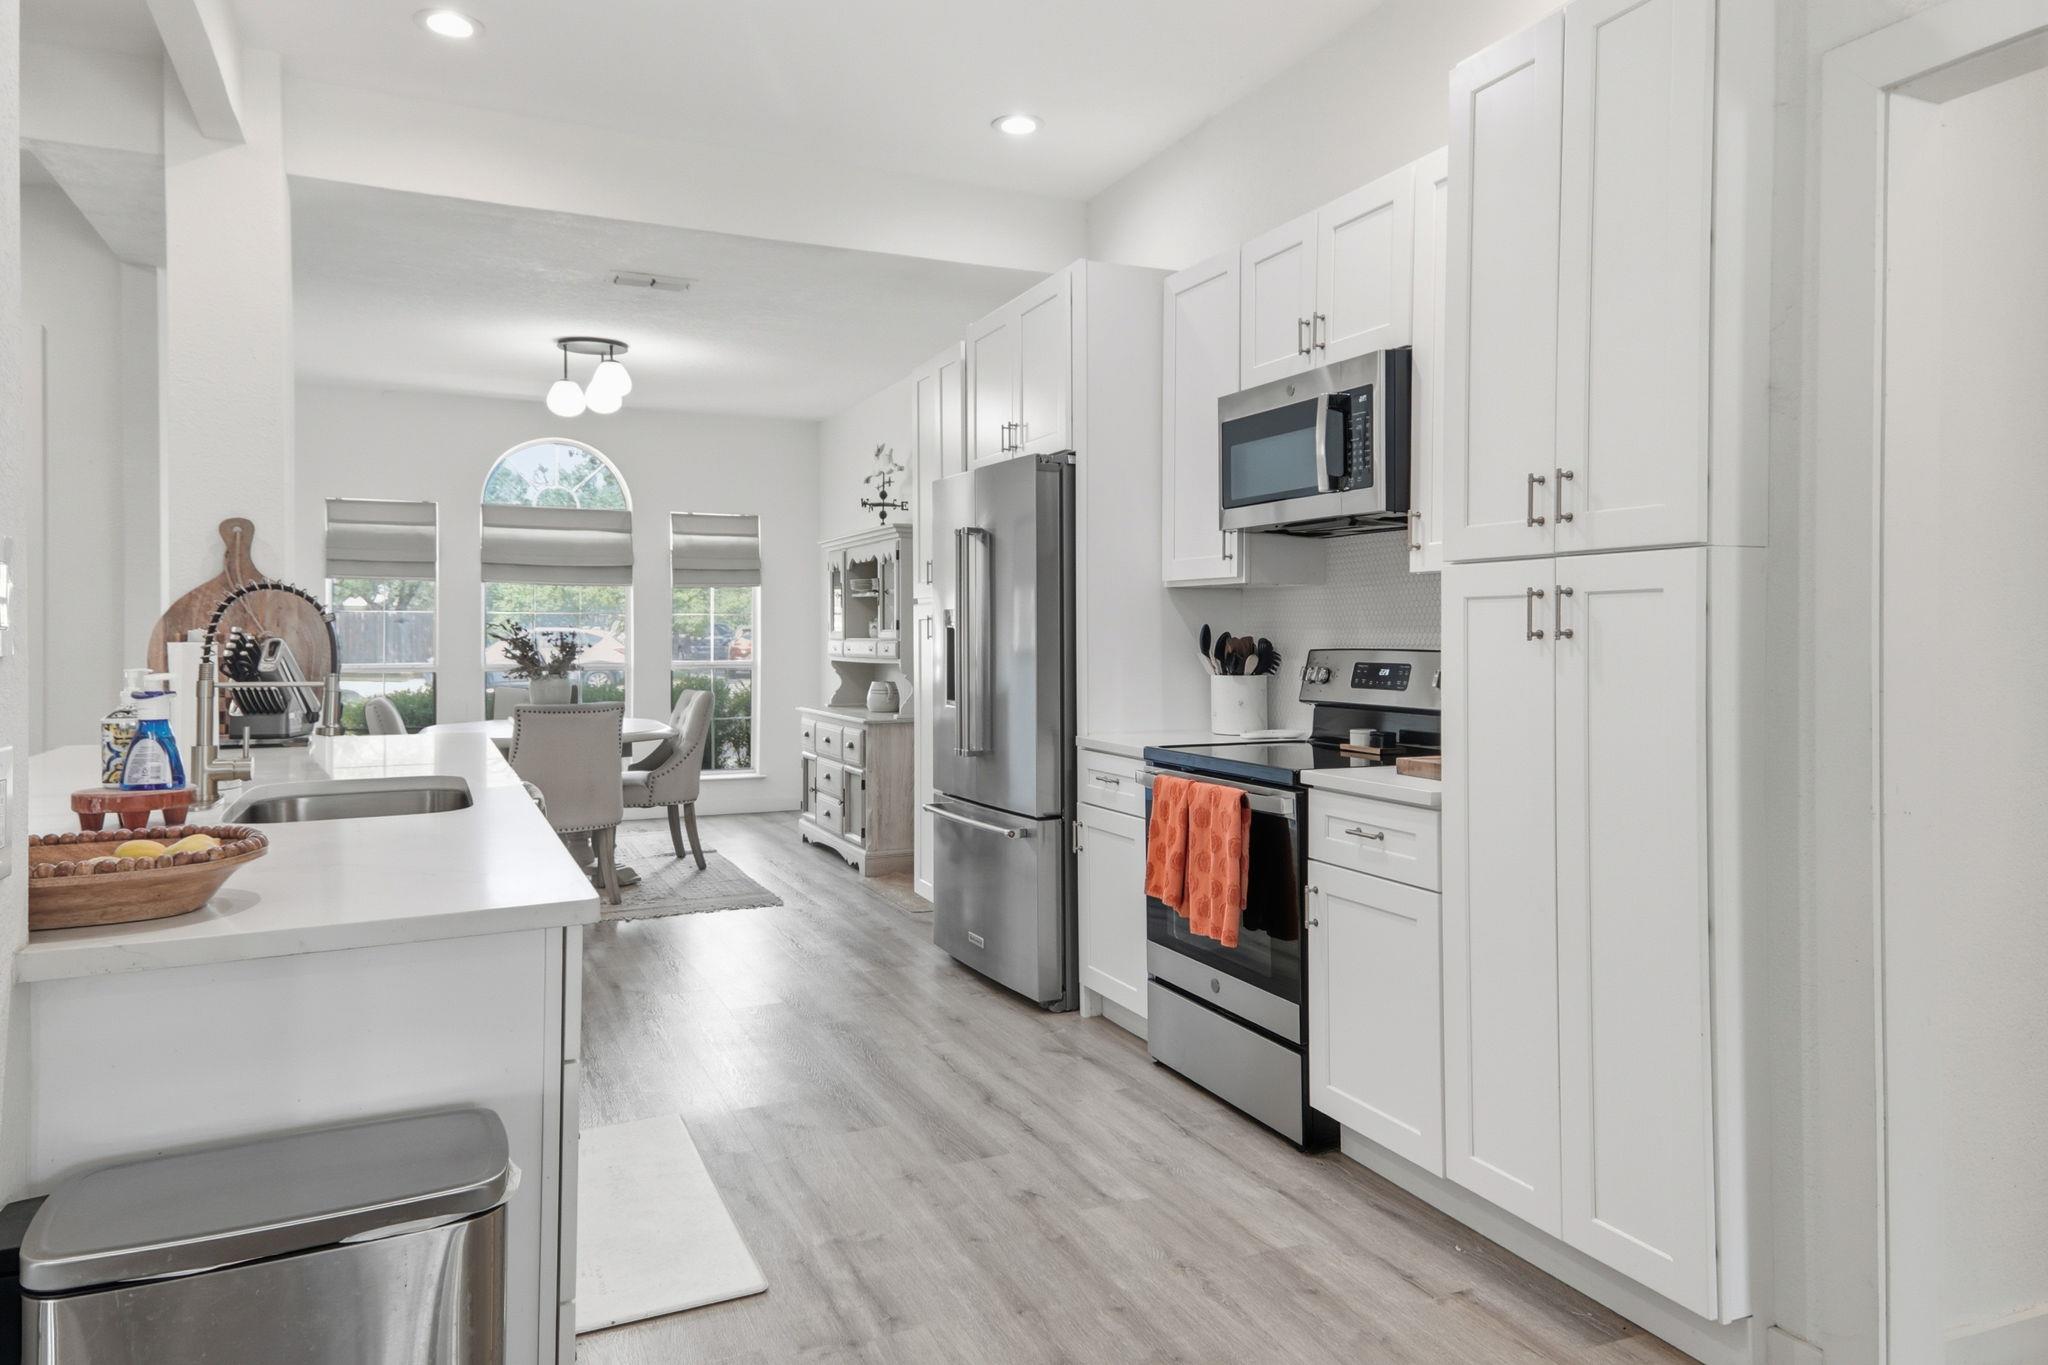
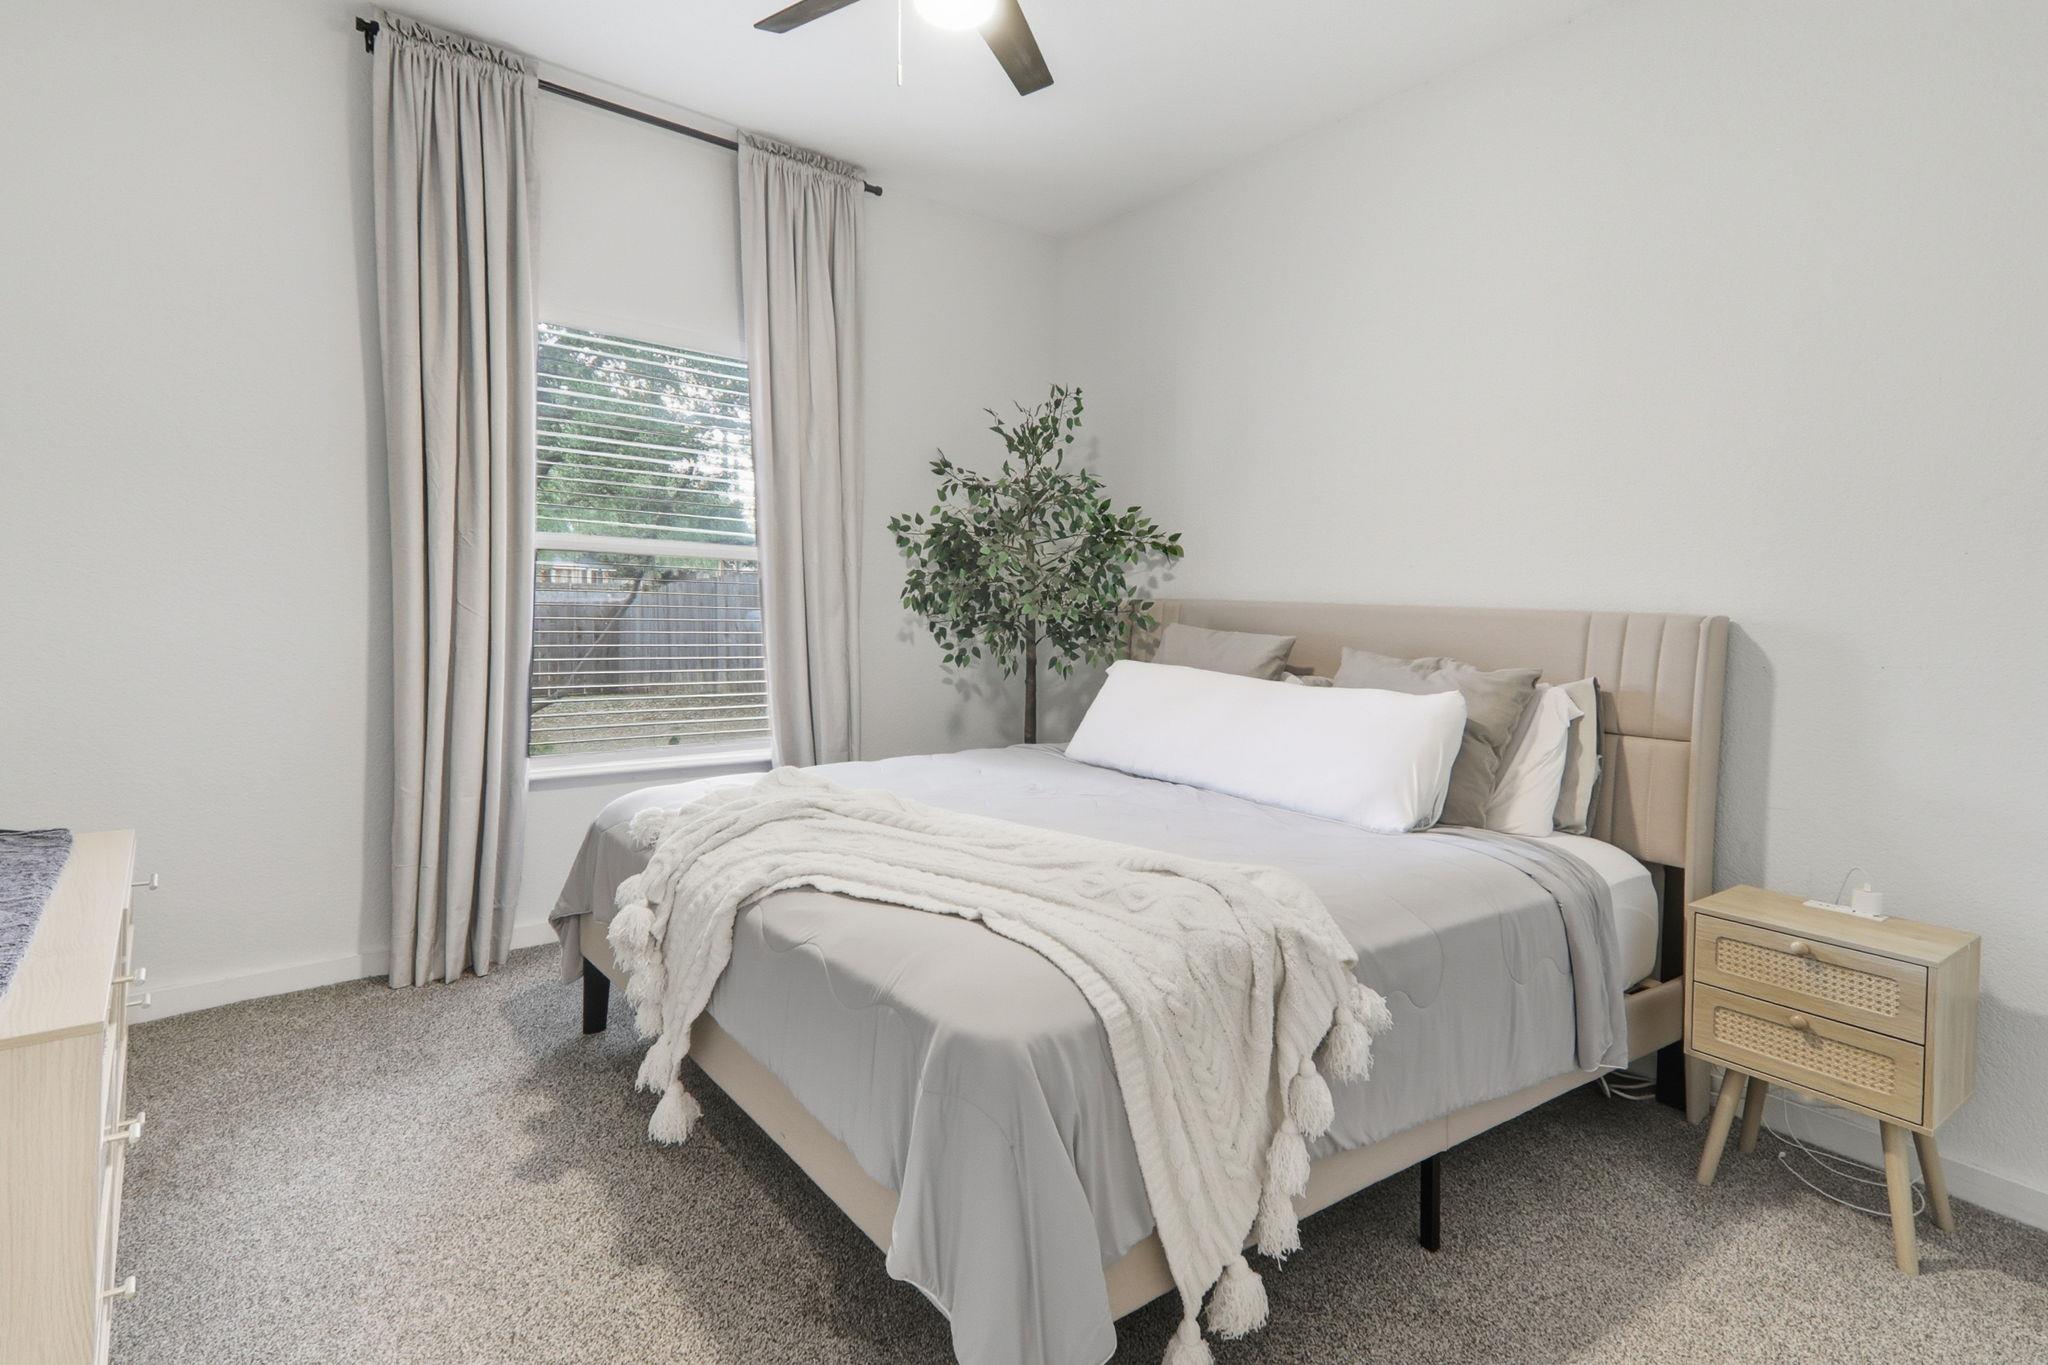
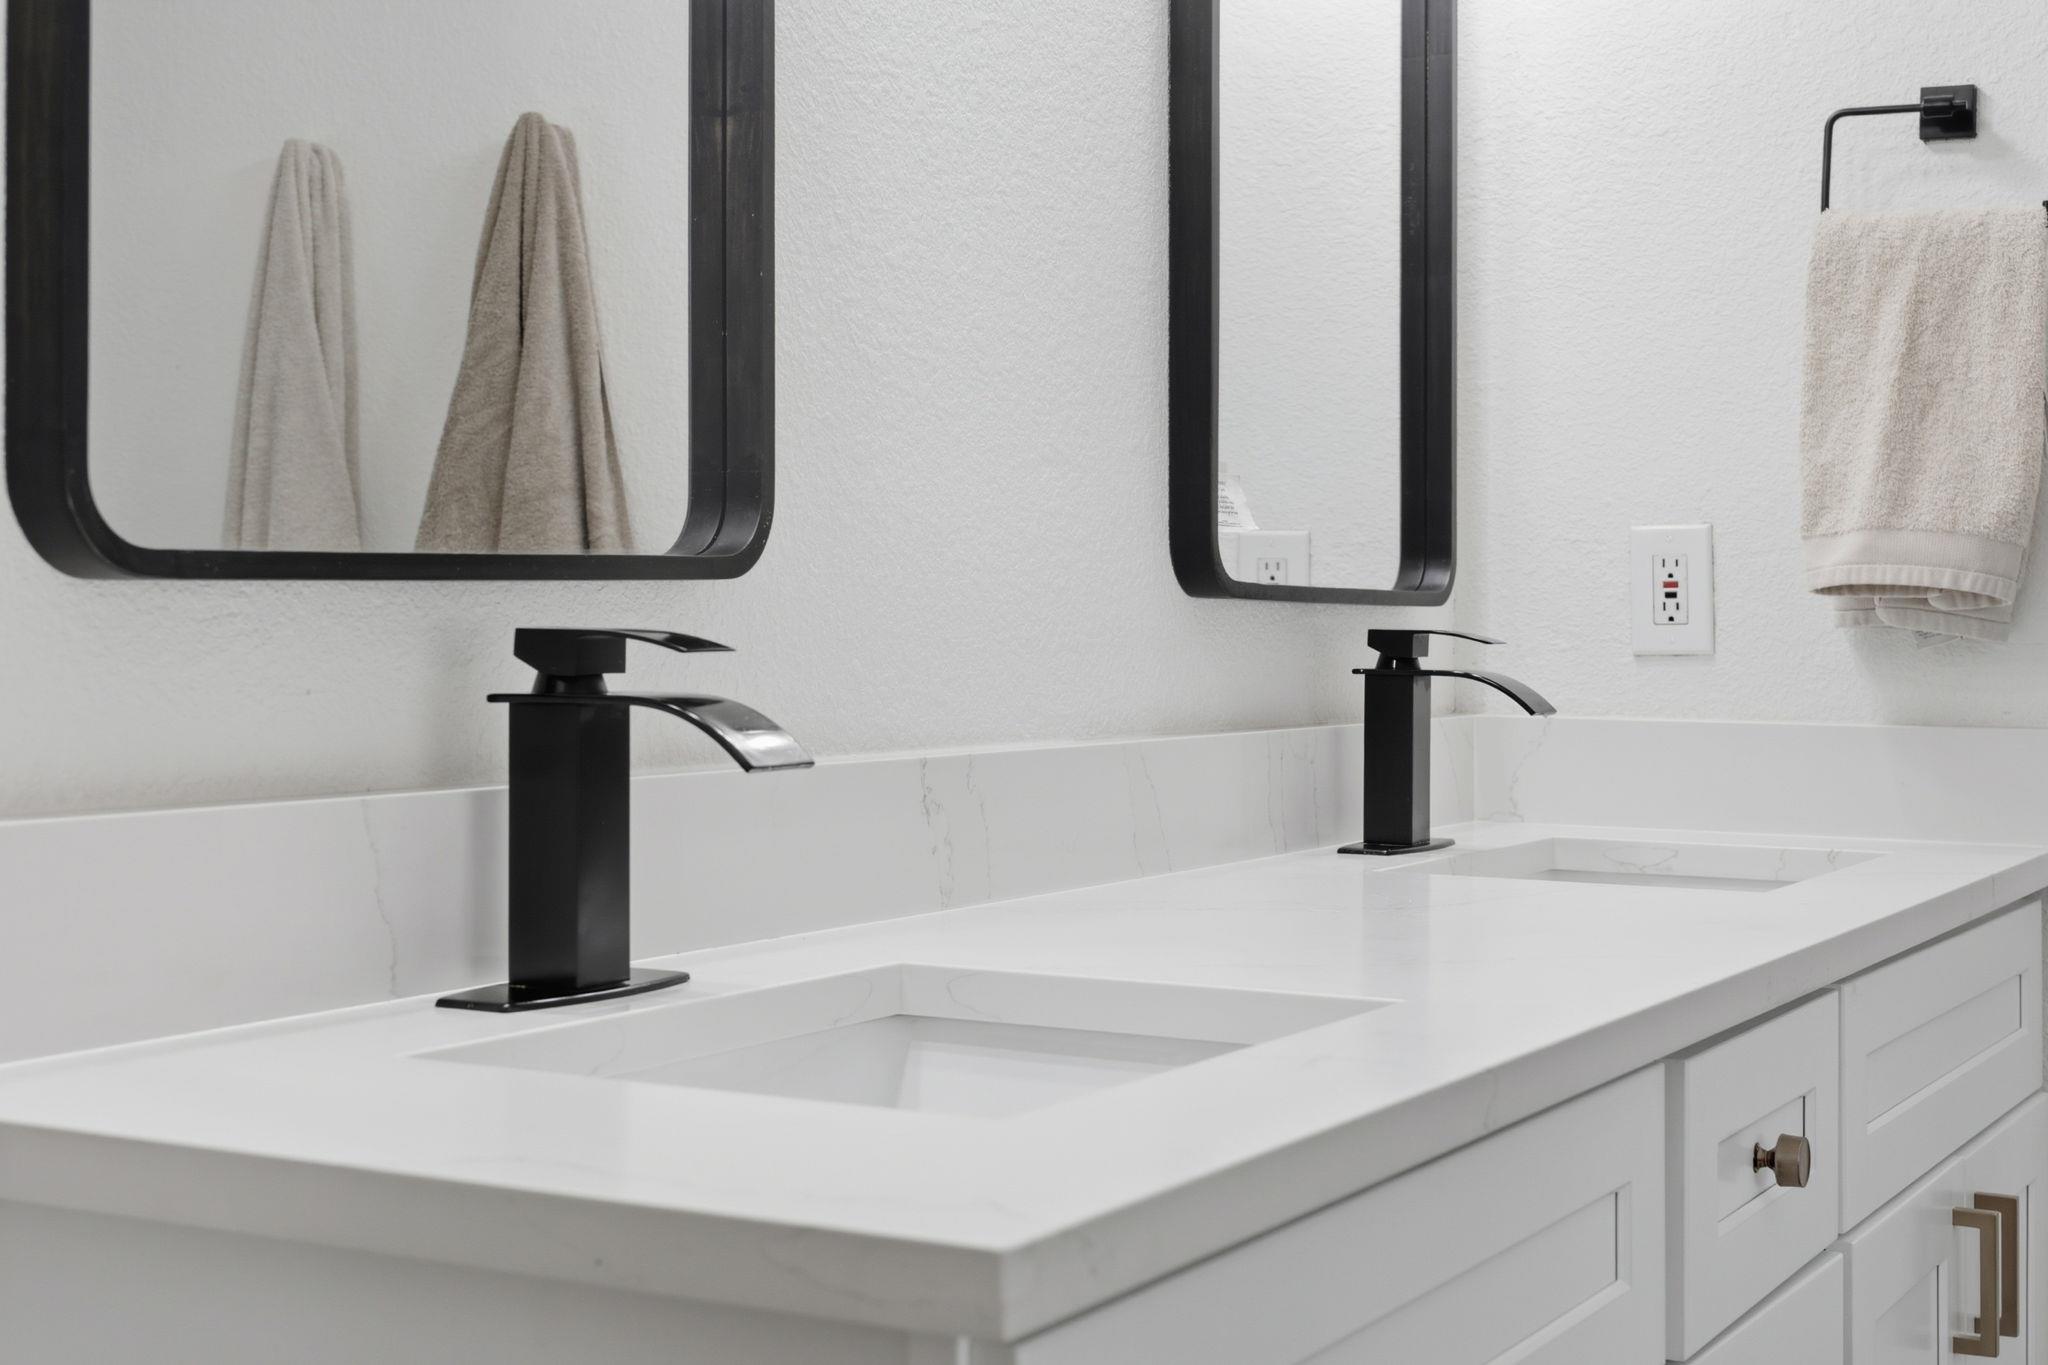
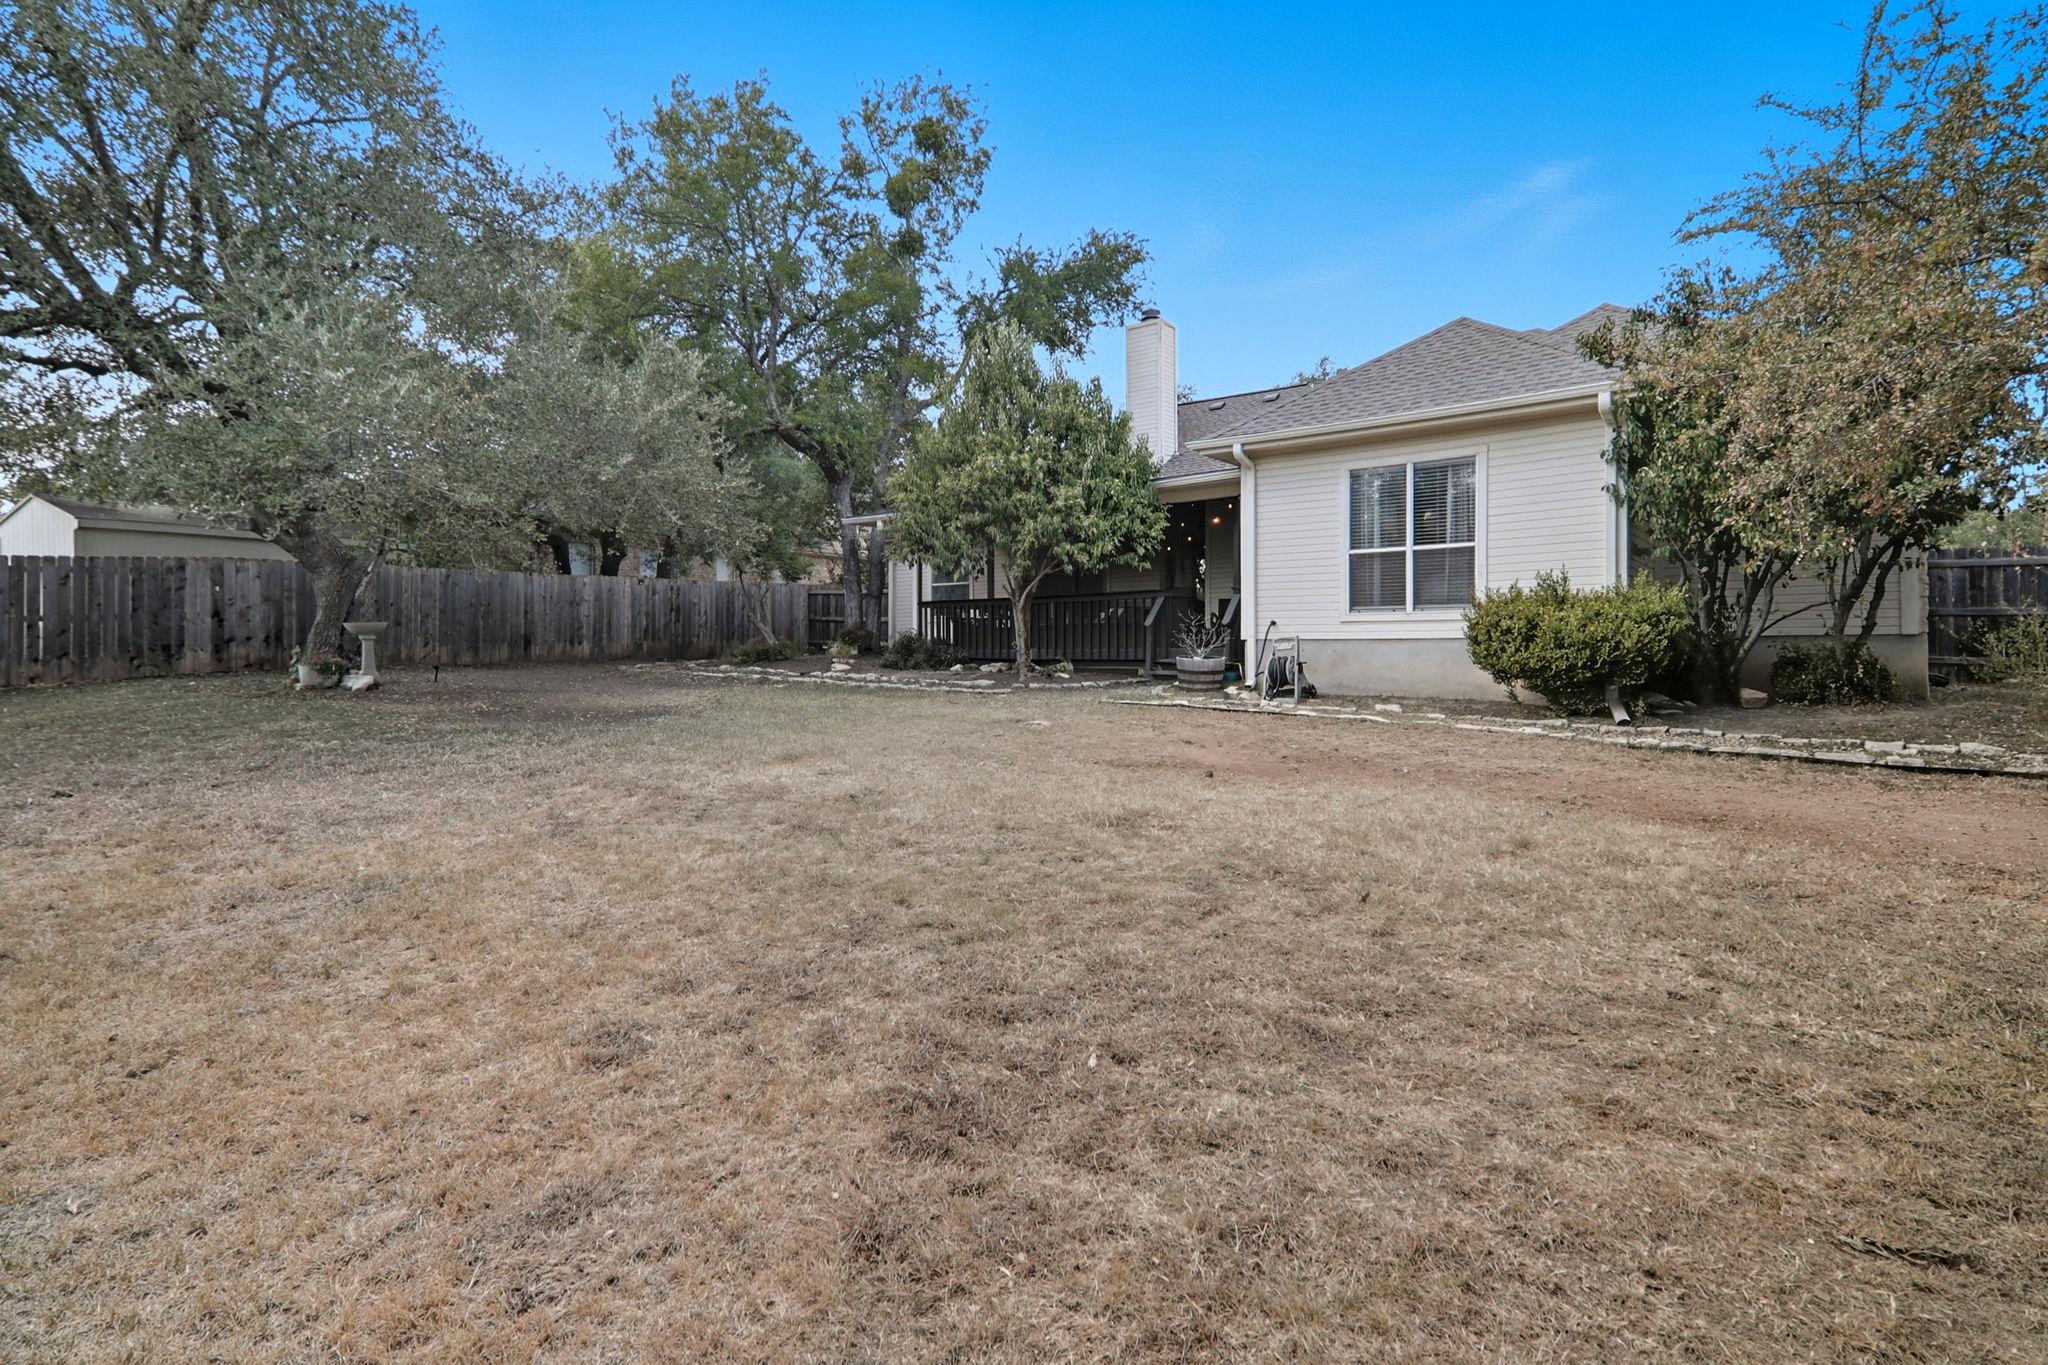
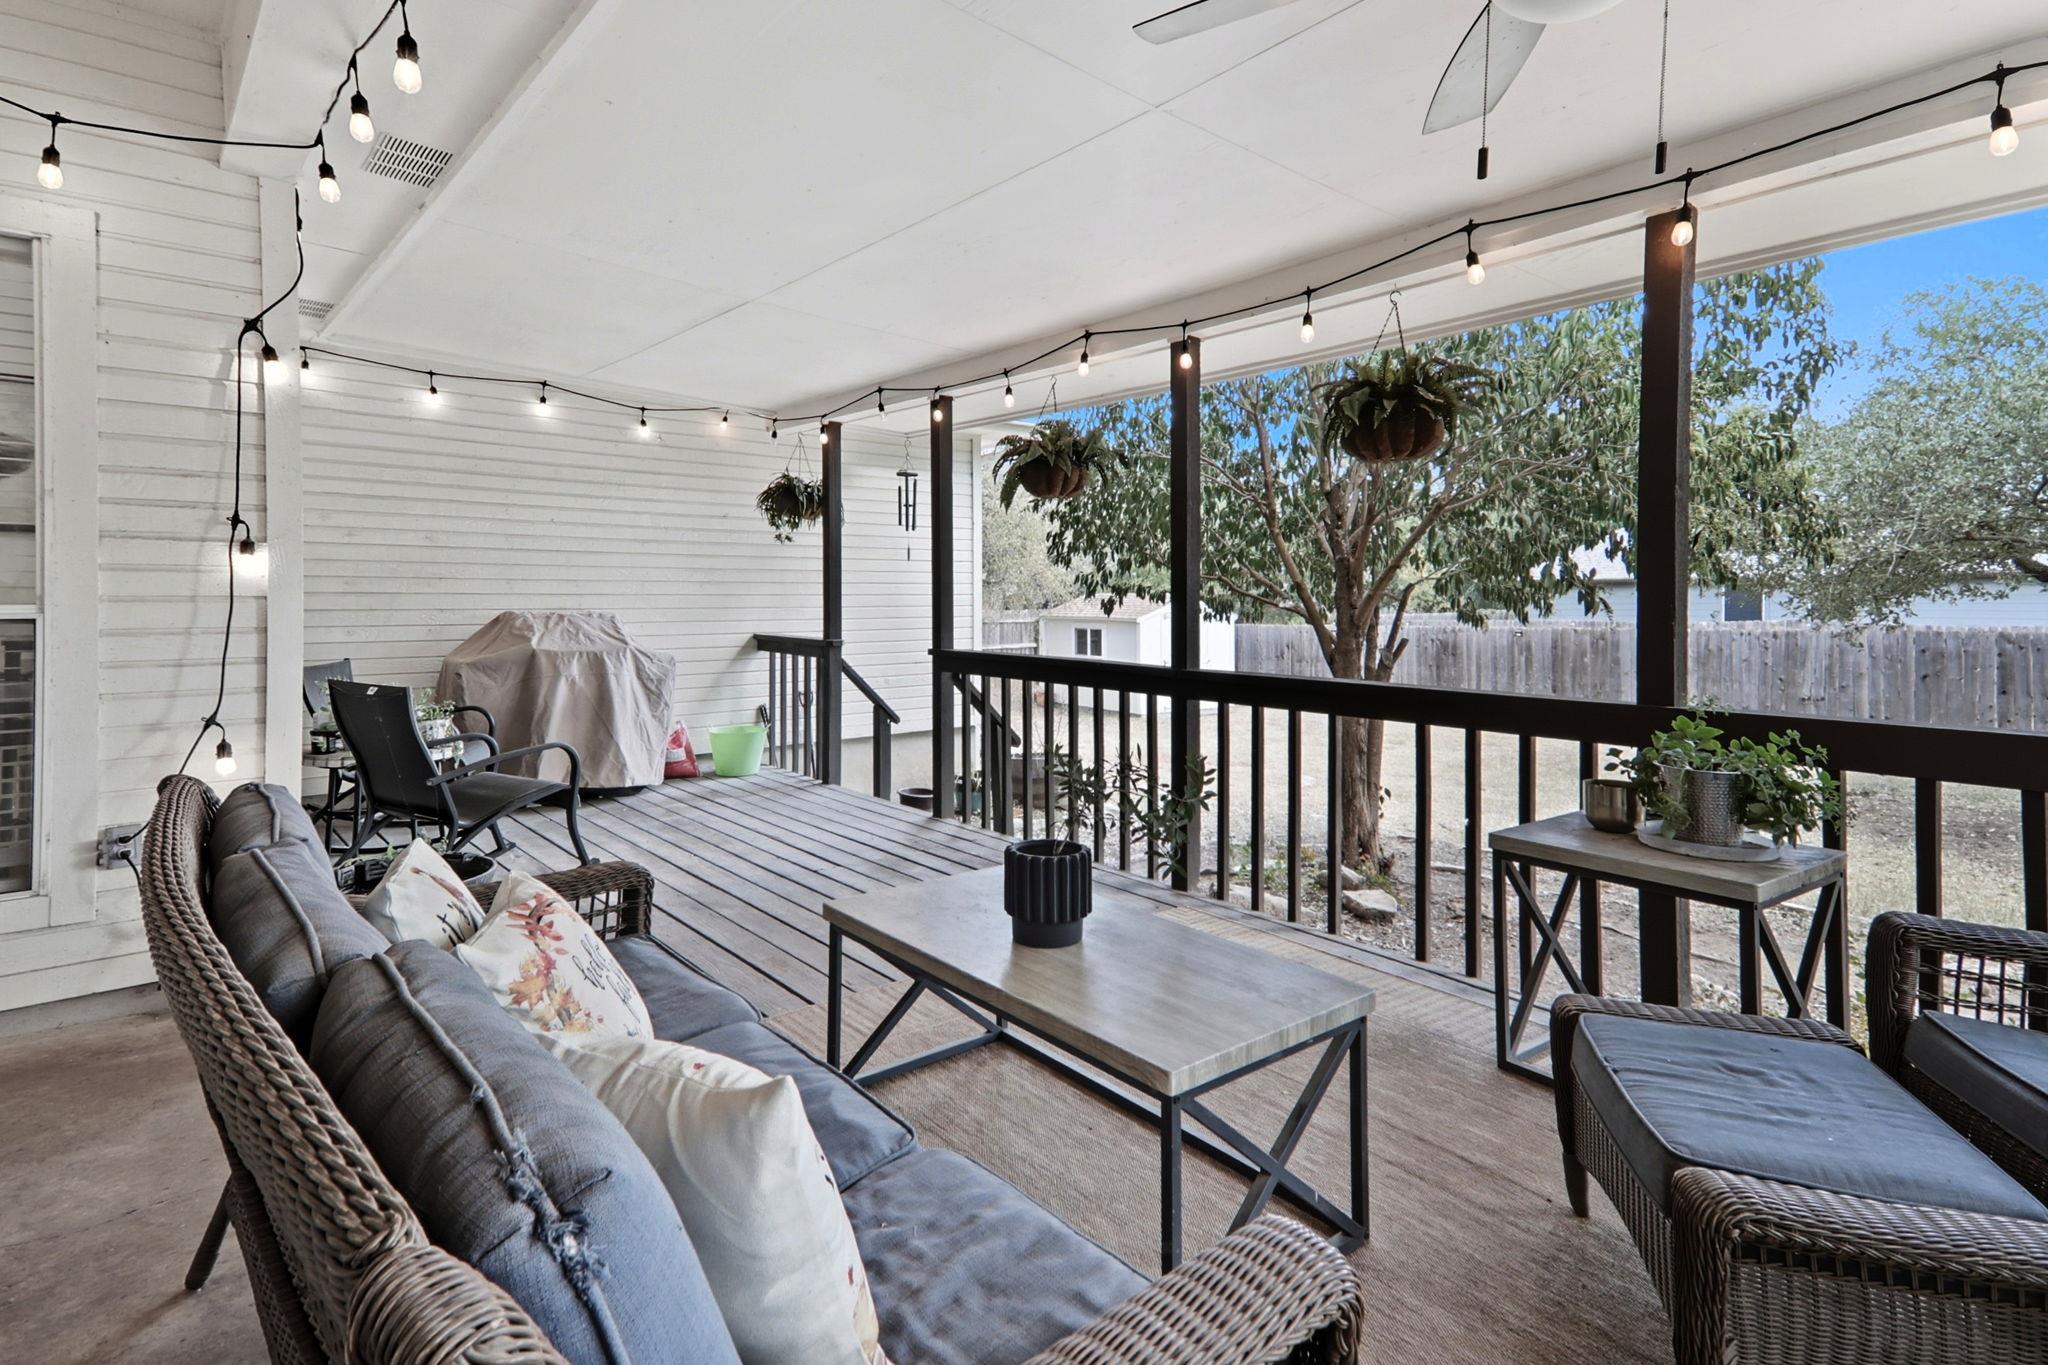
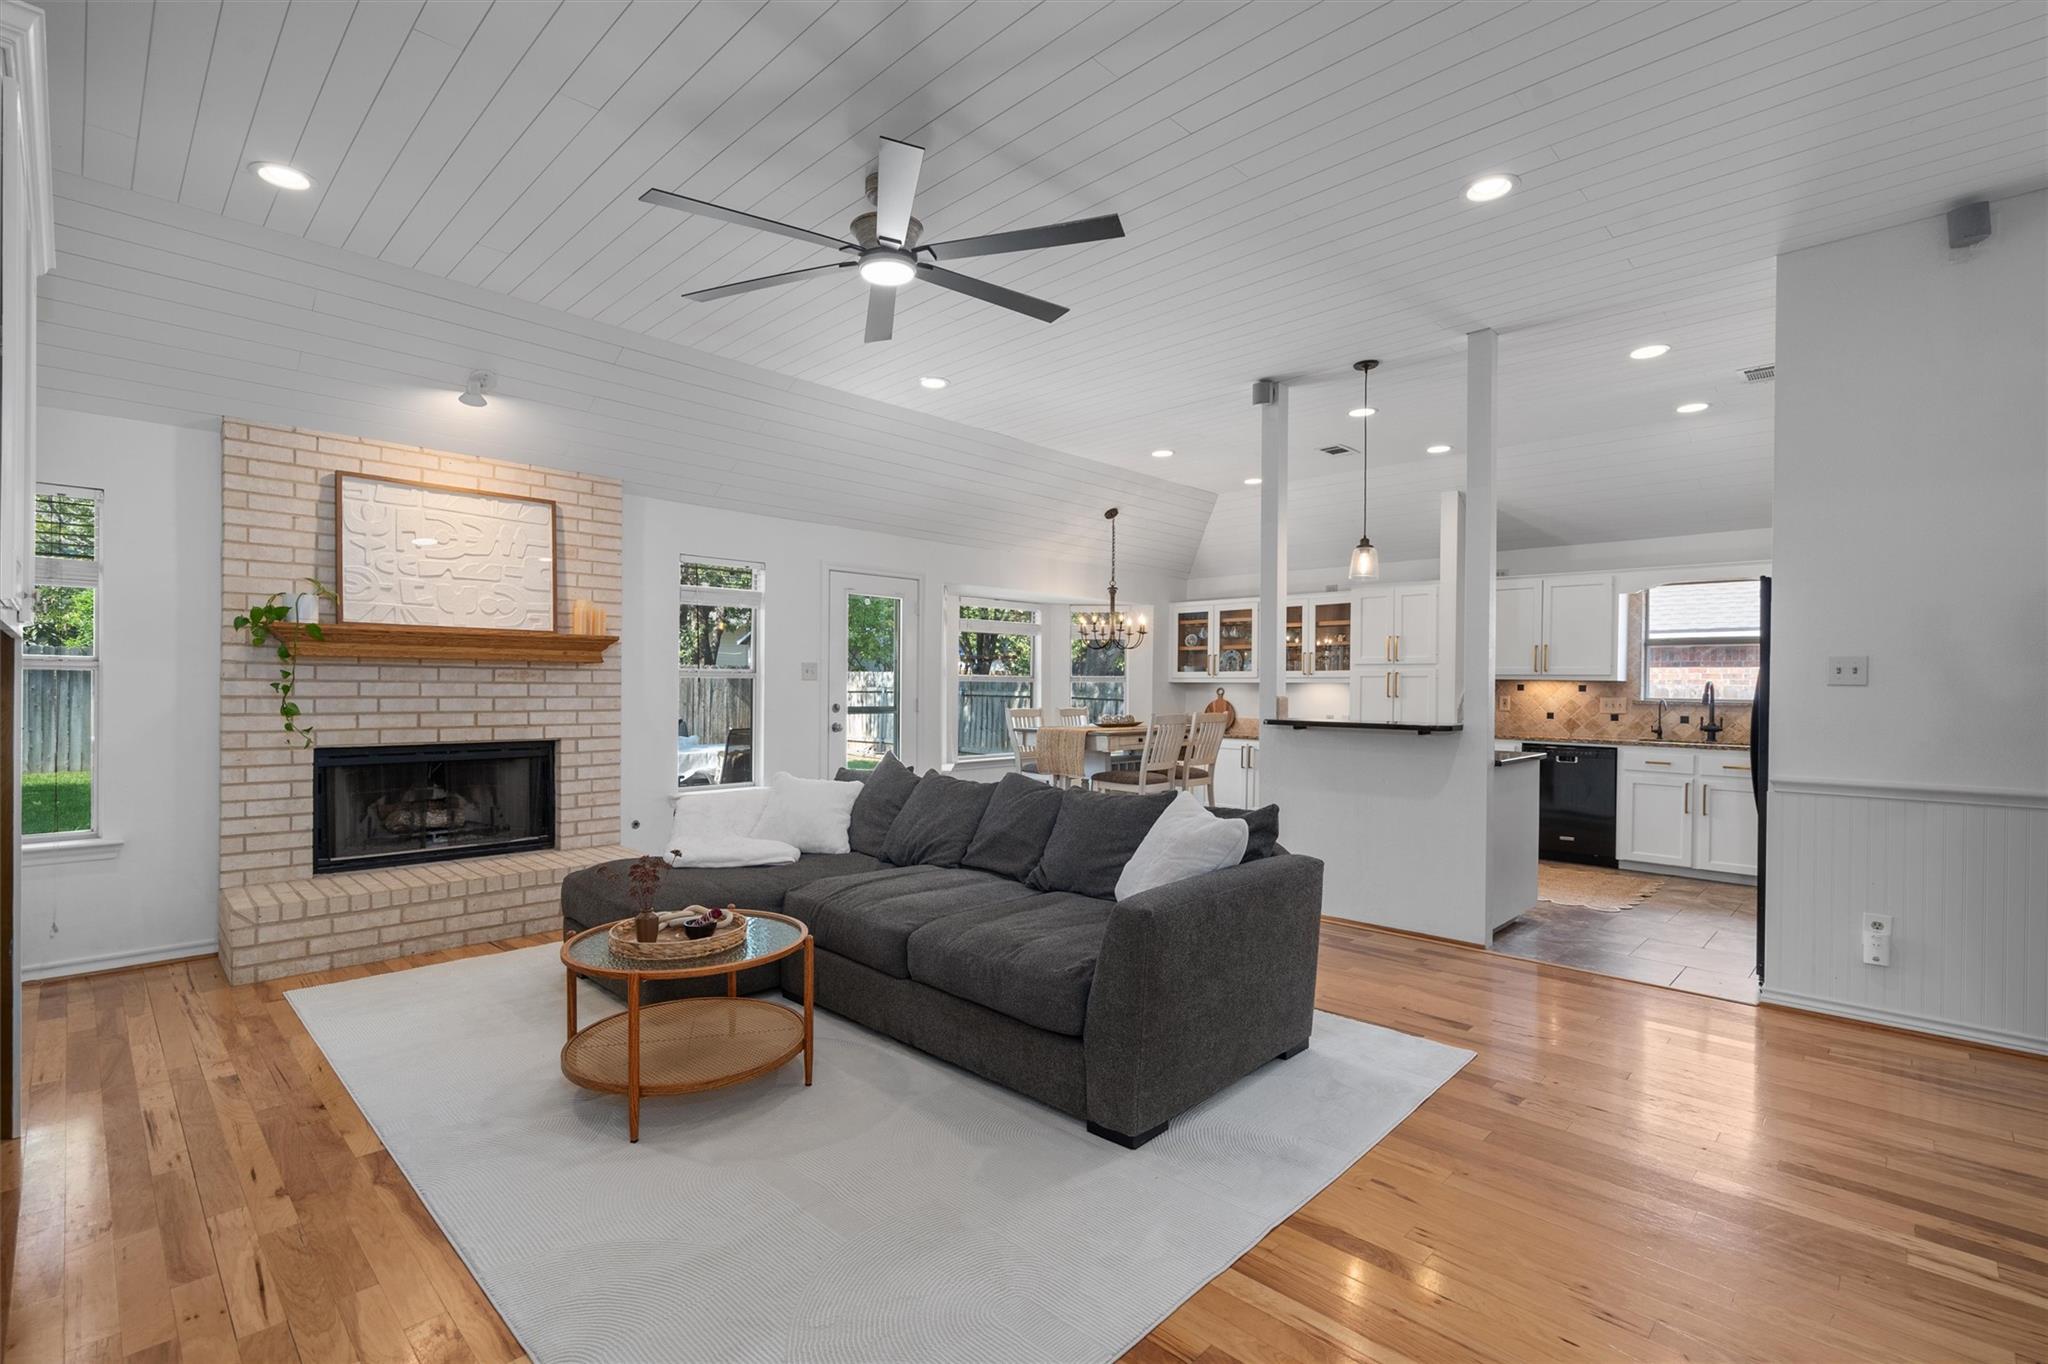
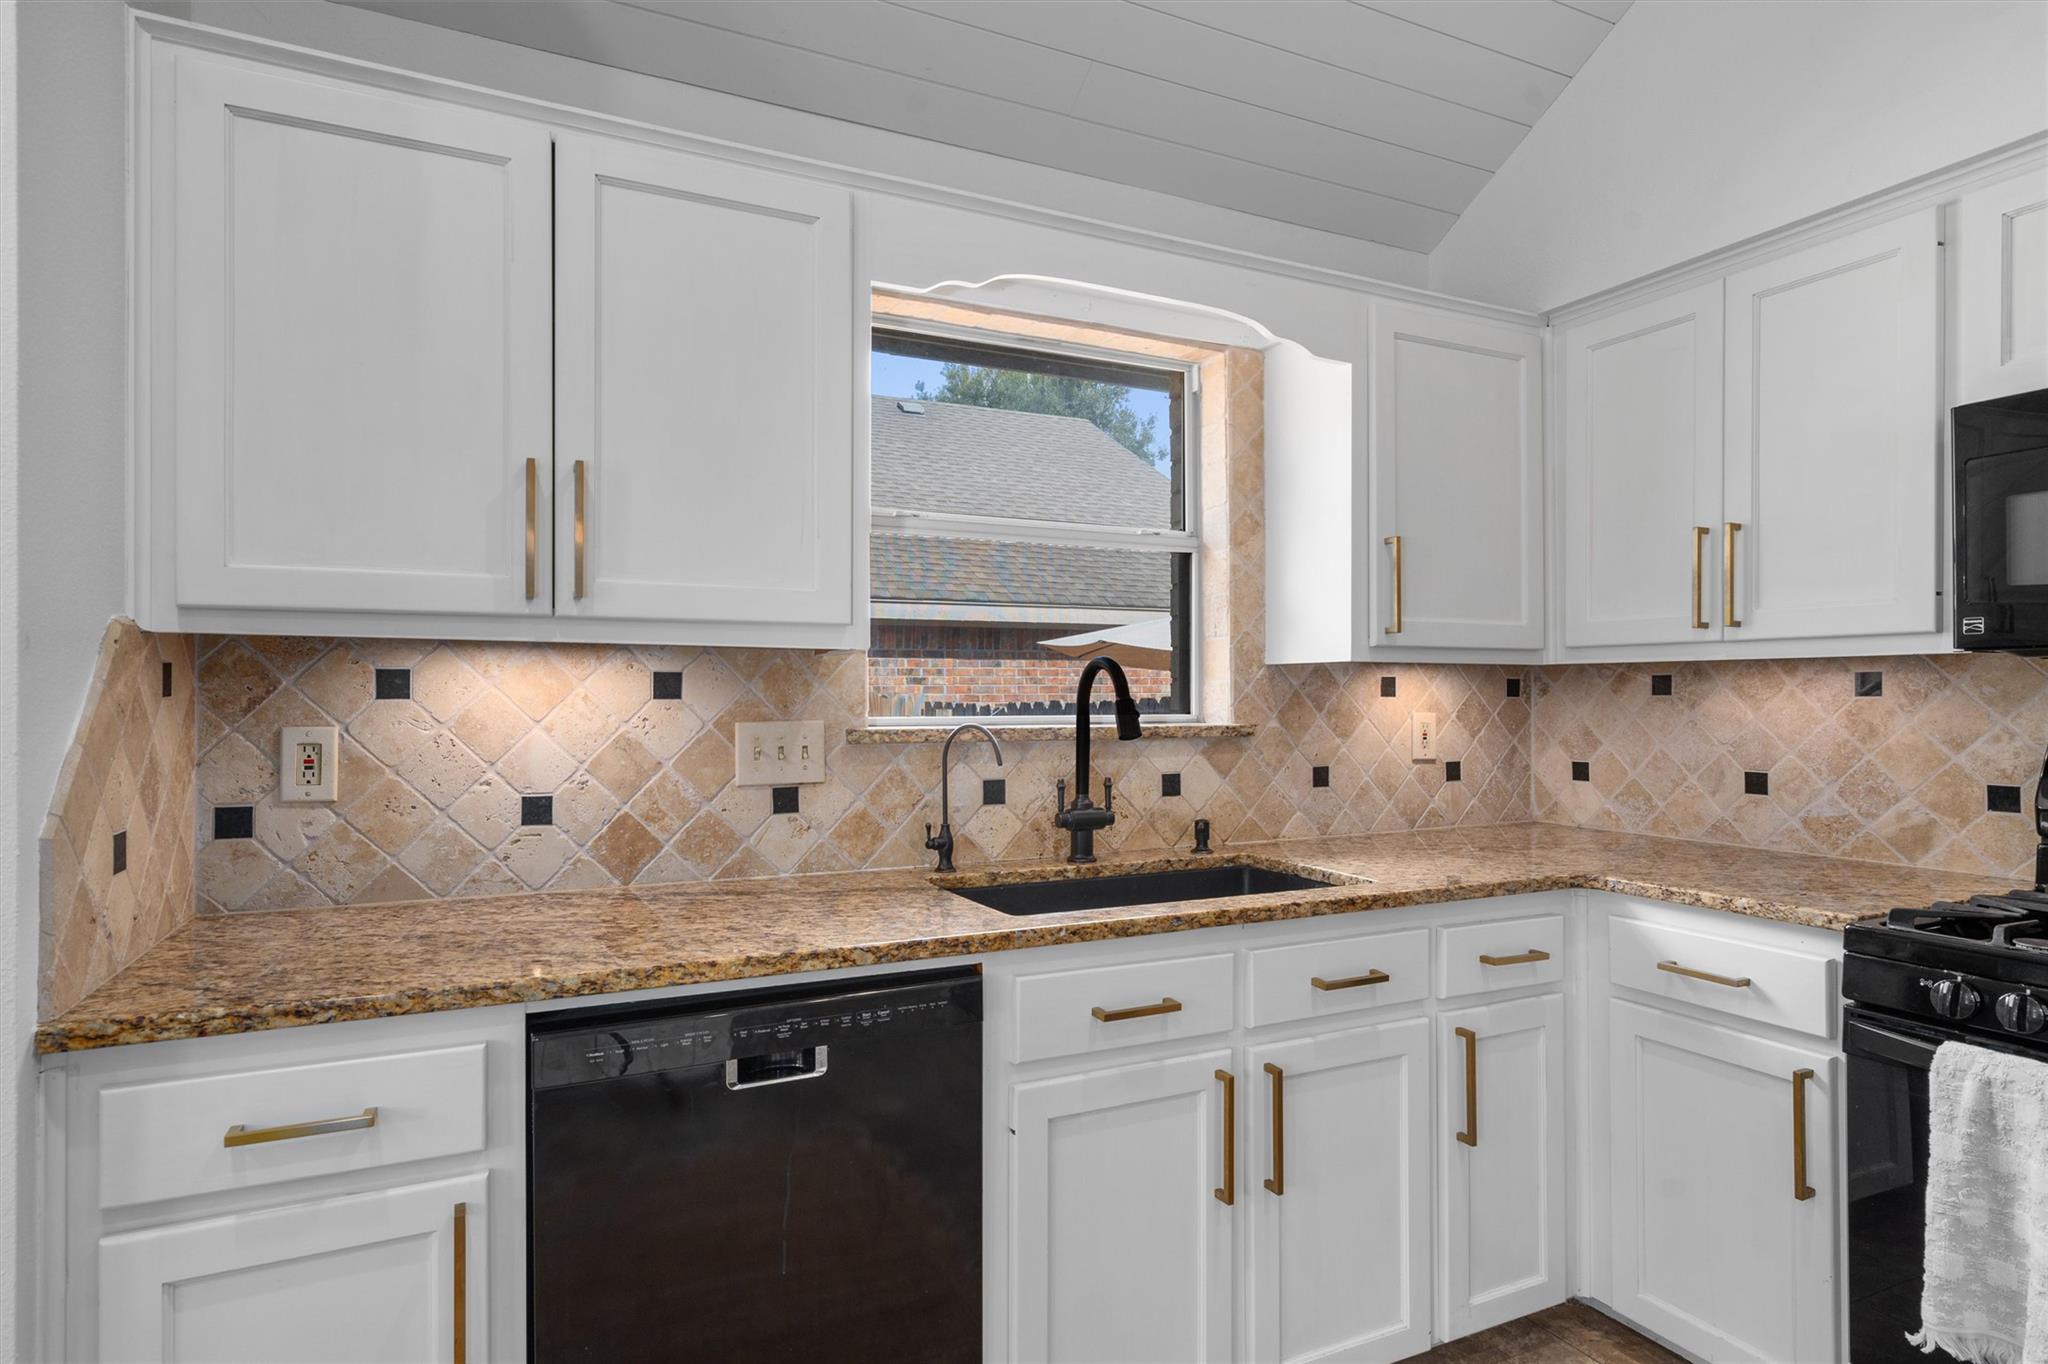
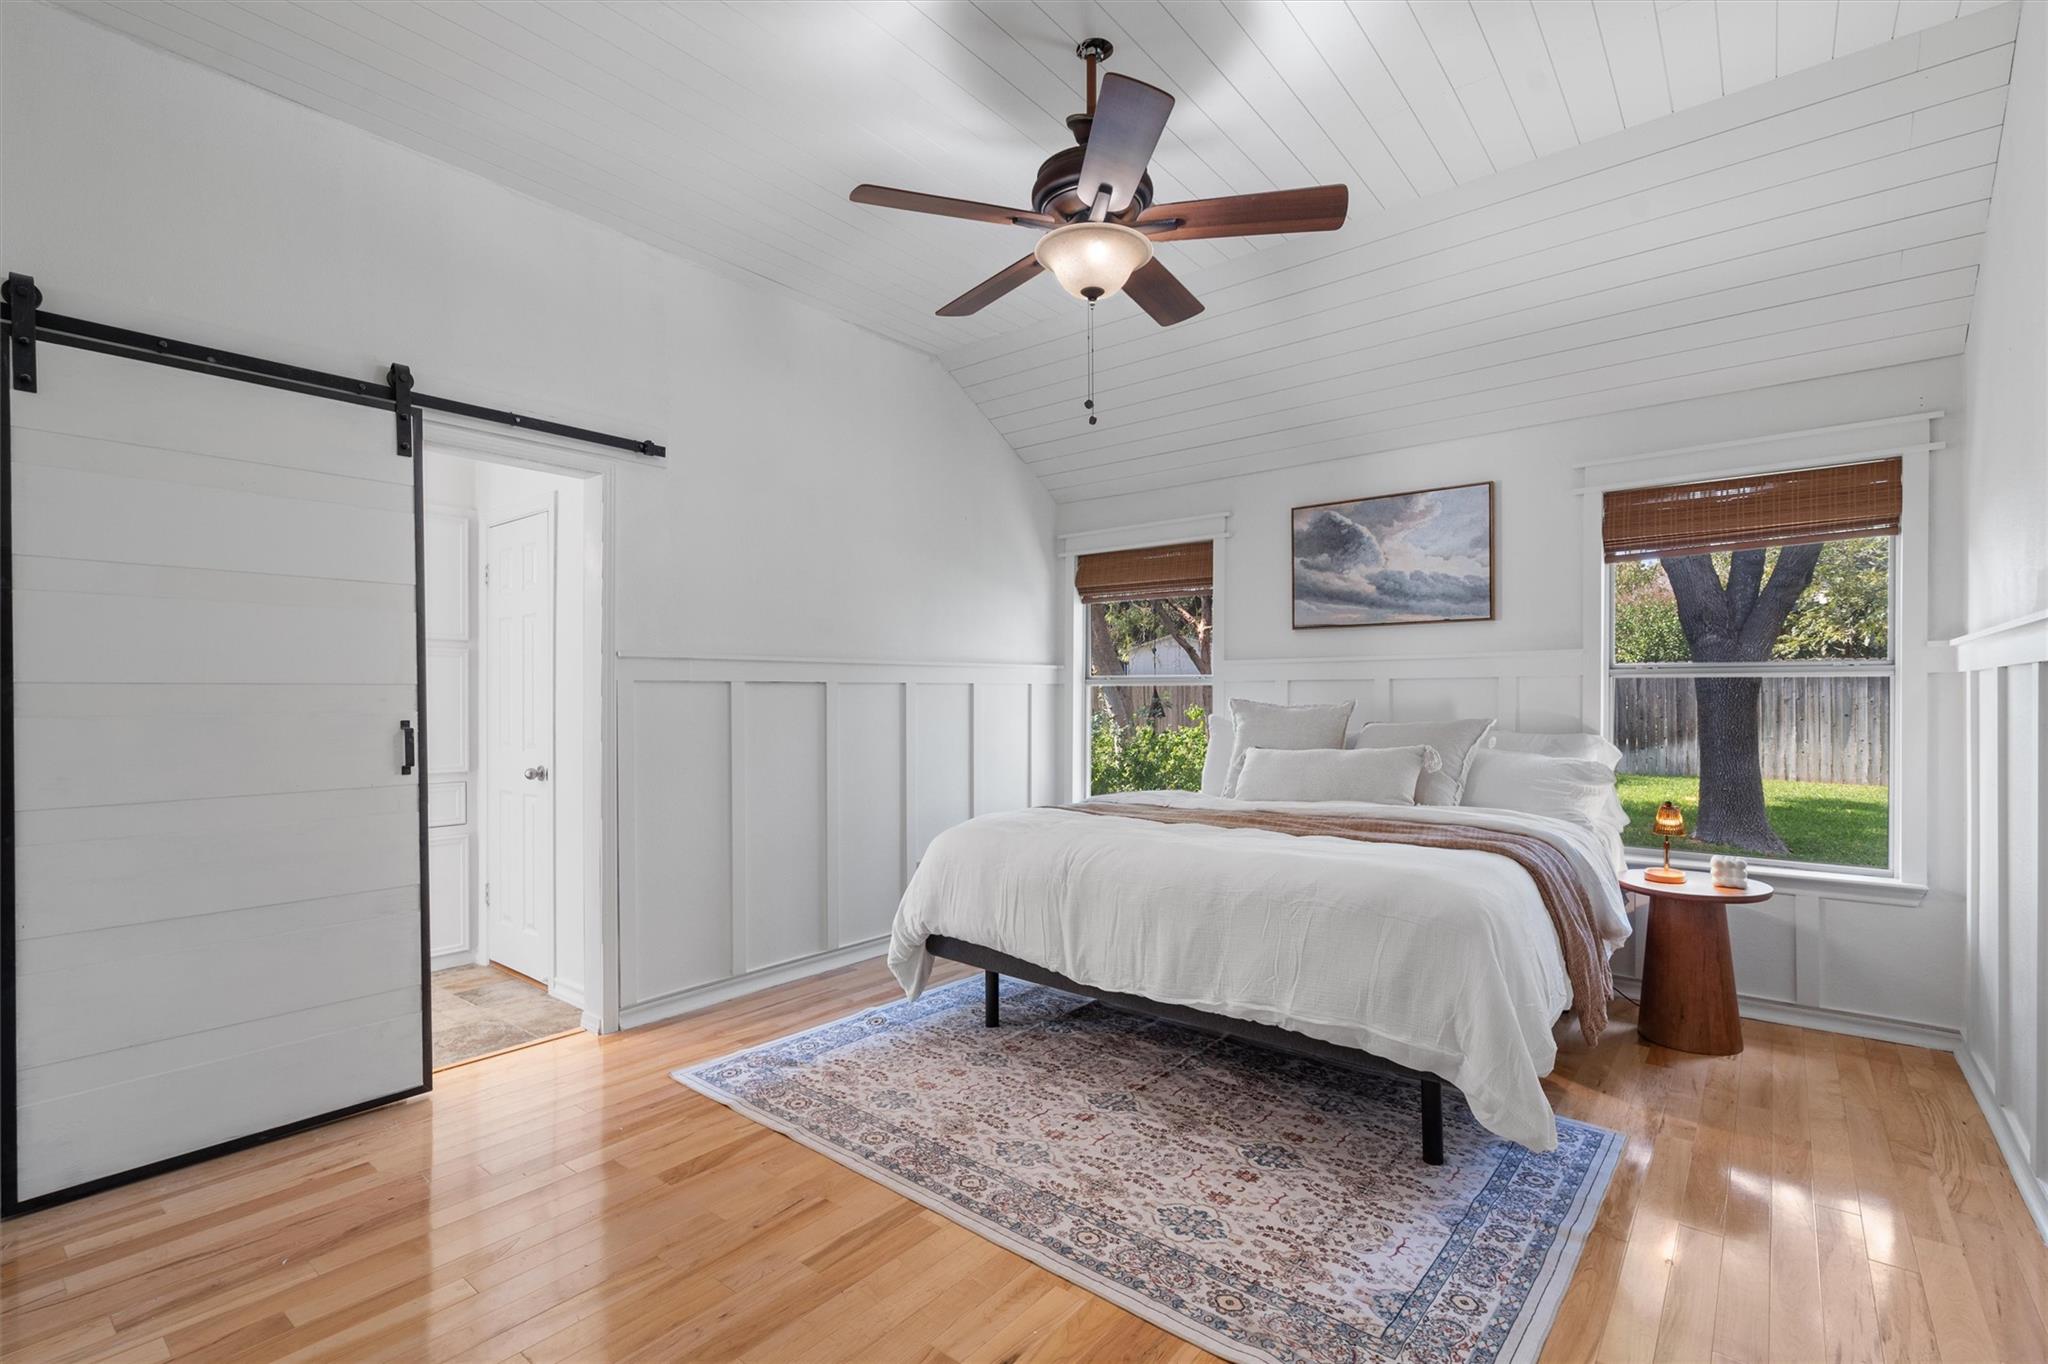
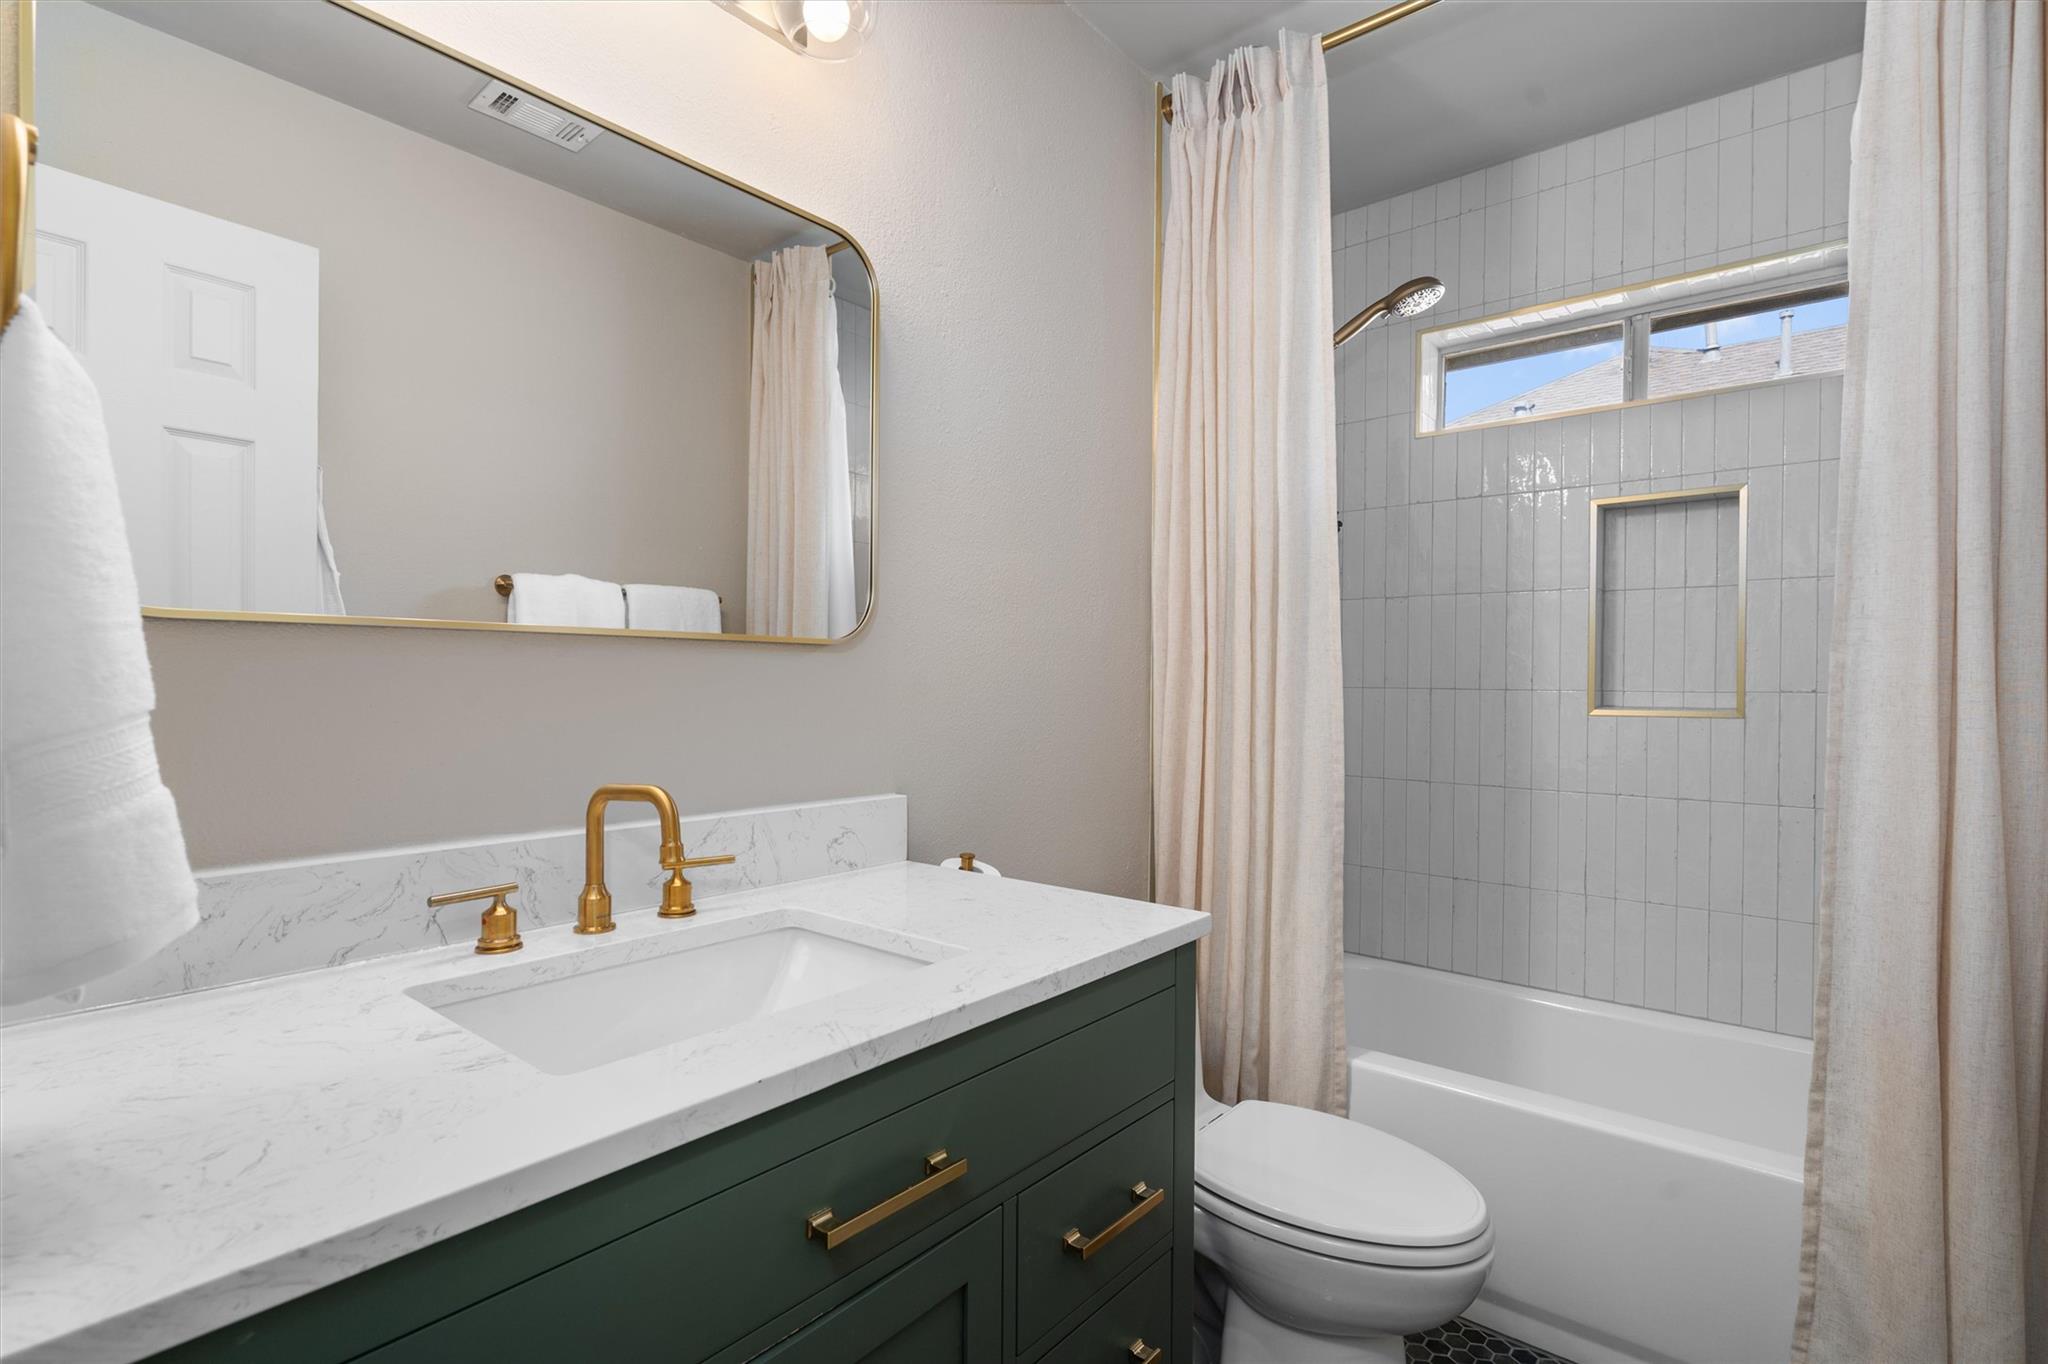
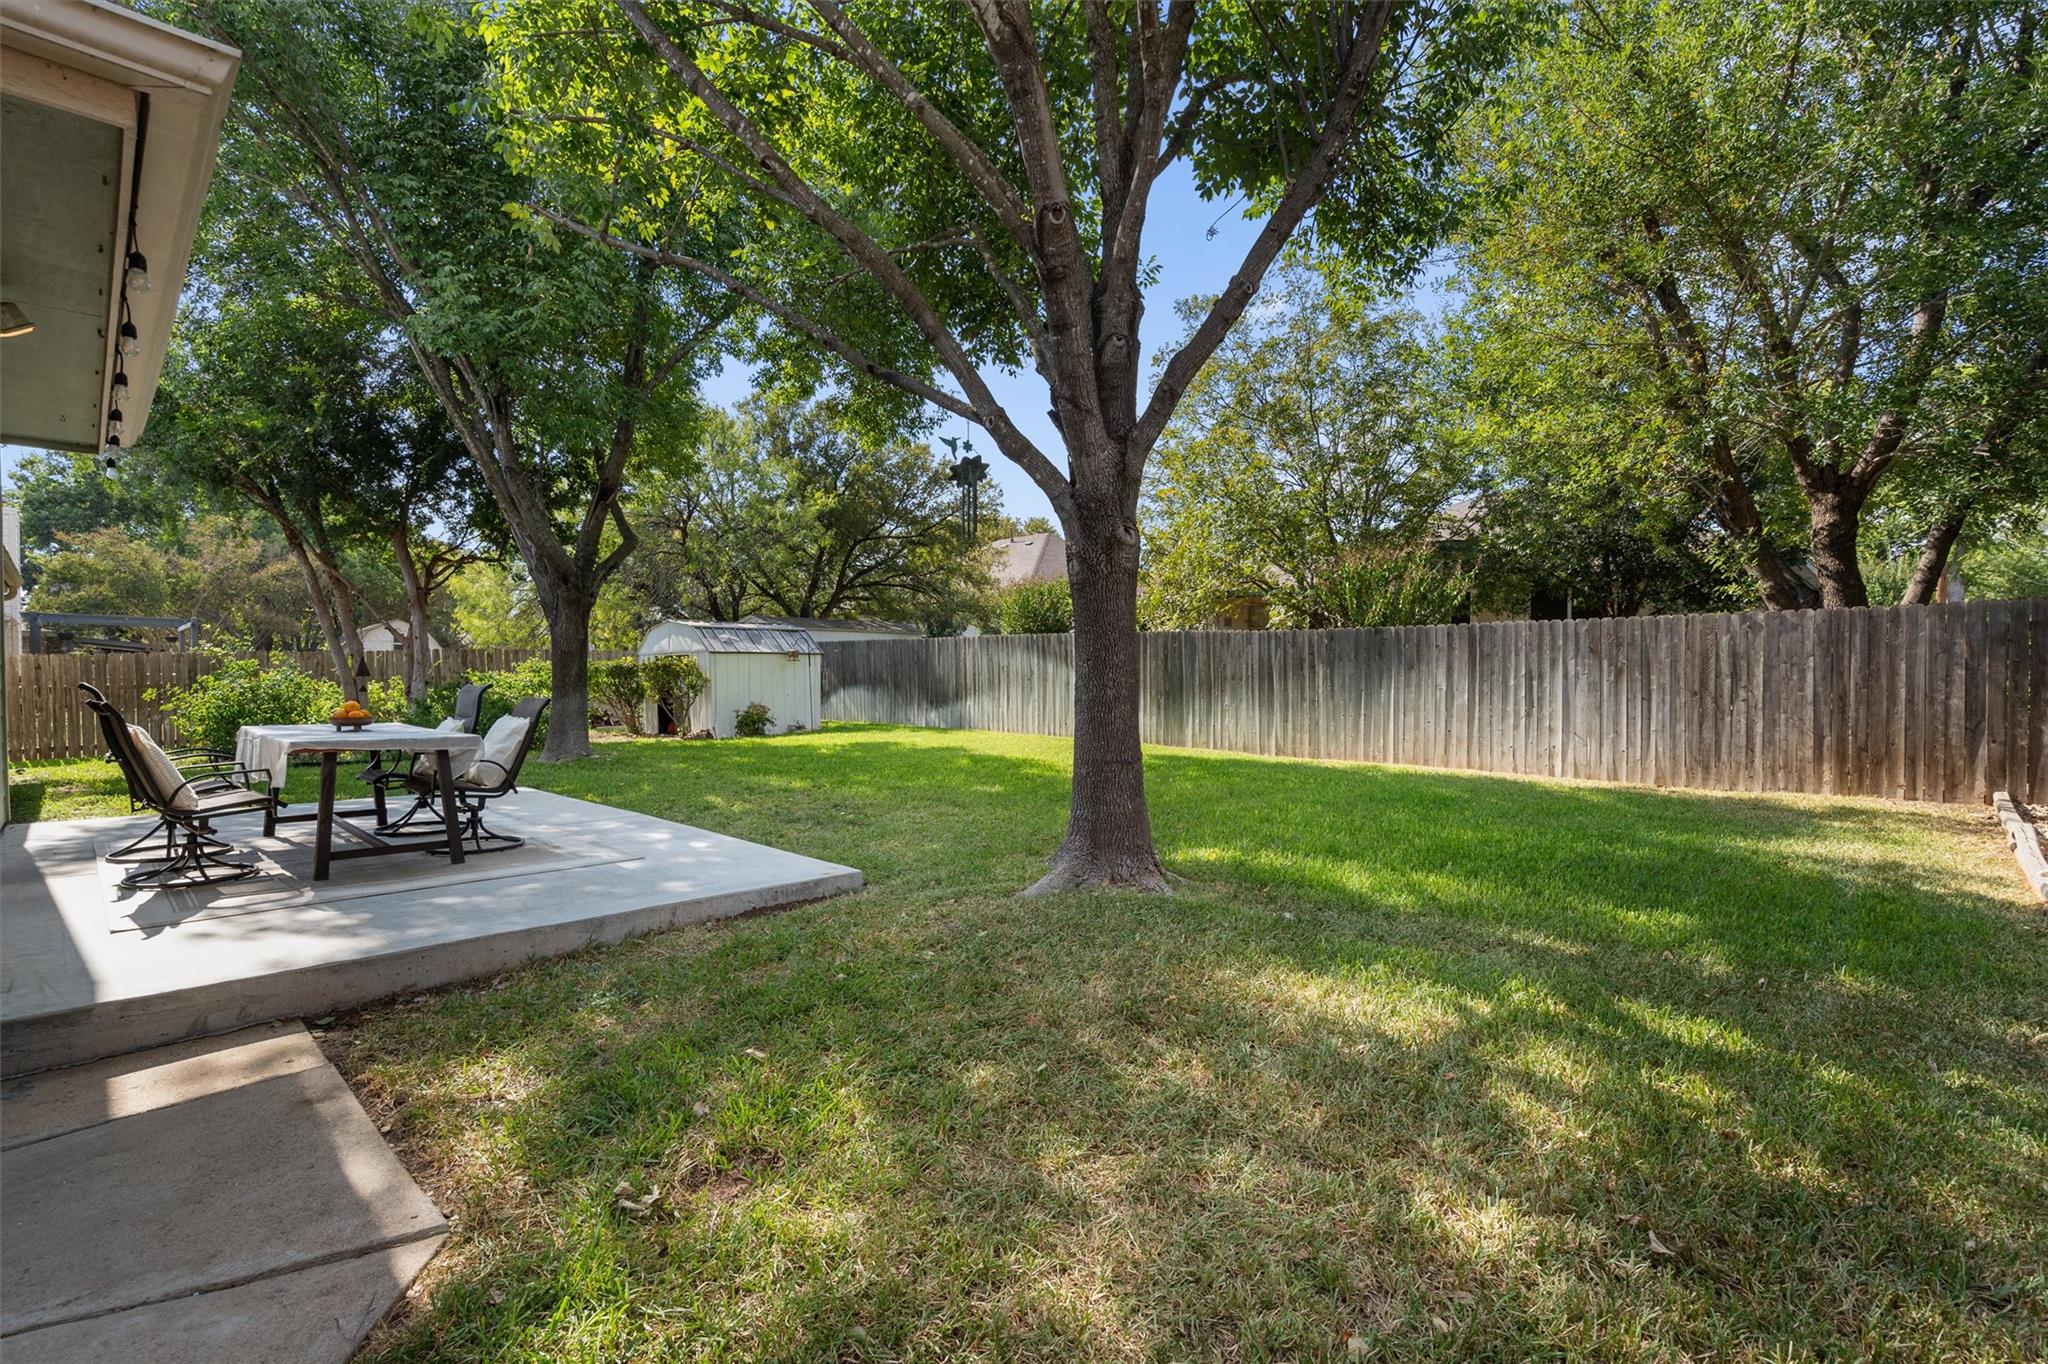
Living areaKitchenPrimary bedroomBathroomBack yardCovered patio
6 of the 24 photographs on this listing, chosen by ALEX Intelligence by ALEX's vision model -- not from the MLS's captions, which are generated. The 6 shown are the best examples of key property components that could be clearly identified.
Annual tax$7,037At 1.82% of the county market value.
Valuation
ALEX AI Statistical Model
Minimum$382,299
Average$413,161
Median$413,348
Maximum$440,793
ALEX’s statistical model uses five comparable sales. Each sale is
adjusted to this property’s 2,104 SF on the size relationship. Then each sale is
weighted by how closely it resembles this house in the matching metric.
Traditional Arithmetic Model
Minimum$399,704511 Debora Dr
Average$445,281
Median$455,778
Maximum$475,859104 Susana Dr
The same five sales counted equally, without adjusting them to this
house’s size. The two averages differ by
$32,120. Both are estimates of net sale
price, not recommendations: what to ask or offer is the agent’s, and is set out separately.
Why is this important? ALEX’s model is based on MIT
PhD-level statistics and NVIDIA models. It adjusts each sale for the size of the home and for when
the sale took place, adjusts for the differences between each sale and this house that the model
identifies, and includes the manual adjustments Diane
made after comparing each sold home with this property.
Click here for details
In plain terms
Sales that are more like
this property — closer in size, age, lot and distance, and more recent —
count for more, and the way price per SF changes with size is measured from
the sales themselves rather than assumed.
What the method is called
Comparables are chosen by Mahalanobis-metric nearest-neighbour matching with
calipers, and the valuation is a kernel-weighted local linear
regression — a local polynomial fit, the same family as LOESS —
evaluated at this property. Both are in services/comp_match.py.
Which sales are admitted, and the boundary that is not drawn
The pool starts from this property’s own subdivision family — every
spelling of it in the feed treated as one place — and widens outward only when
that is too thin to support a valuation. It is not capped at the
subdivision. A hard boundary sounds safer than it is: where a subdivision has produced
four sales in two years, confining the model to them buys a tidy boundary at the cost of
a valuation resting on four houses. Where the pool does widen, every rule that widened
it is printed in this report, with how many sales each step admitted or dropped.
How far apart two houses are
Similarity is not distance on a map. Each sale is described by six measurements:
living area in logs, year built, lot size in logs, distance from this property, months
since it closed, and bedrooms plus half the bathrooms. The Mahalanobis
distance combines all six into one number, scaled by how much each varies in this
market and corrected for the fact that they move together. Bigger houses tend to be
newer and to sit on different lots; a plain Euclidean distance would count that one
difference three times. Geography is one of the six, not the whole of it — a
near-identical house half a mile away is better evidence than a different house across
the street, and the metric says so.
The kernel, and why this one
Each admitted sale is weighted by an Epanechnikov kernel of its
distance: with u = d/h for bandwidth h,
the weight is 1 − u², reaching zero at the bandwidth
and staying there. It is the kernel that minimises asymptotic mean squared error
(Epanechnikov, 1969).
This is not the tricube kernel that LOESS uses by default, and not a
Gaussian one, and the difference is not cosmetic at these sample sizes. On six
comparables, tricube put 41% of the weight on one sale and 1.8% on another
— a six-comparable valuation actually resting on two. Epanechnikov falls away
gently enough that the set keeps contributing. The decay is quadratic and bounded, not
exponential: a sale past the bandwidth contributes nothing at all rather than a little,
which is what makes the admitted set an honest count.
The regression itself
With the weights fixed, the model runs a weighted least squares fit
of adjusted net price per SF on the logarithm of living area, and reads the
answer at this property’s size. Two things follow from that. The fit is
local: it is estimated for this property and discarded, and the next valuation
estimates its own. And the errors it minimises are weighted, so the line is pulled
toward the sales that resemble this house and is allowed to miss the ones that do
not.
Two diagnostics are reported with every valuation. The bandwidth
says how far the model had to reach. The effective sample size says how
many comparables the weighting really amounts to: nine sales weighted 12% each is nine
pieces of evidence, while nine weighted 80/20 is closer to two. Where the effective
sample size is too small, or there are too few comparables, the model refuses to fit a
slope at all and falls back to a kernel-weighted mean of price per SF — the
Nadaraya-Watson estimator — rather than fitting a line the data cannot carry.
The fitted size slope
Price per SF is not flat across sizes: a larger house of the same kind
usually fetches less per SF. Rather than assume a figure, the model fits a line
through the weighted comparables’ price per SF against the logarithm of their
living area and reads this property’s size off it. The slope is estimated on every
report, so a market where size barely matters and one where it matters a great deal are
each handled on their own terms. Where there are too few comparables, or their weights
are too concentrated for a slope to be estimated honestly, the fit falls back to a
weighted average of price per SF rather than fitting a line it cannot support.
Transparent, and statistically valid
Transparent because every step is written down in this report: which sales were
admitted, which were set aside and why, how each was weighted, and what was adjusted.
Statistically valid because it is an estimator with stated assumptions whose accuracy is
measured against sales it was never shown, and reported here whether or not that
flatters the figure. A number that can be checked is worth more than one that cannot.
Where the rest of it is
The full treatment — the exact kernel, the caliper widths, the effective sample
size, the bandwidth, the held-out test and the interval around the figure — is set
out in The statistics.
County Market Value$387,192WCAD 2026
Asking price$419,900at its original asking price
Valuation per SF$196The valuation across this property’s 2,104 SF.
The statistics
Overall Error Score (RMSLE)0.0803One score for all 5 test runs together, counted in proportions rather than dollars.
Forecast Standard Deviation9.0%How far a valuation like this one lands from the sale price, run after run.
Confidence Interval (68%)±7.6%Two of every three test runs came this close to the real sale price.
Median Error (MdAPE)3.4%The middle miss. Half the test runs were closer than this, half were further.
Within 10% (PPE10)80%How often a test run came within 10% of the real sale price.
Held-out Tests5Every figure on this row is measured on this many comparable sales.
Click here for details
Forecast standard deviation (FSD) — defined
In plain terms
Range of potential values.
Lower % is better. At 9.0%, about two in three valuations like this one
land within 9.0% of the price the house eventually sells for, and one in
three land further out. It is measured on this property’s own comparables, so it
describes the spread of the evidence here — not a promise about this house.
Formula. Each comparable in turn is hidden and its net sale price
Pᵢ is predicted from the others as P̂ᵢ.
FSD is the sample standard deviation of the log ratios:
FSD = √( Σ (dᵢ − d̄)² / (n − 1) ), with
dᵢ = ln(P̂ᵢ / Pᵢ). Here
n = 5 and FSD = 0.0895.
How to read it. Lower is better. It is the same measure automated valuation vendors
(Zillow, HouseCanary, Cotality) publish for their own estimates, so it can be compared with theirs — with
the caution that theirs is measured on thousands of sales and this one on 5.
Overall error score (RMSLE) — defined
In plain terms. One number that sums up how wrong the predictions were across all the
hidden comparables, counting a 10% miss high and a 10% miss low as equally bad. Lower is better; 0 would be
perfect. This property scores 0.0803.
Formula. Root mean squared logarithmic error,
RMSLE = √( (1/n) Σ (ln(1 + P̂ᵢ) − ln(1 + Pᵢ))² ),
over the same 5 held-out predictions. Because it works on logarithms, it
measures proportional error, and because it squares each miss, one large miss raises it more than several
small ones.
How to read it. RMSLE has no upper bound and no threshold: it starts at 0, which
would be perfect prediction, and rises without limit, so lower is always better. Because it is measured in
logarithms, its value reads roughly as a proportion — 0.10 corresponds to predictions typically about
10% off, and 1.0 would mean being wrong by a factor of about 2.7. House-price models in practice fall
between about 0.05 and 0.25; this property scores 0.0803. It is most useful for comparing one method against another on the same sales, rather than
read on its own.
Median error (MdAPE) — defined
In plain terms
Line the held-out misses up
smallest to largest and take the middle one. Half were closer than this, half further. It is
the typical miss, and unlike an average it does not move when one comparable is badly
wrong.
Formula.MdAPE = medianᵢ |P̂ᵢ − Pᵢ| / Pᵢ,
over the same n = 5 held-out predictions, expressed as a percentage:
3.44%. The mean of the same errors (MAPE) is
6.59% and the largest single one is
15.35%.
Why it is here, beside RMSLE. The two answer different questions and are
reported together deliberately. RMSLE squares each miss, so it is carried by the worst
comparable; MdAPE is a median, so it is carried by none of them. A set with four close
comparables and one poor one shows a low MdAPE and a raised RMSLE, and that gap is itself the
finding — it says the method works on this property except on one sale, which is worth
knowing before the gap is averaged away. Where the two agree, the error is spread evenly
through the set.
What it does not say. With n = 5, the median is
one of 5 numbers, not an estimate of a population median: change one comparable and it can
move to the next order statistic. It is the typical miss on this set, not the typical
miss of the method.
Within 5% and within 10% (PPE5, PPE10) — defined
In plain terms
How often the method landed
close. Of the 5 hidden sales, 3 came within 5% of what the house actually
sold for and 4 came within 10%. The range after each one says how far those
shares could reasonably be off, given how few sales they are measured on.
Formula.PPEᵙ = (1/n) Σᵢ 1[ |P̂ᵢ − Pᵢ| / Pᵢ ≤ k ]
— the share of held-out predictions inside a tolerance of k. Here
PPE5 = 3/5 = 60% and
PPE10 = 4/5 = 80%. These are the
industry’s own yardstick: PPE10 is what vendors quote as “within 10%”.
The interval, and why it is not optional. A share measured on 5 trials can
only take the values 0%, 20%, 40%, 60%, 80%, 100% —
it moves in steps of 20 points, so the figure alone would claim a precision the
sample cannot carry. Each is therefore reported with a Wilson score interval at 95%:
( p̂ + z²/2n ± z√( p̂(1−p̂)/n + z²/4n² ) ) / (1 + z²/n)
with z = 1.96. Wilson rather than the textbook
p̂ ± z√(p̂(1−p̂)/n) because that interval
collapses to zero width at p̂ = 0 or 1 —
a run of 5 hits would report certainty — and its coverage is poor at small
n (Brown, Cai & DasGupta, 2001). Wilson stays inside
[0, 1] and keeps its nominal coverage here.
PPE5 is 23% to 88%,
PPE10 38% to 96%.
The width of those ranges, not the shares inside them, is the honest summary of what
5 held-out sales can establish.
What is not claimed. The tolerances are fixed at 5% and 10% before the errors are
seen, never chosen to flatter the result. And a share is a blunt instrument by construction: a miss of
5.1% and a miss of 50% both count as outside, which is why MdAPE and the error band are reported beside
these and not instead of them.
Cross validation — the error measured on this property
Which figure these
measures belong to. Every error, band and interval here is computed on
ALEX’s valuation of $413,161 —
the same net sale price shown at the head of the report, on the same basis: what the seller
keeps after paying the buyer’s closing costs and any repair credit. It is not the
grossed-up contract price quoted against the outside estimates in Benchmarks. If an agent has
changed an adjustment, the figure at the head of the report moves; these measures do not move
with it, because they measure how ALEX’s method performed on this property, not how a
revised figure would perform. A changed valuation carries no measured band until the change is
tested the same way.
How this was tested, in one sentence: we covered up
one of the five sales, worked out what this method would have said that house was worth using
only the other four, then uncovered it and measured how close we got — and did that five
times, once for each sale.
Five tests is a small number from which a spread can be quoted.
These figures are real and specific to this house, but thin: one unusual comparable moves them
materially. Treat them as the shape of the uncertainty, not a precise measurement of it.
Confidence interval0.0763the 68% bandTwo times in three, the true figure should land within
±7.63% — that is ±$31,534, or
$381,627 to $444,695. The wider 95% band is 0.1414:
±$58,405, or $354,756 to $471,566.
Typical spread — FSD8.95%±$36,988 on this valueHow much estimates like this one scatter around the truth.
RMSLE0.0803lower is betterA single overall error score that treats being 10% too high and 10% too low
as equally wrong, and stops one big miss dominating. It has no meaning on its own — it
is for comparing one method against another.
Median error3.44%mean 6.59%, worst 15.35%The middle of the misses — the straightest answer to
“how far off is this likely to be”.
What happened when each sale was hidden and predicted from the others: how far off that prediction was, as a share of what the sale actually netted. Past 10% is red.
Held out
Actual net
Predicted from the others
Error
312 Susana Dr
$368,375
$381,030
+3.44%
100 Susana Dr
$362,771
$354,403
−2.31%
108 Susana Dr
$352,500
$343,323
−2.60%
511 Debora Dr
$362,000
$417,581
+15.35%
104 Susana Dr
$380,000
$344,794
−9.26%
Converting a net price to a contract price
In plain terms
The valuation is a net figure: what a seller keeps after the credits a buyer customarily asks for. A contract is written at a higher number that nets down to it. This explains the conversion between the two, so neither is mistaken for the other.
Why there are two, and where each is used. This valuation is a net sale
price. Two places in the report need a contract price instead, and they do not use the same
conversion, so both are stated here rather than left to be discovered.
One: the neighbourhood ratio, used for comparison.ρ̂ = median(net / close) over closed sales in
Sierra Vista (the subject's subdivision)
in the last 24 months, n = 34, with a minimum of 15 sales before the level is used at
all. Here ρ̂ = 0.9979, an implied
seller contribution of 0.21% of the contract price. It
grosses our net figure up for the Benchmarks comparison and sets the “how far above the
evidence the asking price sits” percentage. It is a median of ratios, unweighted, with
no interval reported: at n = 34 a median carries real sampling error, and none is
claimed for it.
Two: the pool share, used for the offer ladder.ŝ = Σwᵢ(Cᵢ+Rᵢ)/Pᵢ ÷ Σwᵢ,
a recency-weighted MEAN of the actual contribution share over the negotiation pool, with its
own drawer in the recommendation section. The two differ in estimator (median of a ratio
against a weighted mean of a share), in pool (a subdivision over 24 months against an MLS-area
price band over 36), and in what they measure (net divided by close, which includes anything
that separated the two, against closing costs and repairs specifically).
What that means for a reader. The two conversions do not have to agree,
and on this property they do not: they differ by
-1.16
percentage points of the contract price (0.21% against
1.37%). Neither is used to alter the valuation itself, which
is and remains a net sale price. Where a contract price appears, the conversion behind it is
named in that section.
The headline figure uses a third. The contract price at the head of the report is
C = (V̂ + R)/(1 − c), rounded to $500, with c the
closing-cost share and R the repair credit set in the page’s closing-cost control,
which starts from the negotiation pool and which the agent can change. It is not
ρ̂. Grossing by
ρ̂ for the Benchmarks comparison gives
G = V̂/ρ̂ = $413,161 ÷ 0.9979 = $414,051.
Assumptions and limits of ρ̂. The sample is every closed
sale with a positive close and net price whose subdivision name begins with
Sierra Vista, with no filter on property
type, condition, price band or arm’s-length status beyond what the warehouse table already applies; a
neighbouring subdivision whose name shares the prefix is included. A median of ratios is not the ratio of
medians and ignores how large the contributions were: where most sales carry none,
ρ̂ can be exactly 1 while a minority carried large ones. A sale whose concession
was never recorded in the MLS fields enters at a ratio of 1.
How the comparables were chosen
Why this matters for everything above. The held-out error, the bands and
the confidence score all rest on the comparables actually chosen. If the selection rule were
unstated, a reader could not judge whether the held-out comparables and the subject are alike
enough for the error measured on them to say anything about the subject. The rule is
therefore stated in full, in the order it runs.
The method, named. Selection is Mahalanobis-metric nearest-neighbour
matching with calipers (Rubin 1980, Biometrics 36:293; Rosenbaum & Rubin 1985,
The American Statistician 39:33; Abadie & Imbens 2006, Econometrica
74:235), run inside an ordered set of geographic strata. The strata decide where
this market is; the metric decides which sales inside it are comparable. This
replaced a cascade of several hundred criteria sets that stopped at the first rung holding
six candidates and then ranked them on a weighted score of stated conventions. Two
differences matter: the cascade treated any two sales clearing the same rung as equally
comparable, and when a rung ran short it widened the living-area band to as much as
±45% — producing candidates this valuation’s own ±25% standard then
discarded. Selection now cannot hand the estimator a sale the estimator must refuse.
Step 1 — what is removed before anything else. Sales that are not
arm’s length (REO, short sale, auction, HUD, corporate-owned, probate, and overbid sales
whose remarks name any of those), sales in fair or poor condition, sales in a FEMA flood zone,
sales more than ±20% from this property’s asking price, and the subject’s
own earlier sale — that last only when at least three other comparables remain, since
below that the set is too thin to refuse the help.
Step 2 — admissibility. These are the differences a distance must
never be allowed to trade away. Each is categorical: a two-storey house is not a one-storey
house that happens to be far away, and no dollar adjustment converts one into the other. Each
rule below is applied in order, to what the rule above it left.
The first two are hard: they are
never relaxed, even when relaxing them is the only way to field a comparable, because a
valuation with no comparable is a problem an agent can see and a valuation built on the wrong
product is one nobody sees.
The rest are relaxed only if applying them would leave nothing at all, and any such relaxation
is named in the table.
Rule
What it requires
Why it is a rule and not an adjustment
Sales in
Excluded
Left
Age-restricted community hard
A sale in an age-restricted (55+) community may be compared only with another such sale, and never with one outside it. Read from ACTRIS_Restrictions where the feed supplies it, and from a curated list of named communities where it does not.
A 55+ community is a different product with a different buyer pool, and no dollar adjustment can undo it. This property is the reason the rule exists: an earlier cascade reached five miles, took five Sun City comparables carrying a $1,960 annual HOA it does not have, and came back $42,000 low. SeniorCommunityYN is populated on zero of 535,397 listings, so the feed alone cannot catch this.
226
−3
223
Association fee hard
Annual association dues must be within the stated gap of this property's.
Dues are a recurring cost capitalised into price. The gap also catches amenity-heavy communities the age rule has not named.
223
−58
165
View
Same view category as this property.
A greenbelt view and a lake view are separate markets, not a difference in degree.
165
−6
159
Attached or detached
Attached homes compare only with attached, detached only with detached.
Shared walls change the buyer pool, the insurance and the land interest. It is a different product, not a nearby one.
159
—
159
Storeys
Single-storey compares with single-storey, multi-storey with multi-storey.
Single-level living commands its own premium in this market and is the first filter many buyers apply. The engine adjusts for story TYPE within a match; it cannot convert one into the other.
159
−59
100
Waterfront
Waterfront compares only with waterfront.
Water frontage is a land interest, not a feature, and its premium varies by body of water rather than by a rate that could be applied.
100
—
100
New construction
New construction compares only with new construction.
A builder's first sale carries incentives, warranty and finish that a resale does not, and it is priced off a price sheet rather than off the market.
100
−16
84
Pool
If this property has no pool, comparables with a pool are excluded. If it has one, both are admitted and the difference is adjusted.
The rule is deliberately one-sided. The engine does adjust for a pool, but when the subject has none, every indication would then rest on that one adjustment.
84
−2
82
Builder
For a new-construction subject with a named builder, comparables naming a different builder are excluded. A comparable with no builder recorded is admitted.
Builder premium runs 8-12% within one subdivision. Missing data is treated as admissible rather than disqualifying, because ACTRIS fills this field sparsely.
82
—
82
School district
Same school district. A comparable with no district recorded is admitted.
District boundaries are a documented price discontinuity and they do not follow distance: two houses a street apart can sit in different districts.
82
—
82
Sale-to-list
Net sale price between 0.93 and 1.03 of the comparable's own list price.
A sale far off its own asking price is usually a data error, a related-party transfer or a term the concession fields do not record. Note this tests the sale against ITS OWN list price, never against this property's price.
82
−7
75
Lot density
Living area per acre within a factor of 3.0 of this property's.
It separates product types that size and lot size do not: a 2,000 SF house on a quarter acre and the same house on five acres are different markets.
75
−3
72
Step 3 — the market area, tightest first. The remaining sales are
placed in nested strata: the same street in this subdivision, then the same phase or section,
then the subdivision — taken as every subdivision sharing its name in this city, so a
“Serenada West” sits with “Serenada” and “Serenada
Estates”, because the distinction between them is a platting artefact and not a
market boundary — then half a mile, one, two, three and five miles, then the postal code. The shared name
must be distinctive on its own: a first word under five letters keeps its second, so
“Sun City” never collapses to “Sun” and sweep in Sunrise.
The search stops at the tightest stratum holding at least five eligible sales
— eligible, not merely present, and five because that is the number the estimator
is built on. A subdivision holding five admissible sales is not abandoned for a
one-mile ring holding six: that trades the definition of the market for one more
observation, which is the wrong trade. That distinction is the second fix: the old rule stopped at the
first rung holding six candidates, and the valuation then discarded those outside its size
standard and finished on three. The rung looked full and the report was thin.
Step 4 — the hard calipers. A sale is eligible only if its living
area is within ±25% of this
property’s — the same appraisal size standard the valuation itself applies, so the
two can never disagree — and only if it closed within the time window. The window opens
at 13 months, which guarantees a full seasonal cycle, and widens to 24 only when 13 cannot
fill the stratum. Time widens before geography: a sale two streets away eighteen
months ago is better evidence than a sale two miles away last month, because the repeat-sales
index can carry a date and nothing can carry a different market.
This report used a 13-month window.
Step 5 — the distance itself. Each eligible sale is placed in a
6-dimensional space
— living area (logarithm), year built, lot size (logarithm), distance from this property, in miles, months between the sale and today, and bedrooms plus half the bathrooms —
and its distance from this property is measured as
d² = (xᵢ − x₀)′ Σ⁻¹ (xᵢ − x₀),
where Σ is the covariance of those covariates across every
admissible sale in the market area. Estimating Σ on the market
rather than on the handful of sales in hand is what makes the distance mean something: two
hundred SF is a large difference in a tract of identical houses and nothing in a
custom one. Each variance is ridged before inversion (Ledoit & Wolf 2004, in its simplest
diagonal form); where the market area holds fewer than five sales per covariate the
off-diagonal terms are dropped and the measure becomes standardised Euclidean distance, which
is the same statistic under independence. The basis line records which was used.
Mahalanobis distance on 6 covariates (metric from 226 sales in the market area), within Sierra Vista; 5 of the 8 sales there clear the size and time standards, 5 of those are inside the distance caliper, 13 months of sales considered
The caliper, and the factor of two in it. A sale is admitted when
d² ≤ 2χ²p,0.5, the median contour of the
reference distribution. The factor of two is not a tuning choice: the subject is one draw and
the comparable another, so their difference has covariance
2Σ and d² is distributed as
2χ²p, not χ²p.
Calipering at the plain χ² median — the error this
model carried until it was measured — admits only the nearest sixth of an honest pool.
For this report the caliper is
d² ≤ 10.70.
The caliper excludes only while exclusion still leaves five comparables. Below that the
nearest sales fill the set and each one past the caliper is named, because a sixth constraint
that silently cuts a valuation to three is not a better valuation.
2 of these comparables lie past the usual distance for a match; this market area holds nothing closer
This property, in numbers. 226 closed sales survived
step 1, 72 of them admissible under step
2, 5 eligible inside the chosen
stratum after the size and time calipers,
5 inside the distance caliper, and
n = 5 used.
What is deliberately NOT a selection rule. The old cascade filtered on
price per SF — within 15% at its tightest rung, and 0.125 of its ranking score.
That is the very quantity the valuation goes on to average, so choosing comparables for
already agreeing on it narrows the measured dispersion by assuming the answer. It has been
removed. Nothing in selection now looks at the comparable’s price except the
±20% asking-price screen in step 1 and the sale-to-list test in step 2, and that test
compares each sale with its own list price, never with this property’s.
Outliers are handled after adjustment, where they can be seen and named.
After selection, two further rules. (1) Same neighbourhood.
When at least three of the selected comparables share this property’s subdivision
family, only those are kept.
Family, not the recorded plat name: matching on the exact name made this rule fight the
selection ladder above it, throwing out the sibling sections that ladder had just brought
in. (2) Size. The set used is
K = {i : |sᵢ/S − 1| ≤ 0.25} if |K| ≥ 3, and
otherwise every comparable with a known living area and net price; here none was set aside.
The final set is n = 5.
Where the agent stands in this.
The comparables on this
page are the model’s own. An agent may replace or remove any of them, and the report
then records that it was an agent’s set. A comparable an agent adds by hand carries no
computed distance and is given full weight in the estimator, deliberately: the agent has
asserted it is comparable, and that assertion is the best evidence available about it.
The limit this creates, stated plainly. Selection is not random. The five
sales are the closest matches the rule could find, which is what makes them useful evidence
and also what makes the leave-one-out error an optimistic estimate of the error on an
arbitrary house: a held-out comparable is being predicted by four sales chosen to be like it.
Removing the price-per-SF filter narrows this bias but does not end it: sales alike in size,
age, lot and location are alike in price, so selection still favours agreement.
The population figures in this section, measured on a blind holdout of sales the model never
saw, are the pessimistic bound on the same question. Both are printed for that reason.
The evidence-quality score
In plain terms
A score out of 100 for how good the evidence behind the valuation is: how many comparable sales there were, how similar, how recent, and how much they had to be adjusted. It rates the evidence, not the house.
What it scores. 71 of 100 scores the EVIDENCE behind
this valuation, not the property and not the probability that the figure is right. It is an
index built from four factors, each worth up to 25 points with a floor of 12, because even a
weak signal carries some information:
Factor 1, how tight the market area had to be. The model walks a ladder
of geographic strata from tightest to widest — the same street, then the phase, the
subdivision, then half a mile out to five, then the postal code — and stops at the
tightest one holding enough eligible sales. The score is that stop’s position on the
ladder, linearly: the tightest rung earns 25, the widest 12. The stratum used is named in the selection drawer.
Factor 2, the back-test error. One point deducted per percentage point of
leave-one-out error, flooring at 12 once the error reaches 13%. The factor is a restatement of
measured performance, not a second opinion about it — measured by the valuation engine on
its own proposed set, which is not necessarily the table above (see the cautions below).
Factor 3, how recent the comparables are. One point deducted per 15 days
of average age across the set, flooring at 12 once the average passes 195 days.
Factor 4, how much adjustment was needed. One point deducted per
percentage point of average absolute adjustment as a share of each comparable’s net
price, flooring at 12 at 13%. A set that needed little adjustment scores higher than one
rebuilt line by line.
When a factor cannot be measured. It is omitted rather than filled in, and
the remaining factors are averaged and scaled to the same 100-point frame; the valuation
records which factors were measured. A score built from two real factors is reported as such
rather than padded to four with invented inputs.
The tightness bonus and the cap. A set drawn from the top of the ladder
earns up to 15 additional points — 15 on the same street, 10 in the same phase, 5 in
the subdivision, nothing beyond it — and the total is then capped at 100. The bonus
covers exactly the rungs that are the same market rather than merely nearby. Labels: high at 70 or above, medium at 50 or above, low below 50 —
this property scores 71, high.
Formally. With τ the stopping stratum’s position on a ladder
of T strata (0 the tightest), ē the engine’s mean
held-out error in percent, ā the mean comparable age in days and
ḡ = n⁻¹ Σ 100|Σₖ aᵢₖ|/Pᵢ:
f₁ = round(25 − 13τ/(T−1));
f₂ = max(12, 25 − round(ē));
f₃ = max(12, 25 − ⌊ā/15⌋);
f₄ = max(12, 25 − round(ḡ)). Over the m factors
that could be measured, Q = min(100, round(4Σf/m) + B), with
B = round(15(1 − π/0.03)) for π = τ/(T−1) < 0.03
and 0 otherwise.
Two cautions the formula makes visible. Factor 4 takes the absolute value of the
net adjustment, |Σₖ aᵢₖ|, so offsetting lines cancel and a
heavily adjusted comparable can score as lightly adjusted — the opposite choice from the gross measure in
the provenance section, and the weaker one. And the score is computed by the valuation engine on its own proposed
set and its own held-out test, before this report applies the same-subdivision rule, the ±25% size standard
and the per-square-foot average: ē therefore need not equal the median error in the
table above, and the score is not recomputed when the agent edits the set.
What it is not. The deductions above are conventions chosen so the score
moves in the right direction and can be read off the inputs; they are not fitted coefficients,
the score has no sampling distribution, and no interval is attached to it. It is not a
probability and must not be read as one. The only uncertainty this report claims is the
held-out error and the bands built from it, immediately above.
How the population figures were produced. They come from the training
run’s own artifact, not from this page: a single temporal split, train on everything
closing on or before 2026-03-08 and test on the
6 months after it, so no sale in
the test set was seen in any form during fitting. 19,486 test
sales out of the full table.
Leases are removed, and the metrics are reported segmented by property type and price band as
well as overall, because a single blended figure hides exactly the segments that matter.
No interval is attached to these population figures in the artifact, and none is invented
here.
What they do and do not describe. They describe the ALEX statistical
model across a metro-wide holdout. They are not the accuracy of the comparable-sales figure
on this page, which is measured by leaving each comparable out, immediately above; the two
are different estimators on different samples and are reported separately for that reason.
Part one — what a valuation should be measured against
This section is reserved. The standard is
being supplied separately and will be placed here in full. It is deliberately empty
rather than filled with a plausible-looking threshold: a benchmark that this report happened
to pass would be indistinguishable, to a reader, from one it had actually been measured
against. Until the paper is here, no accuracy standard is being claimed or implied anywhere
in this report.
What is known today, pending that standard. Three sets of numbers exist
and none of them is a standard — they are measurements, and they are not measuring the
same thing:
1. This property. Median error 3.44%, FSD
8.95%, RMSLE 0.0803, 68% interval
±7.63%, from five held-out comparables. Specific to this house, and
thin: five observations describe this comparable set accurately and generalise weakly.
2. This model, across its blind holdout. MdAPE 7.77%,
MAPE 11.22%, RMSLE 0.1605 over
19,486 sales the model never saw during training. This is the right basis for any general claim about the
method, and it is deliberately not what the tiles above report — those answer “how
accurate is this valuation”, which is a different question.
3. What the vendors publish for themselves. HouseCanary: national MdAPE
2.8% over 1,994,203 transactions internally, 2.9% on a blind
third-party test. Zillow: median error 1.79% on-market and
7.20% off-market. Two cautions before either is treated as a bar to clear.
Both are national aggregates dominated by dense, homogeneous tract housing where an automated
model does best, and neither is conditioned on the kind of property this is. And the
on-market figure is not independent of the asking price — both vendors consume list
price, which is the whole point made in the Benchmarks section.
What a standard would need to specify to be usable here, and what the
forthcoming paper will presumably settle: which statistic is the criterion (MdAPE, FSD,
coverage, or a hit rate); whether it is a point threshold or a distribution; whether it
applies per property or per portfolio; how it is conditioned on price band, property type
and evidence depth; and whether an interval must be calibrated — that is,
whether a stated 68% interval must actually contain the outcome 68% of the time, which is a
materially stricter requirement than a median error threshold and the one most AVM
disclosures avoid.
Where this report already exceeds common practice, whatever the standard
turns out to be: the comparables are named, every adjustment is itemised with its reason,
the estimator and its weights are stated, and the held-out test results are printed so
every summary statistic can be recomputed by hand. A standard can be applied to a number; it
can only be verified against a number whose derivation is visible.
Part two — how this valuation was measured
Why hold anything out at all. Scoring a method on the same sales it was
given measures how well it can interpolate data it has already seen, which is not the
quantity anyone cares about. The quantity of interest is expected loss on an observation
drawn from the same population and not used in fitting:
Err = E(X,Y)[L(Y, f̂(X))]. Resubstitution error is
downward-biased for it by construction.
Design: leave-one-out cross-validation. The adjustments
Aᵢ are ALEX’s per-comparable adjustments to this property
(repeat-sales time carry included, the plain living-area line excluded), giving each comparable an
adjusted value per SF rᵢ = (Pᵢ + Aᵢ) / sᵢ. For
i = 1,…,n comparable i is removed and the
weighted fit is re-run on the rest, re-centred on i so the kernel weights are
distances from i rather than from this property. Writing
r̂−i for that fit read at i’s own
size, its net sale price is predicted as
P̂−i = sᵢ · r̂−i − Aᵢ
— the valuation run backwards, subtracting i’s own adjustments to carry the
prediction from this property back to i — giving
CV = n⁻¹ Σᵢ L(Pᵢ, P̂−i). The
headline statistic is the median of the absolute percentage errors; the mean is reported beside it.
Critically, the held-out comparable is excluded from the average it is predicted from; leaving its own
rᵢ in that average would leak the answer into the prediction.
What the test can and cannot see. An earlier version of this report derived a
closed-form identity here — eᵢ = n sᵢ(r̄ − rᵢ)/((n−1)Pᵢ)
— which is exact for an equal-weighted mean and is not exact for the estimator this report
now uses. Under kernel weighting the held-out fit is re-centred on the comparable being predicted, so its
weights change with i and the error is no longer a fixed rescaling of
r̄ − rᵢ. It is stated here rather than quietly deleted because the
identity was wrong for one version of this page and a reader may have taken it.
The qualitative conclusion survives the change, and it is the one that matters: the test measures how much
the comparables disagree after adjustment, and it cannot measure whether their common level is right.
An error shared by every rᵢ — a mispriced submarket, a rate table set
wrongly for all of them, a time index that is off — moves every prediction and every actual together
and very nearly cancels from every eᵢ. No held-out test on a set can detect an
error common to the whole set. That is what the population figures below are for.
Properties, and the one that governs here. LOOCV is approximately
unbiased for Err — it trains on
n−1 of n points, so the pessimistic
bias of k-fold at small k is largely
absent. It pays for this in variance: the n training sets are nearly
identical, sharing n−2 observations, so the fold-level
estimates are strongly positively correlated and Var(CV) does not
contract at the 1/n rate an independent average would.
At n = 5 this is the binding constraint on everything below
(Hastie, Tibshirani & Friedman, ESL 2nd ed., §7.10–7.12; Efron &
Tibshirani, An Introduction to the Bootstrap, 1993, ch. 17).
Forecast standard deviation.FSD = sd{ln(ŷᵢ/yᵢ)}, computed on the held-out pairs. The
log ratio is scale-invariant, so the statistic is comparable across price points and across
vendors without normalisation. Under an approximately log-normal error,
exp(±FSD) bounds a one-standard-deviation multiplicative
interval; the log-normality is an approximation and is not tested at
n = 5. This is the AVM industry's disclosure convention, which is
what makes the comparison against the vendors’ published figures like-for-like in
definition — though not in sample, since theirs are national aggregates over
millions of transactions and this is five comparables for one house.
Interval construction, and why not a normal-theory interval. The 68% and
95% figures are empirical quantiles of the absolute percentage error distribution
{|ŷᵢ−yᵢ|/yᵢ}, not
μ̂ ± zσ̂. A normal-theory interval would
import a distributional assumption the sample cannot support and would be symmetric in
levels, which a multiplicative error process is not. The trade-off is explicit: a quantile at
the 95th percentile of a handful of observations is an extrapolation of the fitted
distribution, not an observed exceedance rate, and is labelled as such wherever it is
quoted. Coverage validity requires exchangeability between the held-out comparables and the
subject — the assumption underpinning conformal prediction (Vovk, Gammerman &
Shafer, Algorithmic Learning in a Random World, 2005) — which
close, same-era selection supports without guaranteeing. It is worth noting that
conformal width calibration was measured for this pipeline and rejected: a six-month-forward
holdout violates exchangeability outright, and coverage did not improve.
RMSLE.RMSLE = [n⁻¹ Σ (ln(1+ŷᵢ) −
ln(1+yᵢ))²]1/2. Squaring in log space penalises proportional
rather than absolute error and bounds the leverage of a single large residual relative to
RMSE. It is asymmetric in levels: under-prediction is penalised more heavily than
over-prediction of the same absolute size, since
|ln(1−δ)| > ln(1+δ). The
1+ offset is vestigial at these magnitudes. RMSLE is a
relative statistic with no absolute interpretation — it exists to rank
methods, and quoting it alone says nothing.
MdAPE and MAPE.MAPE = n⁻¹ Σ |ŷᵢ−yᵢ|/yᵢ;
MdAPE is the median of the same summands. MAPE is undefined at
y = 0 and structurally asymmetric: unbounded above for
over-prediction, bounded by 1 for under-prediction, so it systematically favours methods
that under-forecast. The median is reported alongside because it has a 50% breakdown point
against the mean's 1/n. Here 6.59% against 3.44% indicates one residual pulling the mean away from the median.
Hit rates.PPEk = n⁻¹ Σ 1{|ŷᵢ−yᵢ|/yᵢ
≤ k} at k = 0.10 and 0.20 — the empirical CDF of
absolute percentage error at two points. On this property: 4 of 5 within 10%, 5 of 5 within
20%. Reported as counts, not percentages: the estimator takes only 6 values at
n = 5, and a Wilson score interval on 4/5 spans roughly
[0.38, 0.96].
Bias check. Mean signed error
n⁻¹ Σ eᵢ = +0.92%, median signed error
−2.31% (positive means the held-out prediction was above the actual net);
2 of 5 predictions were high. At n = 5 a sign is informative only
when every error shares it, and even then it describes this set, not the method.
What is not claimed, stated plainly. No standard error is attached to any
statistic here. The sampling distribution of a standard deviation at this sample size
is severely right-skewed, and a nonparametric bootstrap
resamples the same few points — it would produce an interval, and that interval would
be an artefact of the resampling rather than evidence about the population. No hypothesis is
tested and no p-value is reported, because there is no null here
worth rejecting at this sample size. These figures are offered as descriptive statistics
of this comparable set, which is what they are and the most that five observations can
support. The corresponding population-level figures — MdAPE 7.77%, RMSLE 0.1605
over a blind holdout of 19,486 sales — exist and are the right
basis for any claim about the method in general; they are not what this page reports,
because the numbers asked for are the ones specific to this property.
Statistical appendix — model, estimator and error measures
In plain terms
This is the full working behind the figure at the top of the page: which sales were used, how much each one counted, the formula that combined them, and how far off that formula was when it was tested against sales whose prices are already known.
The models used, named
Every method below is a published one, named so it can be looked up and argued with.
Nothing in this report is a proprietary formula whose behaviour cannot be checked.
Where
Method, by name
Source
Choosing comparable sales
Mahalanobis-metric nearest-neighbour matching with calipers
Ledoit & Wolf, J. Multivariate Analysis 88 (2004) 365
Combining the comparables
Kernel-weighted local linear regression (LOESS / local polynomial), with the
local-constant Nadaraya–Watson mean as its fallback
Cleveland & Devlin, JASA 83 (1988) 596; Fan & Gijbels,
Local Polynomial Modelling (1996); in housing, Meese & Wallace
(1991) and Pace (1993)
The weighting curve
Epanechnikov kernel (minimum asymptotic mean squared error)
Epanechnikov, Theory Probab. Appl. 14 (1969) 153
How many comparables are really speaking
Kish effective sample size
Kish, Survey Sampling (1965)
Adjusting a past sale to today
Repeat-sales price index (Bailey–Muth–Nourse), county indices
shrunk toward the metropolitan index
Bailey, Muth & Nourse, JASA 58 (1963) 933; Case & Shiller,
American Economic Review 79 (1989) 125
Testing the method
Leave-one-out cross-validation; median and mean absolute percentage error;
root mean squared logarithmic error; forecast standard deviation
Stone, JRSS B 36 (1974) 111
Reporting a proportion from few trials
Wilson score interval
Wilson, JASA 22 (1927) 209
Quantiles of a small sample
Hyndman–Fan type 7 interpolation
Hyndman & Fan, The American Statistician 50 (1996) 361
Excluding non-market sales
Arm's-length screen, two-pass
Fannie Mae Selling Guide B4-1.3-08; Wachter, J. Financial Economics
(2018)
Two of these are ours to defend rather than merely to cite: the distance
caliper is set at twice the chi-square median, because the subject and the comparable are
two draws and their difference carries twice the covariance; and the kernel bandwidth is
the caliper itself rather than a bandwidth read off the sample, so it is fixed before any
sale is seen. Both choices are argued where they are used.
Notation. Subject living area S. For each comparable
i = 1..n used in the valuation: net sale price Pᵢ
(closing price less seller-paid buyer closing costs less seller repair credits), living area
sᵢ, and Aᵢ, the sum of its adjustments to the subject
across every factor except the dollar living-area line (time carry, lot, age, finish and quality-of-space lines
included; agent entries replace the engine’s line where made).
Model. Each comparable is assumed to share, after adjustment, a common value per SF
with the subject: (Pᵢ + Aᵢ) / sᵢ = r + εᵢ, where
r is the subject’s value per SF and εᵢ
is comparable-specific error, taken as exchangeable with mean zero. The indication for the subject is
vᵢ = S·(Pᵢ + Aᵢ)/sᵢ. Size enters through the ratio, not
through a dollar line, so a size difference is priced once.
Estimator. The valuation is the sample mean
V̂ = (1/n) Σᵢ vᵢ — the ordinary least-squares estimate of
S·r under equal error variances. The median of the vᵢ
is reported beside it: the mean has a breakdown point of zero (one mispriced comparable moves it by
1/n of its error), the median a breakdown point of 50%. Eligibility is the appraisal size
standard |sᵢ/S − 1| ≤ 0.25, waived if it would leave fewer than three sales.
The headline converts V̂ to a contract price
C = (V̂ + R)/(1 − c), with c the seller contribution as a
share of price and R the repair credit, rounded to $500.
Out-of-sample design (leave-one-out). For each i, comparable
i is withheld and the weighted fit is re-run on the remaining
n − 1, re-centred on i so the kernel weights are
distances from i rather than from this property. Reading that fit at
i’s own size gives r̂₋ᵢ, and its net
price is predicted as P̂ᵢ = sᵢ·r̂₋ᵢ − Aᵢ;
Aᵢ carries the prediction from the subject back to comparable i.
The percentage error is eᵢ = (P̂ᵢ − Pᵢ)/Pᵢ. The
adjustments are ALEX’s and are not refit, so the design measures the weighting step and the dispersion of the
adjusted values, not the error in the adjustment model itself. A local estimator validated at the wrong centre
is not the estimator being validated, which is why the re-centring is done.
Error measures, defined.
Median absolute percentage error MdAPE = medianᵢ |eᵢ|
= 3.44%; mean absolute percentage error
MAPE = (1/n)Σ|eᵢ| = 6.59%.
Confidence interval (empirical): the q-quantile of
|eᵢ| by linear interpolation between order statistics,
Q(q) = x⃝ₖ⃝ + (h − ⌊h⌋)(x⃝ₖ₊₁⃝ − x⃝ₖ⃝),
h = q(n−1), k = ⌊h⌋ (Hyndman–Fan type 7);
the 68% band is V̂(1 ± Q(0.68)) = ±7.63%, the 95% band
±14.14%.
Forecast standard deviation:FSD = sd(ln(P̂ᵢ/Pᵢ)) with the
n−1 divisor = 0.0895; under log-normal error about 68% of outcomes fall
within ±FSD in log terms, the convention Zillow and HouseCanary use.
RMSLE:√((1/n)Σ(ln(1+P̂ᵢ) − ln(1+Pᵢ))²)
= 0.0803, symmetric in proportional over- and under-prediction.
Share within 10%: 4 of 5, Wilson 95% score interval
[38%, 96%].
Inference at small n, stated plainly. With n = 5 held-out
errors, each quantile is an interpolation between two order statistics and the sampling error of every measure is
of the same order as the measure. A parametric check: the standard error of the mean indication is
SE = sd(vᵢ)/√n, and a 95% interval on it uses Student’s
t with n−1 degrees of freedom
(t₀.₉₇₅,₂ = 4.303 at n = 3), which is why
three sales support a point estimate but not a narrow interval. The measures assume exchangeable, independent
comparables; they cannot detect an error common to every comparable (a mispriced submarket, a shared time-index
bias), which moves the valuation and the band together. Additional sales within the size standard are the only
remedy that narrows them.
The estimator, written out. Each comparable i
contributes an adjusted net price per SF
yᵢ = (Pᵢ + Aᵢ)/sᵢ, where
Pᵢ is its net sale price, Aᵢ the
sum of its adjustments other than living area, and sᵢ its floor
area. The valuation is that quantity read off at this property’s own coordinates:
V̂ = S · β̂₀, where
(β̂₀, β̂₁) minimise
Σᵢ wᵢ (yᵢ − β₀ − β₁[ln sᵢ − ln S])².
This is kernel-weighted local linear regression (Cleveland & Devlin 1988,
JASA 83:596; Fan & Gijbels 1996; in housing, Meese & Wallace 1991 and
Pace 1993). The weights are
wᵢ = 1 − (dᵢ/h)² for
dᵢ ≤ h — the Epanechnikov kernel, which minimises the
asymptotic mean squared error of this estimator — with
dᵢ the matching distance defined in the selection drawer and
h the selection caliper itself, fixed before any sale was seen
rather than read off the sample (h = 6.683).
What it replaced, and why. Until this version the same indications were
combined by a trimmed mean: from five comparables up, the highest and the lowest were
discarded on rank alone and the rest averaged with equal weight. It answered a real worry
— that one unusual sale should not carry the figure — with the bluntest available
instrument. It threw away evidence, it did so on rank rather than on distance, and it gave a
sale two doors down exactly the weight of one across the subdivision. Nothing is discarded
here. An unusual sale is handled by weighing it less, which is the same remedy applied
continuously instead of at a cliff.
The fit on this property.S = 2,104 sf, n = 5,
β̂₀ = $196.37 per SF, so
V̂ = $413,161.
The size slope is
β̂₁ = -96.4 dollars per
SF per log-foot, so a comparable 10% larger than this property indicates about
$9 less
per SF before any other difference.
The weights sum to one and their effective count is
neff = (Σwᵢ)²/Σwᵢ² = 4.7
of 5 (Kish). That number, not n, is how many comparables are
really speaking; it is printed because a weighted estimator can otherwise claim a sample it
does not have. A slope is fitted only when
n ≥ 5 and neff ≥ 4.
What each comparable actually carried. Distance is the matching distance
dᵢ from the selection drawer; the weight is
wᵢ/Σw. These are ALEX’s own figures, before any
change an agent makes on this page; edit a comparable and the weights recompute in front of
you.
Comparable
Living area
Adjusted $/SF
Indicates
Distance dᵢ
Weight
312 Susana Dr
1,960 SF
$207.83
$437,272
2.40
25.3%
100 Susana Dr
1,652 SF
$216.63
$455,779
2.41
25.3%
108 Susana Dr
1,690 SF
$217.58
$457,796
3.17
22.5%
511 Debora Dr past the caliper
1,931 SF
$189.97
$399,704
4.78
14.2%
104 Susana Dr past the caliper
1,770 SF
$226.17
$475,859
5.01
12.7%
Where this number is computed. Twice, deliberately: once on the server in
services/comp_match.py and once in the browser, because this page
recomputes the valuation the moment an agent edits an adjustment, removes a comparable or adds
one. The two implementations are checked against each other on identical inputs and agree to
floating-point precision; if they ever disagree, the figure on this page is wrong and should
not be used.
Assumptions of the model, each stated so it can be checked.
(i) Size. The per-SF step carries value in proportion to living area, and price per square
foot ordinarily falls as size rises, so proportionality alone overstates this property where it is larger than its
comparables and understates it where it is smaller. The local slope
β̂₁ estimates that departure from the comparables in hand and corrects
for it; where neff < 4 no slope is fitted, proportionality stands
unaided, and the ±25% band bounds the resulting bias without removing it. (ii) Additive adjustments. Each non-size difference is a
dollar amount independent of the others and of size. (iii) Unequal, declared weights. The
εᵢ are assumed independent but NOT identically distributed: a comparable
further from this property in the matching metric is taken to be noisier evidence and is weighted down by the
kernel accordingly. This replaces the exchangeability the equal-weighted average required. What it assumes
instead is that matching distance is a good proxy for that noise — monotone and correctly scaled. Each
comparable’s weight is printed, so a reader can judge that assumption rather than take it. (iv) The net price is right.Pᵢ uses the seller-paid closing costs and repair amount as recorded in the MLS
concession fields; a concession recorded nowhere, or recorded wrongly, is carried as recorded. (v) One time
path. Each comparable is adjusted to the latest index month by the repeat-sales factor, applied to land and
structure alike.
What the model cannot detect. Any feature of this house that none of the adjustment lines
measures (condition not captured in the listing, layout, noise, a view the data do not record) is outside
Aᵢ, and if the comparables share it, it is also invisible to every error measure in this
drawer.
Range — the lowest and the highest, and the weighting inside it
In plain terms
Lowest and highest adjusted net
sale value of comparable sales. It is not a guess at the highest and lowest price this house
might fetch: it is what the comparable sales each point to on their own, so you can see how
far apart the evidence is before it is combined. The comparables are not treated equally
— the closer a match, the more it counts — and that weighting is what decides
where inside the range the valuation lands.
How the two ends are built. Each comparable’s net sale price
Pᵢ plus its adjustments to this property
Aᵢ, divided by its own living area sᵢ, is its
adjusted value per SF; multiplied by this property’s 2,104 SF it is that comparable’s
indication Iᵢ = (Pᵢ + Aᵢ) / sᵢ × S. The cell reports
minᵢ Iᵢ and maxᵢ Iᵢ, each adjusted to
the same basis as the figure above by (v + R) / (1 − c) —
R the repair credit, c the closing-cost share — and
rounded to $500. The plain living-area dollar line is left out of Aᵢ, because
the per-SF step already carries size; adjustments for the quality of the space, such as second-floor area,
stay in.
The ends are NOT weighted. The valuation is. This is the distinction to
hold on to. The two ends are what single comparables say, each on its own, and no weighting
is applied to them — a comparable carrying 6% of the weight still sets the low end if
it is the lowest. Weighting them would narrow the range toward the answer and hide exactly
the disagreement this cell exists to show. What the weighting does is decide where the
valuation sits between those ends.
The weighting, in full. Every comparable that survives selection is used
— nothing is discarded — and each is weighted by how near it is to this property
in the matching metric described in the selection drawer. The weight is
wᵢ = 1 − (dᵢ/h)², the Epanechnikov kernel, where
dᵢ is that comparable’s distance from this property and
h is the bandwidth, here
6.683. Three properties of that
formula matter:
(i) It is a curve, not a cliff. A comparable does not count fully and then stop
counting. Weight falls away smoothly with distance, so a sale that is slightly further off is
worth slightly less, not nothing.
(ii) The bandwidth is fixed before the sales are seen.h
is the selection caliper itself, not a number read off this set. A bandwidth chosen from the
data can be tuned, knowingly or not, until the answer looks right; this one cannot, because
it was settled before any comparable was chosen.
(iii) Epanechnikov is the minimum-variance kernel (Epanechnikov 1969), meaning
that among all kernel shapes it gives the smallest expected squared error for this estimator.
It is also gentler than the tricube shape used in classical LOESS, which matters at these
sample sizes: on an earlier build tricube put 41% of the weight on one sale and 1.8% on
another, which is a six-comparable valuation resting on two.
How much is really speaking. Because the weights are unequal, the count of
comparables overstates the evidence. The honest count is Kish’s effective sample size,
neff = (Σwᵢ)² / Σwᵢ², which here is
4.7 of 5. That figure, not 5, is what the
error measures should be read against. Each comparable’s own weight is printed in the
statistical appendix, so the weighting can be checked rather than taken on trust.
The weighted interval, for contrast. The range in the cell is the spread of
the raw evidence. The weighted fit also produces an interval of its own around the valuation:
$387,838 to
$438,490 at one standard error,
and $346,051 to $480,277
at roughly 95%. These are narrower than
the raw range because they describe uncertainty about the fitted value, not the disagreement
among the comparables. Both are printed because they answer different questions, and quoting
either as though it were the other would overstate what is known.
What it is and is not. Two readings of the same 5 indications
the valuation is fitted through. The low end is the least any one comparable supports for this house and the
high end the most. Neither is a confidence interval and neither carries a probability. With
5 comparables both ends are extremes of a very small sample and will move as
evidence is added — an extreme is the least stable statistic a small sample has. For a statement
carrying a probability, use the error band in the Confidence card.
Why per SF and not per house. The comparables are different sizes. Their adjusted
totals would answer “what did those houses sell for”, which is not a value for this
property. Dividing by each comparable’s size and re-multiplying by this property’s answers the
question actually asked, and it is why the plain living-area dollar line is kept out of
Aᵢ — otherwise size would be counted twice.
It moves when the agent works. Every figure here is recomputed in the page from the
comparables as they currently stand, including the agent’s adjustments, additions and removals. The
server’s own first pass is not what you are reading once an agent has touched a line.
Asking price
In plain terms
How the current asking price sits against what the comparable sales support, and what the price history since listing says about it.
What this is. The current asking price as the MLS carries it. It is a
datum, not an estimate: it has no error, because it is not measuring anything. It is what the seller is asking.
Why it is not evidence of value. An asking price is one party’s opening position.
Across the comparable pool the median sale closed at
98.9% of the asking
price, and 64% of those sellers had already reduced before they sold
— which is why this report values the property from
closed sales and reports the asking price beside that valuation rather than inside it.
Days on market. 6 days
as counted from the listing contract date. The feed’s own days-on-market field resets when a price
changes, so it understates time on market for any property that has been reduced; this report does not use it.
Confidence — the error band, FSD and RMSLE
In plain terms
How much weight to put on the figure. The method is tested by hiding one comparable sale at a time, valuing it from the others, and comparing that with what it actually sold for. The band comes from those misses, not from an opinion.
How it is measured. Leave-one-out cross-validation on this property’s own comparable
set: each of the 5 comparables is removed in turn and the fit is re-run
without it — re-centred on that sale, with the kernel weights recomputed as distances from it —
then read at its own size and adjusted back to a net sale price, less its own adjustments, and compared with
what it actually sold for. Every number below comes from those
5 held-out errors — none of it is a published benchmark or a figure
carried over from another property.
Confidence level and band. At the 68% level,
±7.63%
($381,627 to $444,695). At the 95% level,
±14.14%
($354,756 to $471,566). These are empirical quantiles of the held-out absolute
percentage errors — the 68th and 95th percentile of what the errors actually were — not a normal
interval around the estimate. At 5 observations the 95% figure rests on the largest error or two and
should be read as indicative; the 68% figure is the more stable of the two.
FSD and RMSLE on this property. FSD
0.0895 — on the vendor convention of
1 − FSD that reads 0.9105,
and in dollars ±$36,988. RMSLE
0.0803, over the same 5 held-out pairs. Both are
defined under their own cards at the head of this report. FSD is reported beside, never instead of, the
error band above: it assumes a log-normal shape that 5 points cannot confirm.
Error distribution. Median absolute percentage error
3.44%; mean
6.59%; worst single error
15.35%.
4 of 5 held-out valuations landed within 10% (Wilson 95% interval 38%–96%),
5 of 5 within 20%. The mean sitting above the median is the ordinary sign of a
right-skewed error distribution: most valuations are close, a few are not.
What this does not claim. The errors are measured on the same comparables that built the
valuation, in the same submarket, over the same period. They describe how well this method reproduces these
sales; they are not a guarantee about the sale price of this house, and they cannot detect an error shared by
every comparable in the set — a mispriced submarket moves the valuation and the error band together.
With 5 observations, treat every figure in this drawer as an estimate with its own uncertainty.
Evidence — the comparable set
What is being counted. 5 closed sales used as comparables.
Every valuation figure in this report is built from these 5; no other sale, model
output or vendor estimate enters the number.
How they are combined. Each comparable’s net sale price is adjusted for every
difference from this property except size; the adjusted net is divided by that comparable’s living
area to give its adjusted value per SF, and that is multiplied by this property’s
2,104 SF. The valuation is the average of those indications, with the median
reported beside it. Only comparables whose living area is within ±25% of this property’s are
used — the appraisal size standard — unless that would leave fewer than three.
Why 5 is a small number, stated plainly. With 5 observations
the average has real sampling uncertainty — each comparable moves it by a full
1/5 of its own error — the median and maximum beside it are read from the
same small sample, and where cross-validation was possible every accuracy figure above rests on 5 held-out points.
The defensible reading is that this is the best available evidence for this property, not that it is precise.
Selection. All within Sierra Vista
Benchmarks
ALEX — this report, shown for comparison$414,051Our net $413,161 grossed back up to a contract price using the ratio Sierra Vista sales actually run at, so it can be set beside the outside estimates below. Five Sierra Vista sales, each adjusted to this property for every difference but size, divided by its own living area and multiplied by this house’s 2,104 SF; the valuation is a distance-weighted fit through those indications, read at this property’s own size, median $455,779, highest $475,859, before the agent’s changes.
Click here for details
In plain terms
Three other services
publish a number for this house. They are shown above so you can see what else is
being said about it. None of them was used to produce our figure, none of them can be
checked from the outside, and two of them start from the asking price — which is
what a seller wants, not evidence of what the house is worth.
What the chart shows
Each estimate as a bar on one money scale, with its published range
shown behind it where the vendor publishes one. ALEX’s valuation is the crimson
bar — the same figure as the head of this report. The gold bar is that same
valuation grossed to a contract price, which is the basis the outside estimates quote on and
the only basis on which they can honestly be compared with ours.
The outside estimates below were not used to produce our number.
Each “vs ALEX” percentage compares that vendor with
$414,051 — our net figure grossed to a contract price by the neighbourhood
ratio described in the drawer below — not with the figure at the head of this report,
because the vendors publish contract-price estimates and a net price is not the same quantity.
They are here so you can see what else is being said about this house. Each is a contract price, and
each is compared with the ALEX figure above.
Outside source
Value
Range
vs ALEX
What it is
HouseCanaryconfidence 90%, HIGH
$427,364
$384,277–$470,451
+3.2%
A national automated valuation, quoting its own forecast standard
deviation of 10%. Retrieved with this valuation run.
Zillow Zestimate
$186,707
$168,036–$205,377
−54.9%
Zillow rates its own confidence here “Low”. It cannot see the interior, the condition, or the subdivision
boundary that governs this comparable set.
Williamson CADparcel R098324
$387,192
—
−6.5%
2026 appraised value: land $82,500 plus improvement $304,692; prior year
$385,589. A tax assessment, not an opinion of market value —
produced en masse for taxation, lagging by design, and capped by statute.
How close any model can get
There is a floor, around
±5%. No model can reliably predict a single sale much closer, because sales
themselves disagree — the same house listed twice in one month will not fetch the same
price. Different buyers, different negotiation, different day. That scatter is how houses are
sold, not a flaw in any model, and more data will not remove it. Treat any accuracy claim much
tighter than ±5% on one property with suspicion.
What we will and will not claim about that floor.
The ±5% figure above is a judgement about transaction noise, not a published result we can
cite, and this report does not rest on it: nothing here is measured against 5% or against any
industry target. What is measurable is on this page — the held-out error on this property
and the population figures in Cross Validation — and that is the only standard this
valuation asks to be judged against.
Why these are benchmarks and not evidence
The vendor models are proprietary.
Zillow, HouseCanary and Cotality — the company that acquired CoreLogic — publish
neither their methods, their parameters nor their data, and their accuracy figures are
self-scored on samples they choose. Nobody outside those companies can
reproduce a number, test an interval, or prove any of it wrong — which is the minimum
before a figure counts as a defensible statistic. Good commercial products; not evidence in the
sense this report uses the word.
This does not make the vendor numbers useless. We use them as benchmarks. We do not include them in our valuation model.
How the comparison in the table is computed
What each number in the table above is, and the arithmetic that produced it.
Notation.V̂ the net valuation,
ρ̂ the neighbourhood median of net ÷ close (Sierra Vista,
n = 34, ρ̂ = 0.9979),
G = V̂/ρ̂ the ALEX figure grossed to a contract price, and
x an outside figure. The “vs ALEX” column is
100(x − G)/G. Here G = $414,051;
HouseCanary +3.2%; Zillow
−54.9%; the county roll −6.5%. Against the asking price,
100(G − list)/list = −1.4%.
Assumptions and limits of the comparison. Each percentage is a difference between two
estimates, not between an estimate and the truth: it says the two disagree, not which is nearer the eventual
price. Its uncertainty is at least that of either side — a gap smaller than a vendor’s own FSD
or this report’s (8.95%) is within that estimate’s typical error.
G carries the error in ρ̂, a median with no interval,
on top of the error in V̂. Vendor figures are as retrieved with this valuation run
and change without notice; the roll is a January 1 mass appraisal. No outside figure enters the valuation.
Why an undisclosed model is not a defensible statistic. A figure is
defensible when someone else can reproduce it: the estimator is specified, the data are
identified, and the validation protocol is stated. Both vendors publish outputs and accuracy
summaries; neither publishes the estimator, the trained parameters, or the data. Their
accuracy figures are therefore self-reported and self-scored on samples they select. This is
normal commercial practice and not a criticism of their competence — it is a statement
about what an outside reader can check, which is: the claim, but not the calculation.
Zillow, in its own words. The Zestimate is described as combining
“public records, MLS data and user-submitted home details into Zillow’s
proprietary home valuation model,” offered as “a transparent, free starting
point,” and explicitly “not an appraisal and can’t be used in place of an
appraisal.” Published accuracy: nationwide median error 1.79% on-market
and 7.20% off-market — meaning half of on-market Zestimates fall
within 1.79% of the eventual sale price. Zillow states directly that on-market estimates are
more accurate “because more up-to-date information is available, including listing
details and recent market activity.” No specification, feature list, or training data
is published.1
HouseCanary, from its published technical brief. Considerably more is
disclosed. The algorithm runs in three stages: (1) query and clean data; (2) build localised
price indices; (3) train machine-learning models on time-adjusted historical prices. Models
are fitted at census-tract level, borrowing from neighbouring tracts where a tract
is too thin to model alone, with neighbours used for training but excluded from accuracy
testing. Two index models are built — median price and median price per SF
— at census-block level, and all historical sales and list prices are carried
to current values through them. The response variable is each price expressed as a percent
deviation from its block’s current median for that property type; several ML models
per tract are then fitted to explain that deviation and combined into one estimate.
Inputs include 3,100+ county assessors, 2,700+ county recorders over 20 years, MLS
characteristics, listed prices and contract prices, mortgage balances and distress
measures. In non-disclosure states such as Texas, MLS contract prices substitute for
recorded sale prices where an arm’s-length sale can be jointly verified
— directly relevant here.2
HouseCanary’s FSD, and an important caveat they state themselves.
FSD is trained on the census-tract empirical error distribution and depends both on that
spread and on how much the component models disagree for the individual property. The
confidence score is simply 1 − FSD, which is why the 90%
confidence reported for this property corresponds to an FSD of 0.10. The interval is
constructed for approximately 68% coverage: P(1 ± FSD). And
in their own words: “We assume symmetry but not normality... using 2*FSD to
estimate a new interval is not guaranteed to yield an approximate 95% coverage
probability.” Anyone doubling their FSD to get a 95% band is doing something the
vendor explicitly warns against.
What HouseCanary validates, and how. Monthly internal testing on a
rolling six-month window, plus quarterly blind third-party testing. As of July 2019: national
MdAPE 2.8% over 1,994,203 transactions internally, and 2.9%
on the third-party blind sample for Q1 2019. They report hit rate, MdAPE, median signed error
(as a bias check), within-5/10/20%, and the share of sales falling inside their own 68%
interval — a coverage check, which is the right diagnostic and more than most vendors
publish. Results are available by state and MSA on request, which is the boundary of
the disclosure: the validation design is public, the validation data are not.
The comparison this page makes, and its limit. FSD is a shared
convention, so this report’s 8.95% and theirs are the same quantity —
the standard deviation of log(estimate ÷ outcome). But they are computed on different
samples by different methods: theirs across millions of national transactions, this one
across five comparables for this house. A national median error says what happens to a
typical home; it does not say what happens to this particular property and its own comparables. Reading a vendor figure as a promise about this house would be a category
error, and reading ours as vendor-grade inaccuracy would be the same error in reverse.
What this report exposes by contrast. The estimator is stated, the
comparables are named with MLS numbers, every adjustment is itemised with its reason, the
index method is a published 1963 regression with its exclusions listed, and the
held-out test results are printed so every summary statistic can be recomputed by hand.
Whether the answer is right is a separate question; whether it can be checked is not.
Listed September 24, 2026 at $419,900, with no reduction since.
$400,000
$405,000
$410,000
$415,000
$419,900first askedOriginal Sep 24, 2026
List price
Reduction, $
Reduction, %
$ per SF
Original, September 24, 2026
$419,900
—
—
$200
The VA appraisal
Offer, contract price$419,900
Seller-paid costs$8,000
Offer, net to seller$411,900
Financing100% VA
The financing makes the VA appraisal, not the asking price, the number that
governs. A VA-guaranteed purchase is appraised by an appraiser the VA assigns, who issues a Notice
of Value. Where that notice comes in below the contract price, you can make up the difference, or you can
terminate the contract and get your escrow money returned.
The comparable sales set the net evidence, and this offer nets the sale price to
$411,900. The ALEX AI Statistical Model ranges from
$382,299 to
$440,793, with an average of
$413,161; the average of the
Traditional Arithmetic Model is $445,281.
The VA’s appraiser will form an independent opinion from the same kind of evidence. This is the case
that can be put in front of them. It is not a prediction of what they will write.
Diane will guide the strategy with you.
Move the price, not the credit. Because
you are financing 100% with no down payment, that $8,000 of seller-paid closing
costs helps make the VA purchase closable. Trading it away creates a higher cash requirement for you at the
closing table. If necessary, raise the contract price and keep the $8,000 credit intact.
Every suggested counter keeps the full $8,000 credit for you at closing.
One gate remains: the Notice of Value. If the VA appraiser comes in
below the contract price, you can make up the difference if you want, or you can terminate the contract and
get your escrow money returned. The counter ceiling in the negotiation section is about what to concede
willingly, not about what the loan will permit. You control which counter is used and when, or if you want
to counter at a different price.
What is a Time Adjusted Net Sale Price?
Two steps. First the net sale price: what the seller
actually kept, which is the closed price less anything they paid toward the buyer’s
closing costs and less any repair credit. Two houses can both close at $500,000, and if one
seller paid $15,000 toward the buyer’s costs, those are not the same sale.
Then the time adjustment. A house that sold ten months ago
sold in a different market from today’s. Rather than guess what it would fetch now,
ALEX measures how prices in this county have actually moved, month by month, from houses that
sold twice — the same house, bought and sold again, which is the one comparison where
nothing about the property itself has changed. That measured movement is applied to each
sale, adjusting it to today. On the table below, the column marked
Market trend to today is exactly that adjustment, in dollars and as a share
of the sale; add it to the net sale price and you have the time-adjusted net sale price.
Divided by the house’s floor area, it is the figure every comparable is ethically
and statistically compared to.
104 Susana Dr, one of the comparables in this report and
the one the market moved most. It closed at $380,000, with no concessions, so the closed
price is also the net. Adjusting that to today on the index
adds $5,724, giving
$385,724 — which across its
1,770 SF is $218 per square
foot, the figure it is compared on.
All sold homes used for report data
The chart below
counts these sales — 170 homes sold in
ZIP 78628, Georgetown, between
August 18, 2025 and August 14, 2026, which closed between
$357,000 and $480,000.
What sellers actually gave, and how much
What the seller did
Share of sales
Least
Middle
Average
Most
Sales
Gave nothing at allWhat the buyer offered is what the seller got
32.0%
— every one of these is $0
—
Cut the asking price firstLowered the price before the house sold
63.6%
$4,000
$32,256
$40,641
$179,900
108
Paid the buyer’s closing costsChipped in on what the buyer owes at closing
54.4%
$300
$10,000
$9,383
$25,000
96
Credited repairsMoney back for repairs, usually after the inspection
24.5%
$35
$1,000
$2,409
$25,000
41
Shares are of all 170 sales in the pool. The four money
columns describe only the sales where something WAS given, which is why they are read across a
smaller count in the last column: an average that included the sales giving nothing would
understate what a concession costs when one is asked for.
Click here for details
The pool. single family residence resales in
ZIP 78628, Georgetown
— the pool is selected by the subject’s own ZIP, the tightest geography the feed carries
that a reader can check against the address. City and MLS area are used only where no ZIP is on
the record; an MLS area is not a ZIP and neither nests inside the other.
Sun City and other 55-and-over communities are excluded, asking between $357,000 and
$483,000 (the band actually observed runs
$359,000 to $482,500), closed
August 18, 2025 through August 14, 2026: 170 sales.
Recent sales count more heavily, so every share quoted is a weighted share, and the two
payment shares overlap — a sale can carry both a closing-cost credit and a repair
credit, so they do not sum to the share that paid anything at all.
What is being estimated. Four proportions in one pool of closed sales:
p₀ = Pr(C + R = 0), the share where the seller paid nothing toward
the buyer’s closing costs and credited no repairs, and
pᵣ = Pr(original list > list), the share that had reduced the asking
price before the sale; and the same pool split the other way,
pᶜ = Pr(C > 0), the share where the seller put something toward the
buyer’s closing costs, and pᵣ = Pr(R > 0), the share that
credited repairs. All four are properties of this pool, not forecasts for this property.
pᶜ and pᵣ are not mutually exclusive
— a sale carrying both is counted in each — so they do not sum to
1 − p₀ and should not be read as a partition.
Weighting, and why the interval is not built on 170. Sales are
weighted by recency on a 6-month half-life,
wᵢ = 2^(−aᵢ/h) with aᵢ the
age of the sale in months, so the estimate is the weighted proportion
p̂ = Σwᵢxᵢ / Σwᵢ. Weighting costs
information: the effective sample size is
nᴱ = (Σwᵢ)² / Σwᵢ² =
147.8 against 170 rows, and every interval below uses
nᴱ. Using the row count instead would overstate precision by
about 1.1 times.
Intervals. Wilson score intervals at 95%, which is the right choice here
because a share near 0 or 1 makes the normal approximation cover badly and can put a bound
outside [0, 1]:
gave nothing 32.0%
[25.1%, 39.9%];
had cut the price 63.6%
[55.5%, 70.9%];
paid closing costs 54.4%
[46.4%, 62.2%];
credited repairs 24.5%
[18.3%, 32.0%].
The intervals assume the sales are independent. They are not entirely: sales cluster by
subdivision, by listing agent and by month, so a cluster-robust interval would be wider.
Read these as the narrowest defensible bounds, not the final word.
Measurement limits, stated rather than buried. A zero and a missing value are
indistinguishable in the concession fields, so p₀ is an upper
bound on how often a seller truly gave nothing. The reduction test compares the feed’s
original list price with its current one, and a relisting can reset that original, so
pᵣ is a lower bound on how often an asking price came down.
Neither is corrected by a guess.
Interval formula. For a weighted proportion p̂ with effective
size nᴱ = 147.8 and z = 1.96, the Wilson
score interval is
[p̂ + z²/2nᴱ ± z√(p̂(1−p̂)/nᴱ + z²/4nᴱ²)] ÷ (1 + z²/nᴱ)
— the inversion of the score test, which keeps both bounds inside [0, 1].
Assumptions. The pool is treated as one population, stationary within the window once
recency weighting is applied: the half-life down-weights older behaviour but does not model a change in it.
Sales are treated as exchangeable within the pool whatever their price inside the band, subdivision or listing
agent.
How this connects to the valuation, and how it does not. None of these shares enters the
valuation. Each comparable’s net sale price is computed from its own recorded figures,
Pᵢ = closeᵢ − Cᵢ − Rᵢ, with
Cᵢ the buyer closing costs its seller paid and Rᵢ
its repair amount, both read from that sale’s MLS concession fields. The pool says how common concessions
are; it is never used to impute one to a sale. Its
recency-weighted mean contribution share,
s̄ = Σwᵢ(Cᵢ+Rᵢ)/Pᵢ ÷ Σwᵢ = 1.37%,
feeds the offer ladder and the page’s closing-cost control, not the valuation.
What the net price cannot detect. A concession delivered outside those two fields — a
credit entered in another field, or one paid outside the closing — leaves
the net equal to the closed price, so in exactly those cases the net overstates what the seller achieved. An
amount entered in error is carried as entered: Texas is a non-disclosure state, the settlement statement is not
public, and nothing in the pipeline audits the MLS figure against it.
Pool and exclusions. Single Family Residence
resales in
MLS area GTW, asking price within
±15% of this property’s, at least 7 days on market, closed
August 18, 2025 to August 14, 2026 with a
45-day settle window so pending sales cannot enter, and a
36-month cap on age. Sun City and other 55+ communities are excluded, as is new
construction: both negotiate on terms a resale does not.
Market timing: adjusting a past sale to today
Market timing
How each comparable’s time-adjusted net sale price was calculated
The factors and adjustments in this section are
ALEX’s. Where an agent has changed or zeroed a market-timing line, the adjustment details
for that comparable show the agent’s figure and this table still shows ours, so the two
can be compared rather than one quietly replacing the other.
A sale that closed months ago is a snapshot in time. To use it as evidence about today,
it has to be moved forward by however much the market moved in between. That is what the
market timing line on each comparable does.
The Williamson County
repeat-sales index, month by month. Each gold dot is one comparable at the month it closed;
the line above it runs up to today’s level, the dashed red line. That
climb is the adjustment in the table below — the further back a sale sits, the further
it has to travel, which is the whole of what a market-timing adjustment does.
Comparable
312 Susana Dr
100 Susana Dr
108 Susana Dr
511 Debora Dr
104 Susana Dr
Close month
2026-07
2026-05
2026-05
2025-11
2025-12
Index then
170.570
166.970
166.970
170.064
165.558
Index now
167.172
167.172
167.172
167.172
167.172
Factor
0.9852
1.0065
1.0065
0.9882
1.0151
Adjustment= “Market trend to today” above
−$5,439
+$2,350
+$2,284
−$4,283
+$5,724
Adjustment = net sale price × (factor − 1). All come from
the Williamson County index, built from 19,824 repeat-sale pairs.
What the index numbers mean.
They are not dollars and not percentages — they are a scale, and every scale needs a zero.
Here the zero is January 2016, set to 100. That month
is the base by construction: the regression fixes its value and measures every later month
against it. So a reading of 167.172 for September 2026
means Williamson County house prices are 67.2%
above where they stood in January 2016.
What this section does not claim
What no figure in this section carries. No standard error is computed
for any monthly index level, and therefore none for the factor applied to a comparable. The
repeat-sales regression would support one — the residual variance of the log price
differences is estimable — but it is not computed in this pipeline, and an interval that
has not been computed is not printed. What the section does state instead is the evidence
behind each month: the number of repeat-sale pairs, and the shrinkage weight applied when a
month is thin. A month resting on a handful of pairs is pulled toward the metropolitan path
for exactly the reason an interval would be wide there.
The model
Specification. Bailey, Muth & Nourse (1963),
A Regression Method for Real Estate Price Index Construction, JASA 58(304),
933–942. For a dwelling transacting at periods s and
t with s < t, the model is
ln(Pᵗ/Pₛ) = βᵗ − βₛ +
εₛᵗ. Let X be the
N × T design matrix with
xᵢₛ = −1,
xᵢᵗ = +1 and zero elsewhere. Then
β̂ = (X′X)⁻¹X′y with
yᵢ = ln(Pᵗ/Pₛ). The base period is normalised to
β₀ = 0 and its column deleted; retaining it makes
X′X singular, since the indicators sum to zero by
construction. The index is Iₜ = 100·exp(β̂ₜ).
Identification. The estimator is consistent for the market factor under
the assumption that E[ε | X] = 0 — that idiosyncratic
price changes are mean-independent of when a property happened to transact. Dwelling fixed
effects difference out exactly because the same unit appears with opposite signs on both
sides, which is what removes omitted-variable bias from unobserved quality and is the
method’s central advantage over a hedonic index.
Error structure. Case & Shiller (1987, New England Economic
Review; 1989, AER 79(1), 125–137) decompose
εₛᵗ = (Hᵗ − Hₛ) + (uᵗ −
uₛ), where H is a Gaussian random walk in the
property’s own value and u is i.i.d. transaction noise. The
implied variance Var(ε) = σ²ᵘ(t−s) +
2σ²ᵤ grows linearly in the holding interval, motivating their
three-stage weighted least squares: OLS, regress squared residuals on the interval, then GLS
with weights 1/√(â + b̂(t−s)). This index
does not apply that weighting. It instead excludes holds under 180 days and annualised
changes beyond ±60% outright — a trimming rather than a down-weighting
strategy, which is more conservative, discards information the WLS would retain, and is
stated rather than left implicit.
Shrinkage. County-month estimates are shrunk toward the metropolitan
estimate in log space,
ln Iᶜₜ = w ln Iᶜₜᶜ + (1−w) ln
Iᵐₜ with w = n/(n+k),
k = 20. This is the James–Stein / empirical-Bayes posterior
mean under a normal-normal hierarchy where k is the ratio of
within-month sampling variance to between-county prior variance; here it is fixed rather
than estimated. The effect is that thin months borrow strength in proportion to how little
evidence they carry of their own — September 2026, with 38 pairs, sits at
w = 0.655.
Limitations, and what was tested
Known limitations. (i) Sample selection. The index is estimated
only on dwellings that transacted at least twice, which is not a random sample of the
stock; properties that turn over frequently differ systematically, and no Heckman-type
correction is applied. (ii) Revision. Estimates for recent periods move as later
transactions arrive, so the most recent months are the least stable — a property
shared with all repeat-sales indices including S&P CoreLogic Case–Shiller.
(iii) Renovation. The dwelling-constant assumption fails where a property was
materially improved between sales; the ±60% annualised filter removes the extreme
cases and cannot remove the moderate ones. (iv) Aggregation. A single county index
assumes a common market factor across submarkets within it.
Empirical note on smoothing. A trailing three-month average of the log
index was tested against the raw monthly series by ten-fold cross-validation on 20,631
Williamson County pairs (September 2026), scoring out-of-sample RMSE of predicted log price change. It was worse in
10 of 10 folds (mean difference +0.00171, 95% CI [+0.00139, +0.00202],
t = +10.70); a five-month window was worse again
(t = +22.77). Monotonicity in the smoothing window is the signature
of signal removal rather than noise suppression, consistent with the shrinkage above already
performing the variance reduction a second pass would duplicate.
Applying the index to one comparable
From the index to a comparable’s line. For a comparable that closed in month
m, the factor is fᵢ = Im* / Im and the
line is Pᵢ(fᵢ − 1), with m* the month shown as
“Index now”; the index’s latest month is September 2026, level
167.172 against January 2016 = 100, estimated from
19,824 repeat-sale pairs for Williamson County. The line enters Aᵢ like any other, so it passes through the
per-square-foot step and the held-out test unchanged.
Assumptions specific to its use here. The factor multiplies the whole net price, so land and
structure are assumed to appreciate at one rate, and the county
rate is assumed to hold for this subdivision and price band. A sale is adjusted to m*, not
to the report date; movement after the latest index month is not in the figure. And because every comparable is
adjusted by the same index, an error in its recent level is common to the whole set: it moves the valuation and
does not appear in the held-out error.
The land
Land Values from County Appraisal District
No county land rate is available for this parcel, so lot differences are priced from the adjustment schedule
and no county figure is shown.
Click here for details
In plain terms. Each comparable is moved by the difference in lot size times one land rate
per SF, taken from the county’s own figures for this parcel.
How the land adjustment is computed
Model. Land is priced at a constant rate per SF of lot. For comparable
i the land line is
aᵢlot = (L − ℓᵢ) · λ, with
L this property’s MLS lot size (17,437 SF),
ℓᵢ the comparable’s MLS lot size, and
λ = land value ÷ (acres × 43,560) from this property’s own county
record.
The comparable’s own county rate is used only when this parcel has none; where neither exists the line is
zero and flagged (GEN-020) rather than estimated. No cap is applied. A line of 10% or more of the
comparable’s net sale price, |aᵢlot|/Pᵢ ≥ 0.10, raises a
variance notice (GEN-005) and changes no arithmetic. The table’s “Difference” is
ℓᵢ − L and “Share of net” is
|aᵢlot|/Pᵢ. The line is part of Aᵢ
and passes through the per-square-foot step like every other non-size adjustment.
Assumptions and limits
Assumptions. (i) Linearity. Every SF of lot is worth the same, the
5,000th and the 50,000th alike. The marginal value of land ordinarily falls as lots get larger, so an average
rate applied to a large difference tends to overstate it, and the bias is largest where the line is largest.
(ii) The county’s land value is a market value. It is a mass-appraisal figure set by schedule for
taxation; how closely it tracks what buyers pay for land is not tested here. (iii) One rate for the
set. This parcel’s rate is applied to every comparable, which suits a set drawn from one subdivision
and suits it less as the set spreads out.
What it cannot detect. Usable land is not lot area: slope, flood plain, easements, shape,
frontage and view are not in ℓᵢ and are not priced by this line, so two lots
of equal size can differ materially in value. The MLS lot size sets the difference and the county record sets the
rate. No interval is attached to λ: the
county publishes none, and none is invented.
Where everything is
The properties
Everything is within about a mile. Every marker is clickable.
A red circle jumps to that comparable sold property in the table below. A blue diamond jumps to the for-sale property in its own section.
Solid red lines join the five comparables to the subject.
Dashed blue lines join the five properties currently for sale.
Those properties are shown for reference. They are not used in the valuation.
Comparable sales — used in the valuation.511 Debora Dr —
0.06 mi south312 Susana Dr —
0.28 mi north-east108 Susana Dr —
0.52 mi north-east104 Susana Dr —
0.54 mi north-east100 Susana Dr —
0.57 mi north-eastThey are joined to the
subject by solid red lines.
Each one carries the adjustments set out later in this
report.
Properties for sale — reference only, not used in the
valuation. 406 Tamara Dr 0.21 mi
east, 625 Luther Dr 0.31 mi
east, 306 Debora Dr 0.32 mi
east-north-east, 302 Debora Dr 0.34 mi
east-north-east, and 303 Pin Oak Dr 0.43 mi
north-east. None has sold.
None is evidence of value.
They are joined to the subject by dashed blue lines.
Those lines mark the difference.
All are shown for one reason. A buyer viewing this property will also be viewing them:
see Other Properties for Sale.
Time-adjusted net sale price per SF across these
5 comparables
Each bar is that sale’s net sale price adjusted to today on the
repeat-sales index and divided by its own living area — the final column of the table
above, and the figure every comparable is compared on. The colours are the same ones the
table uses, so a sale can be found in both without counting rows.
Click here for details
How to read the columns
The columns run in the order the arithmetic runs. The closed price, less what
the seller paid toward the buyer’s closing costs, less any repair credit, is the
net sale price. The market trend then adjusts that sale from
its closing date to today on the repeat-sales index — shown in dollars and as a share of
the net — giving the time-adjusted net sale price. Divided by that
house’s own living area, it becomes the time-adjusted net sale price per square
foot in the final column.
A sale that closed last month barely moves; one that closed a year ago moves by whatever this
market did in that year.
Each sale in detail, with its adjustments
312 Susana Dr
MLS4046589Days on market28Original list$392,000Sale price$375,000Net, time-adjusted$362,936Per SF$185
Living area1,960 SFBeds4Baths2Year built1985LevelsOneLand8,830 SF (0.20 ac)Garage2-carTypeSingle Family Residence
Front exteriorLiving areaKitchenPrimary bedroomBathroomBack yard
100 Susana Dr
MLS9111148Days on market41Original list$380,000Sale price$375,500Net, time-adjusted$365,121Per SF$221
Living area1,652 SFBeds3Baths2Year built1994LevelsOneLand15,520 SF (0.36 ac)Garage2-carTypeSingle Family Residence
Living areaKitchenPrimary bedroomBathroomBack yardLaundry
108 Susana Dr
MLS5219415Days on market102Original list$380,000Sale price$352,500Net, time-adjusted$354,784Per SF$210
Living area1,690 SFBeds3Baths2Year built1995LevelsOneLand8,181 SF (0.19 ac)Garage2-carTypeSingle Family Residence
Living areaKitchenPrimary bedroomBathroomBack yardGarage
511 Debora Dr
MLS7511020Days on market6Original list$370,000Sale price$375,000Net, time-adjusted$357,717Per SF$185
Living area1,931 SFBeds3Baths2Year built1993LevelsOneLand12,066 SF (0.28 ac)Garage2-carTypeSingle Family Residence
Living areaKitchenPrimary bedroomBathroomBack yardCovered patio
104 Susana Dr
MLS1592521Days on market10Original list$374,900Sale price$380,000Net, time-adjusted$385,724Per SF$218
Living area1,770 SFBeds3Baths2Year built1995LevelsOneLand8,329 SF (0.19 ac)Garage2-carTypeSingle Family Residence
Living areaKitchenPrimary bedroomBathroomBack yardLaundry
Neighborhood
About the neighborhood
Property tax
The county roll, 2025 to 2026
What the county says this parcel is worth, 2026 against
2025. The upper bar in each pair is 2026.
Almost all of the movement is in the land.
38% of the total change is the county
revaluing the dirt and only 62% is the
building, which fell slightly. That is a land reappraisal, not a judgement that the house got
better or worse, and it is worth knowing before treating the county’s number as an
opinion about the property.
Williamson CAD values the property at $387,192 for 2026, up 0.4% ($1,603) from $385,589 in 2025. Improvement value moved $4,103 and land −$2,500. Of the change, 37.9% is land and 62.1% improvement. The parcel changed +0.4% against a neighborhood median of −1.7% across 128 parcels, a larger change than 83.6% of them. The listing reports annual taxes of $7,037, 1.82% of the county market value.
WCAD
2026
2025
Change
%
Improvement value
$304,692
$300,589
+$4,103
+1.4%
Land value
$82,500
$85,000
−$2,500
−2.9%
Total market value
$387,192
$385,589
+$1,603
+0.4%
Against its peers
Change in total market value, 2025 to 2026. Bars to the left of the line fell; this parcel is in red.
Peer group
Parcels
Median change
103 Maria Ctthis parcel, R098324
—
+0.4%
NeighborhoodG242593F - Sierra Vista Sec 2
128
−1.7%
ZIP 78628
24,238
−3.1%
Georgetown
62,812
−3.5%
Williamson County
286,358
−4.6%
Measure, 2026
This parcel
Neighborhood median
Difference
Improvement value per SF124 comparable parcels
$144.82
$150.68
−3.9%
Click here for details
Where the values come from
What the roll is. Values are the Williamson CAD certified market roll for parcel R098324 (SIERRA VISTA SEC 2, BLOCK O, LOT 10): land plus improvement equals the total. They are the county’s mass-appraisal figures for taxation, not an opinion of this property’s market value. The roll’s total is not used as a value anywhere in this report. Its land component is used, and only for one purpose: the land section prices lot-size differences at this parcel’s own county land rate, and says so there. Nothing else in the valuation reads from the roll.
Splitting the change between land and building
“Of the change, X% is land.” Those two shares are of the
ABSOLUTE component movements, not of the net change:
|Δland| ÷ (|Δland| + |Δimprovement|) and the
same for improvement. Here land moved −$2,500 and improvement
+$4,103, which is why the shares can read as 95/5 while the net
change is smaller than the land movement alone. No exclusions are applied to the peer groups:
splits, new construction and parcels that changed use are all in them, which is part of why a
county median can fall while a settled neighbourhood rises.
Comparing this parcel with its peers
No interval is attached to any peer median. Each is the median of a
complete enumeration of that group’s parcels carrying both rolls — every parcel in
the neighbourhood, the ZIP, the city or the county, not a sample of them — so a sampling
interval would be answering a question nobody asked. The uncertainty that does exist is in the
appraisal itself: the county’s mass-appraisal model, its choice of neighbourhood codes,
and any parcel whose use or boundaries changed between rolls. None of that has a published
error, and none is invented here.
How the peer figures are built. Peer medians are the median percentage change in total market value between the 2025 and 2026 rolls across every parcel in each group carrying both years. “A larger change than N%” is the share of the neighborhood’s parcels whose change was below this parcel’s (10th–90th percentile −5.5% to +2.7%). Unit values compare land per acre and improvement per SF with the neighborhood median among parcels carrying those measures. Taxing units: Williamson CAD (CAD); City of Georgetown (CGT); Williamson CO (GWI); Wmsn CO FM/RD (RFM); Georgetown ISD (SGT).
The tax figures
The effective rate. Annual taxes are as reported on the listing; the effective rate divides them by the county market value, before any exemption the owner holds, so a buyer’s bill can differ.
The annual tax figure on the header, in full. The county market value of
$387,192 for 2026, as assessed by WCAD, multiplied by the
combined rate of 1.82%, gives $7,037. The
combined rate is the sum of every jurisdiction levying on this parcel — county, city,
school district and any special district — which is why it is quoted as one number and
not attributed to any one of them. Two things move a real bill away from it: an exemption the
current owner holds, which is not carried to a buyer automatically and in some cases not at
all, and a reassessment, since the market value shown is the roll for 2026 and the
roll is set once a year. The figure is what the parcel would be taxed at on today’s roll
with no exemption, which is the only version of it that is comparable between properties.
The arithmetic
Notation and formulas. Let Mt,
Lt and It be the roll’s market, land
and improvement values in year t, with Mt = Lt + It.
The change is Δ%M = 100(Mt/Mt−1 − 1), and the
same for each component. Land’s share of the 2026 total is
L/M = 21.3%. The
effective rate is τ = annual tax ÷ M2026 = 1.82%.
For peer group G the figure is
mediank∈G 100(Mk,t/Mk,t−1 − 1) over parcels
carrying both rolls, and the rank is the share of neighbourhood parcels whose change was smaller than this
parcel’s.
Assumptions and limitations. The roll’s market value is the district’s
mass-appraisal estimate as of January 1 of the roll year, produced by schedule across every parcel; its accuracy
for a single parcel is not published (districts are tested in aggregate, by ratio studies, not parcel by parcel).
It is not the taxable value: a homestead’s appraised value may rise by no more than 10% a year under the
Texas Tax Code, and exemptions reduce the taxable value further, so a bill does not follow the market-value
change one for one. The annual tax is the listing’s figure — the current owner’s bill under the
current owner’s exemptions — and a buyer’s bill is computed on the buyer’s own. Peer
comparisons are produced only for Williamson CAD parcels with both rolls on file.
Market data & statistics
Everything here describes the market around this property rather than the
property itself: how long sales take, how prices have moved, and what a buyer is competing
with today.
The market this property sits in
ZIP 78628 · single-family homes · through August 2026
Ten measures of this market are tracked, from closed MLS sales only:
how many homes sell, what they fetch outright and per SF, how long they take, how
much of the first asking price survives, how often a seller pays part of the buyer’s
costs and how much, how often the price is cut before it sells, how much of the competition
is a builder, and how wide the spread around the middle sale is. Over the last
36 months ZIP 78628 carried
4,236 sales, a median of
119 a month, and the underlying trend in price per
SF has been running at about
−3.5% a year. At today’s 573 homes for sale and the
recent selling rate, it would take 5.0 months
to clear what is on the market.
The full set — every chart, every definition, and the same measures for
the subdivision, the ZIP code, the city and the county — is a separate report you can
open, share or keep:
Opens in this window. Measured from closed MLS sales, read when this
report was built.
Click here for details
In plain terms
Every number on this page
comes from homes that actually sold near this one, grouped by the month they sold, and
reported as the middle sale of that month rather than the average — so one unusual
house cannot move the line. Prices are what the seller kept after paying anything toward
the buyer’s costs.
What was measured
Every number above is drawn from closed sales of
single-family homes in ZIP 78628, taken from the MLS record of each sale, grouped by
the month the sale closed, and reported as the middle sale of that month rather than the
average.
Why the middle and not the average. The average of nine ordinary houses and
one mansion is a number that describes none of the ten. The median — the middle sale, half
above and half below — does not move when one unusual house sells, which is what makes it
readable month to month. The one place an average is used is the share measures, where the
question is literally “what fraction,” and there the average is the fraction.
Which geography, and why. The choice is made by measurement rather than
preference. The rule is to take the tightest geography whose typical month carries at least
25 sales, and to widen only if it does not. What the candidates carried here:
Sierra Vista — a median of 10 sales a month,
111 over the period
ZIP 78628 — a median of 119 sales a month,
4,236 over the period — used
Georgetown — a median of 251 sales a month,
8,782 over the period
Williamson County — a median of 852 sales a month,
29,879 over the period
The county is the largest and the least relevant: a median that pools Leander, Hutto and
Taylor describes a market this property is not in. A census tract is the opposite mistake
— roughly five sales a month, where a single unusual house moves the median by a fifth and
every line on this page would be charting its own sampling error. A ZIP code sits where the two
curves cross: local enough to mean something about this address, large enough that a monthly
median is a measurement rather than an anecdote.
Net, not gross. Where a price appears it is the net figure: the
closing price less any closing costs or repair credits the seller agreed to pay. That is what
the seller actually received. Every valuation figure in this report is net for the same reason,
and charting a gross market against a net valuation would invite a comparison between two
different quantities.
Days on market is the cumulative figure where the record carries one,
counted from the day the home first came to market. The plain days-on-market field restarts at a
price change, so a house that has been available for seven months and cut its price last week
reports seven days. Using it would make a slow market look fast.
The three measures no public market report carries. Seller-paid closing
costs, price cuts before sale, and the builder share of closings. They are here because in this
market they are not marginal: over the period charted above, 49%
of sales in the most recent month involved the seller paying part of the buyer’s costs, and
a concession is a discount that never appears in the sale price. A seller comparing their asking
price against those closing prices is comparing it against numbers that were quietly reduced
after the fact.
What each measure is computed from.
Sales closed — a count of records whose status is Closed with a
closing price above zero.
Median net sale price — the middle value of the net sale price.
Median net price per SF — the middle value of net sale
price divided by living area.
Median days on market — the middle value of cumulative days on
market, where that value lies between 0 and 1,095 days.
Sale price as a share of the first asking price — the middle value
of closing price divided by the original list price, not the last one. Measuring
against the last asking price would hide every reduction, which is the thing being
measured.
Share at or above the asking price — the fraction of sales whose
closing price met or beat the original list price.
Share where the seller paid the buyer’s costs — the fraction
of sales recording seller-paid closing costs above zero. A sale that records nothing is
treated as a sale with no concession, which is the conservative reading: an unrecorded
concession would push this figure up, never down.
Size of that payment — the middle amount, among only the sales that
recorded one. Including the zeros would answer a different question.
Share that cut the price — the fraction whose original asking price
was above its final asking price.
Share newly built — the fraction flagged as new construction in the
listing record.
The middle half — the 25th and 75th percentiles of net price per
SF, drawn month by month across the whole period rather than folded into two years,
because the question is how wide the band is, not how this year compares with last.
Assumptions, and where they could be wrong. A median drawn from a month with
few sales is less certain than one drawn from a busy month, and the charts above do not show
that uncertainty band; the sales count in the first chart is the guide to it. New construction is
taken from the listing record, and a builder who lists through a brokerage without setting the
flag is counted as a resale. Concessions are recorded by the listing agent after closing and are
known to be under-reported. The trend chart's final point is a part year, drawn dashed and
labelled, and it will move as the year finishes.
Source and currency. ACTRIS MLS closed-sale records held in ALEX's warehouse,
read at build time. The most recent closing on file is 2026-09-08. The monthly series covers
36 complete months ending August 2026.
Competition
Other Properties for Sale
Five other properties
are for sale in Sierra,
asking $285,000 to $388,000 — every one of them, whatever its size.
Reference only:
they are not used in the valuation and carry no weight in
it. Nothing is left out for being larger or smaller than this house: the size standard governs which
sold homes may serve as evidence, which is a different question from what a buyer is choosing between this
weekend. Of these, no are larger than
this property and five smaller. Every figure in this report comes from closed
sales, and these have not sold — an asking price is a seller’s opinion of
value, not a measurement of it. They are shown as context for a decision, and you can view
them with Diane.
They appear on the map below as
blue diamonds on dashed lines.
Listing
Distance
Asking
Living area
$/sf
Built
Days on market
103 Maria Ctthis property
—
$419,900
2,104 SF
$200
1992
6
406 Tamara Dreast
0.21 mi
$300,000
1,688 SF
$178
1994
8
625 Luther Dreast
0.31 mi
$380,000
2,050 SF
$185
1995
19
306 Debora Dreast-north-east
0.32 mi
$285,000
1,690 SF
$169
1999
8
302 Debora Dreast-north-east
0.34 mi
$388,000
1,893 SF
$205
1996
202
303 Pin Oak Drnorth-east
0.43 mi
$380,000
2,034 SF
$187
1986
89
Editing copy — sheet and report.Editable text is outlined in grey and lights up as you pass over it. Gold boxes are agent entries. Figures, charts and controls are locked.Nothing here saves by itself — press Save when you are done.